W0: A dVLM-Based GUI Agent with Block-Diffusion Mode Steering
Additional data & models are released on KMK040412 (Hugging Face).
Overview
W0 keeps a frozen screen-language backbone and bounded memory, decodes each UI action with a block-discrete diffusion head, and trains only a categorical mode selector with critic-free RLVR (MSPO).
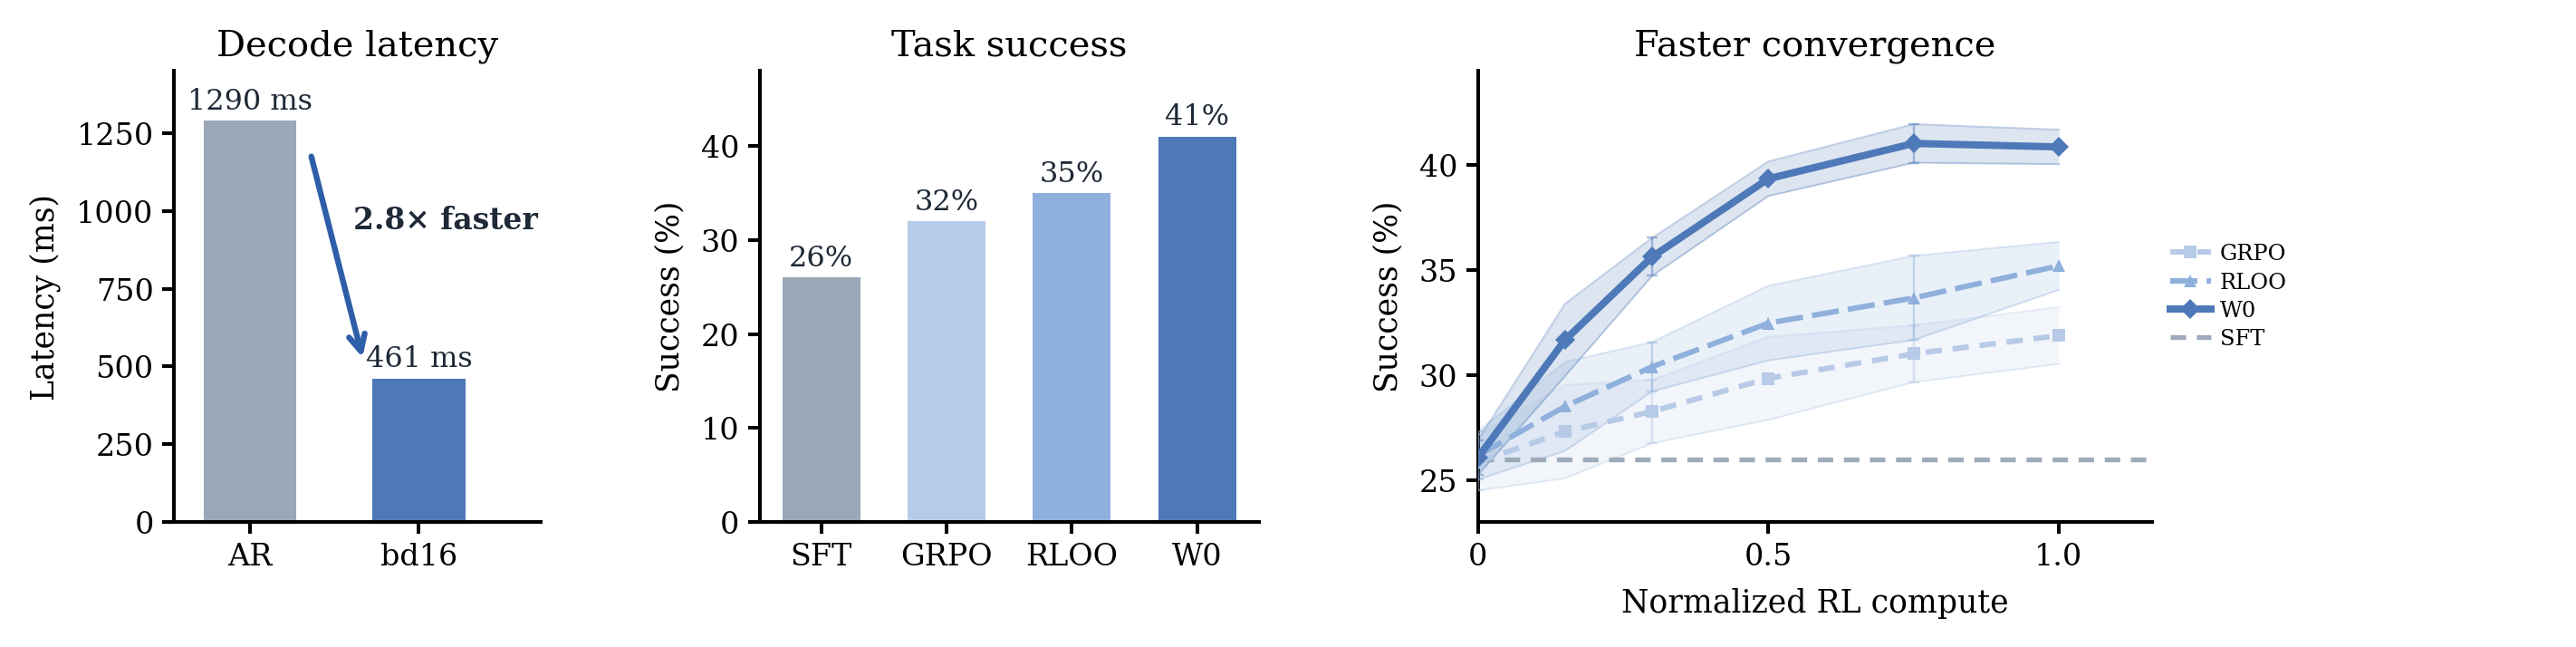
bd16, block-diffusion decoding cuts
per-chunk decode latency over an autoregressive decoder (~2.8×).
Middle: selector-only W0 reaches the highest GUI task success, above SFT and the two
critic-free RLVR baselines — GRPO and RLOO — applied to the full block-dVLM policy.
Right: W0 reaches that regime with fewer verifier-driven update rounds.
(Technical-report snapshot; numbers to be finalized.)
Block diffusion vs. autoregression
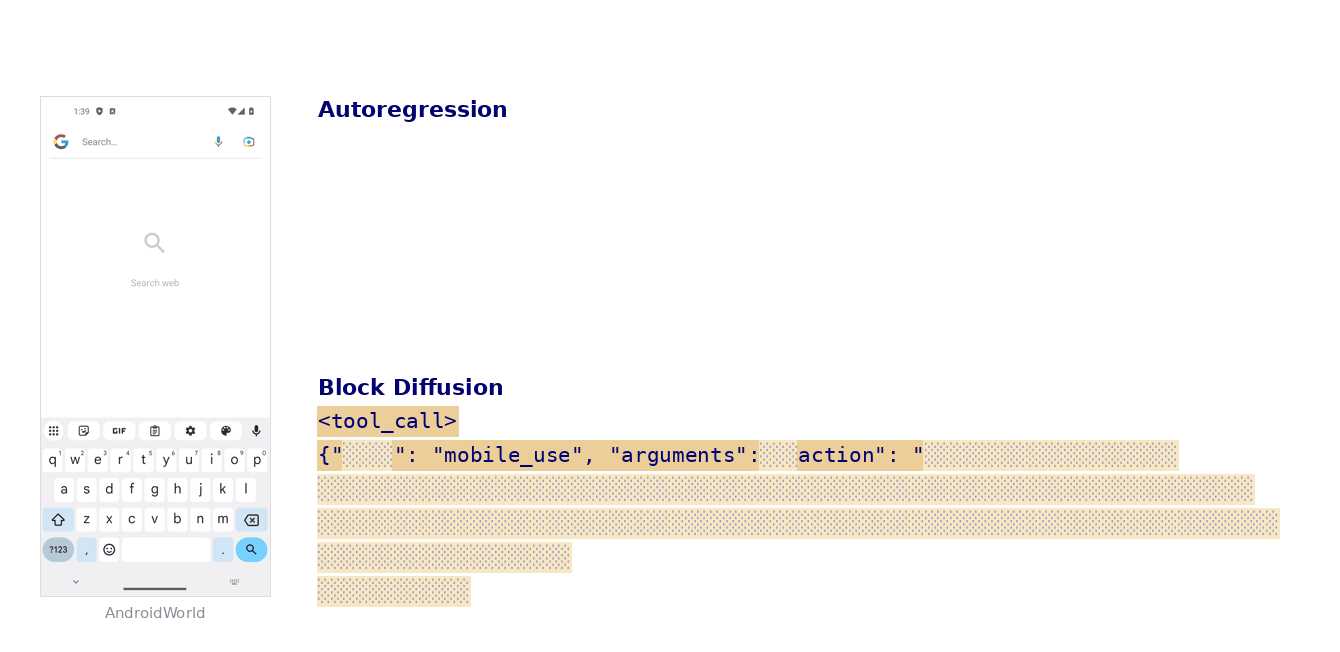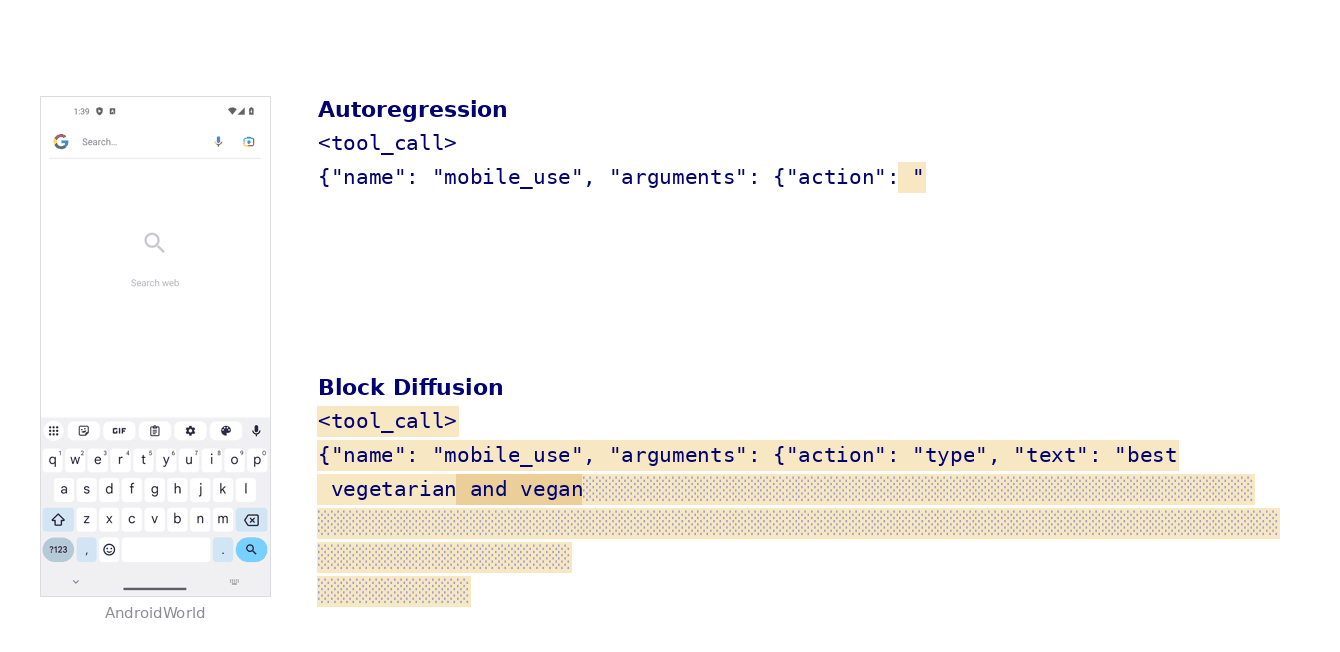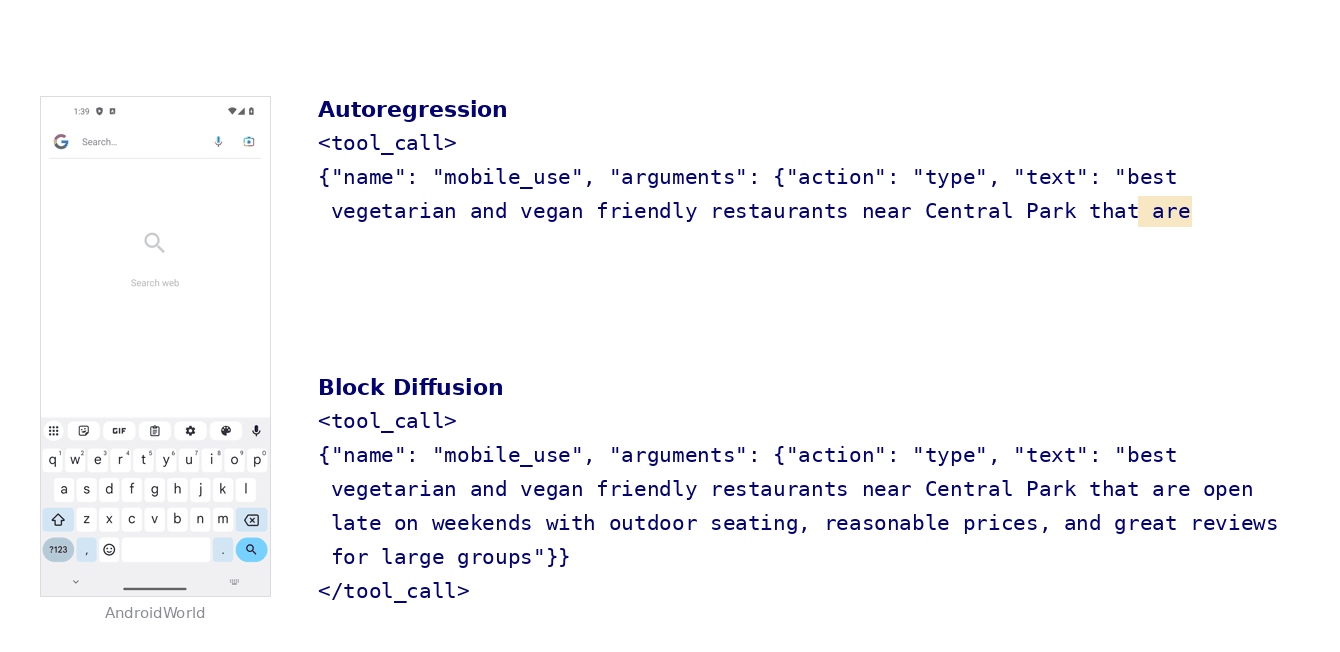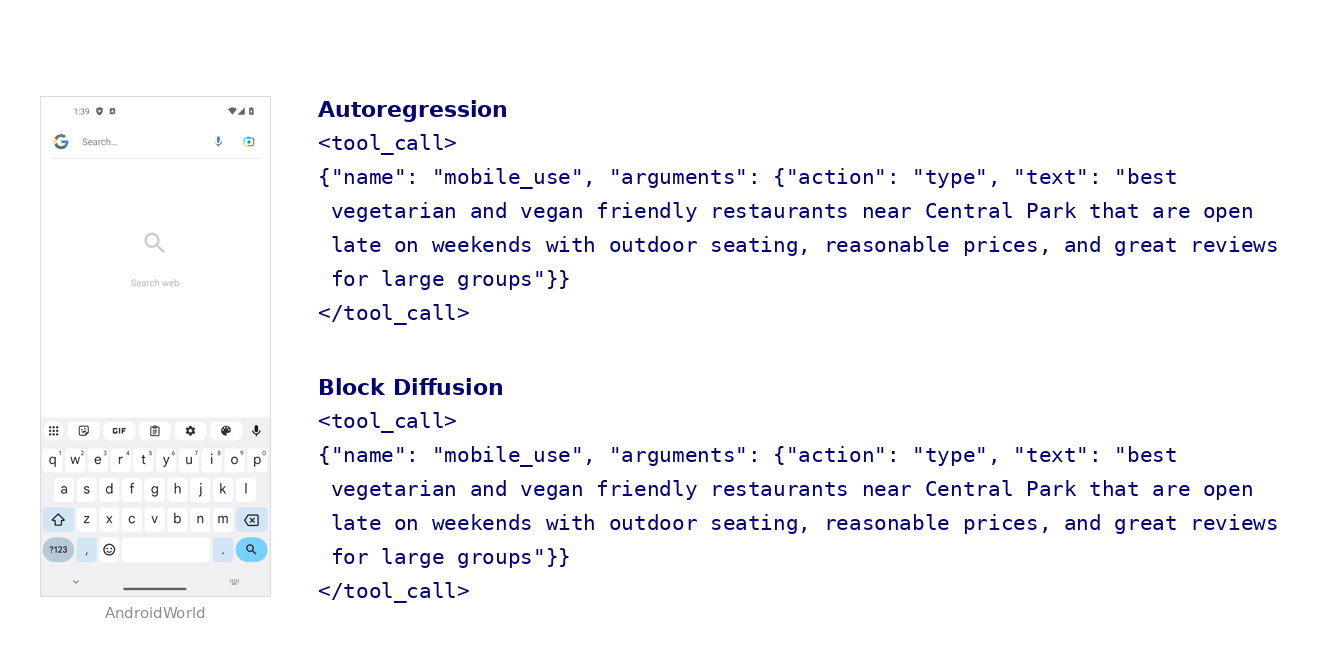
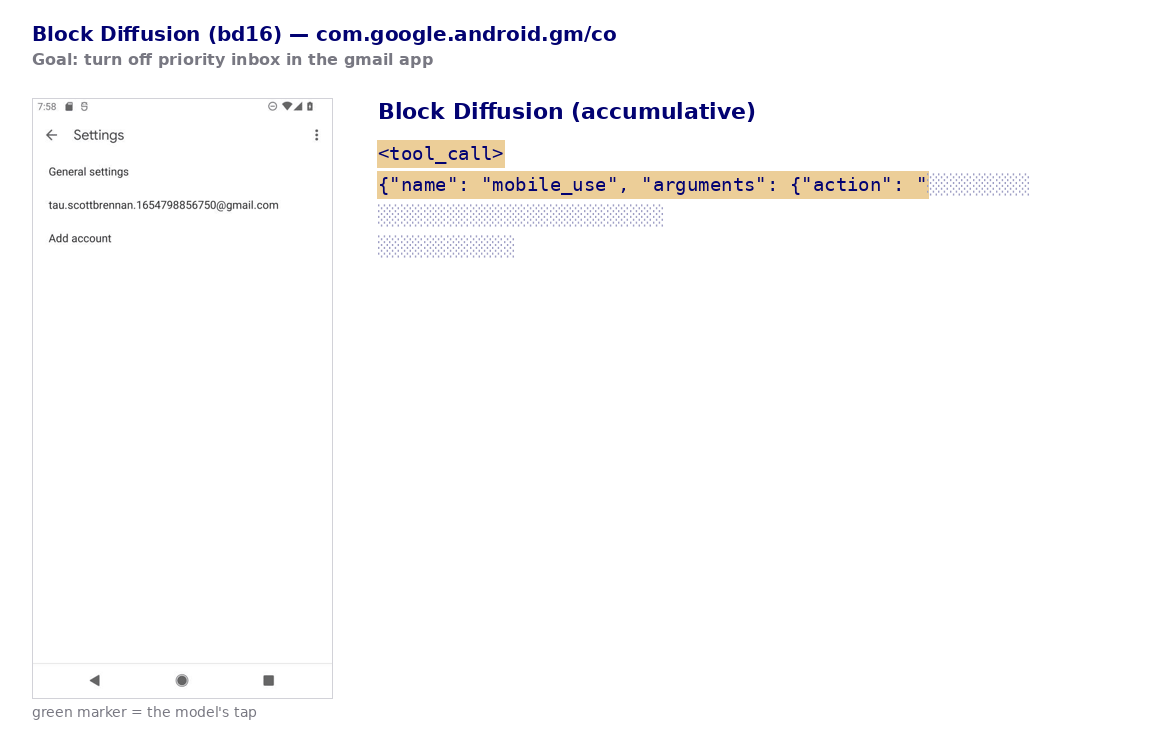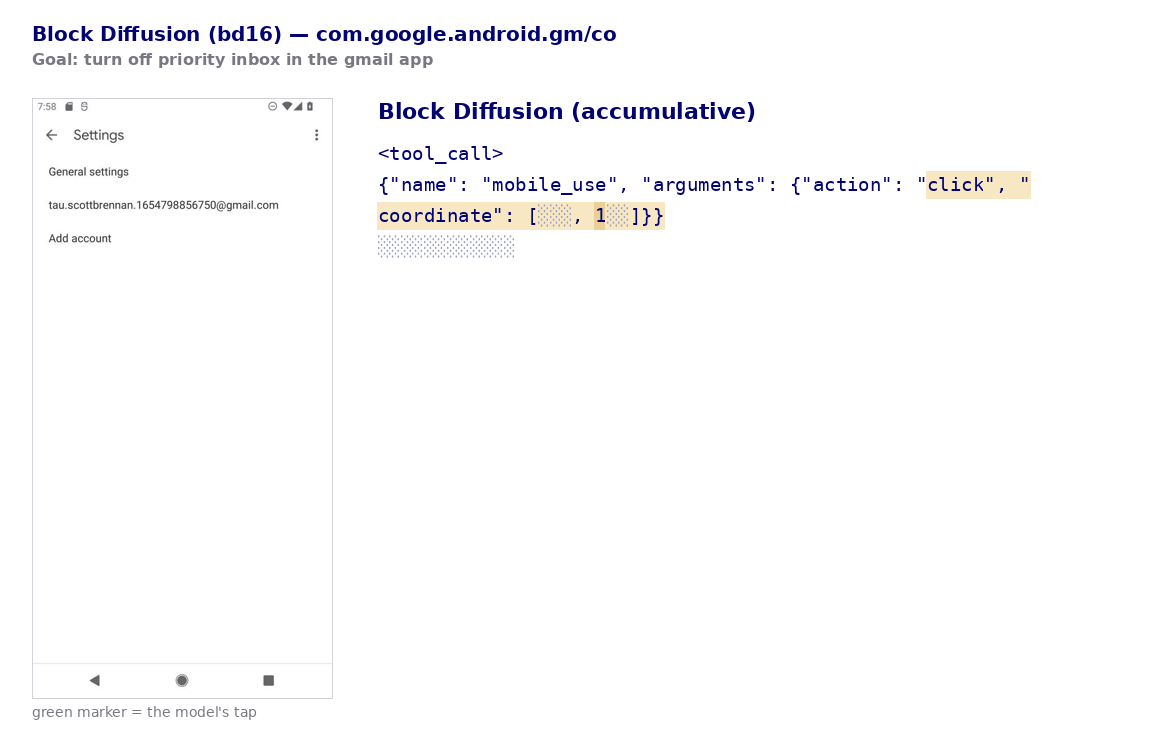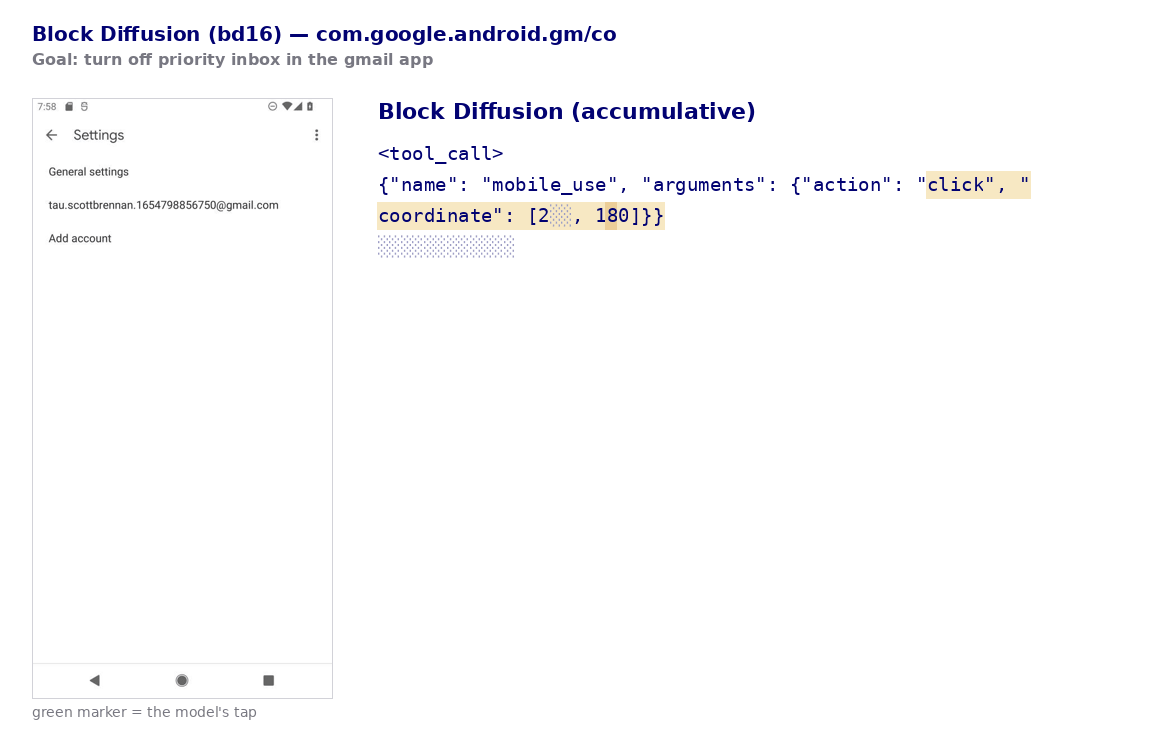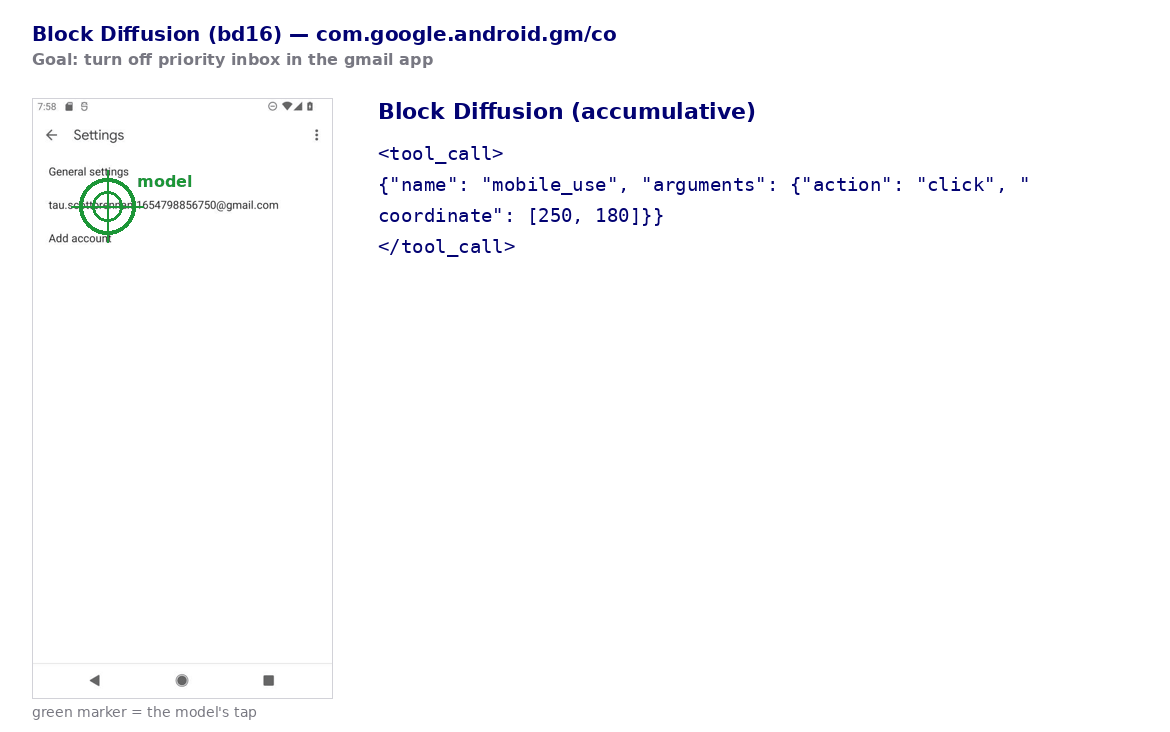
The same UI action, decoded two ways. Autoregression emits one token per forward pass; block diffusion denoises the whole action chunk in parallel — fewer forward passes, lower latency, at matched output.
Gmail action (with screen)
Action decoding (clean view)
Block diffusion fills the action in parallel — in this example ≈3.8× faster and ≈3.8× fewer forward passes (12 vs. 45 NFE), at the same decoded action.
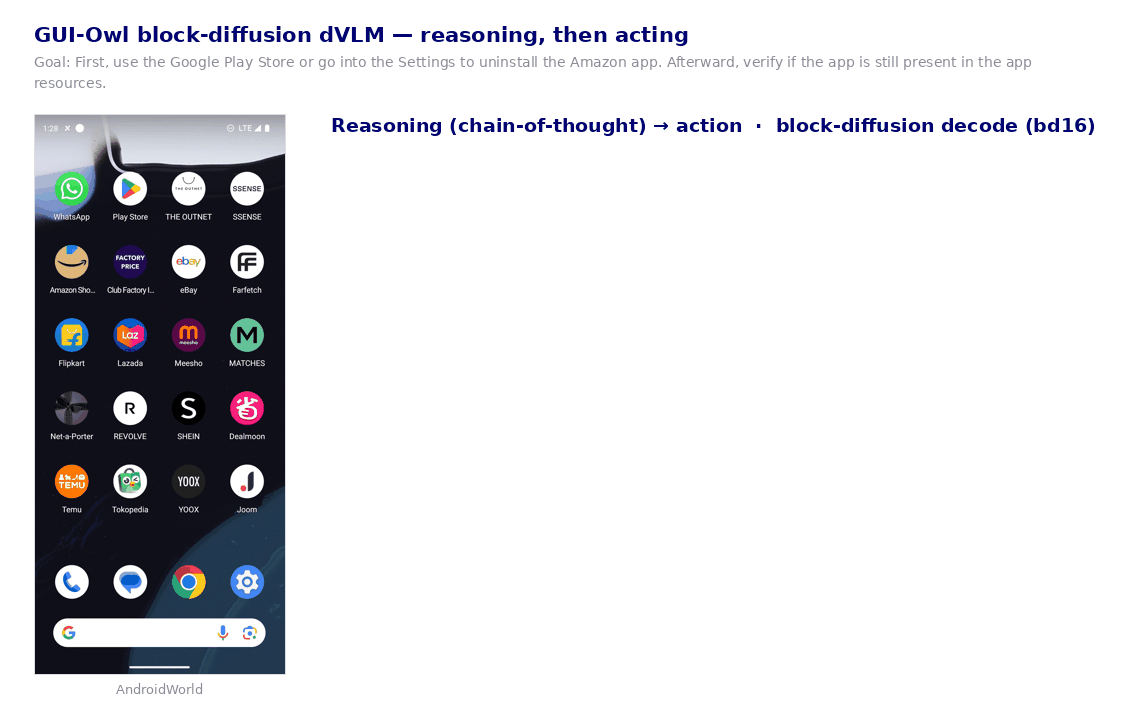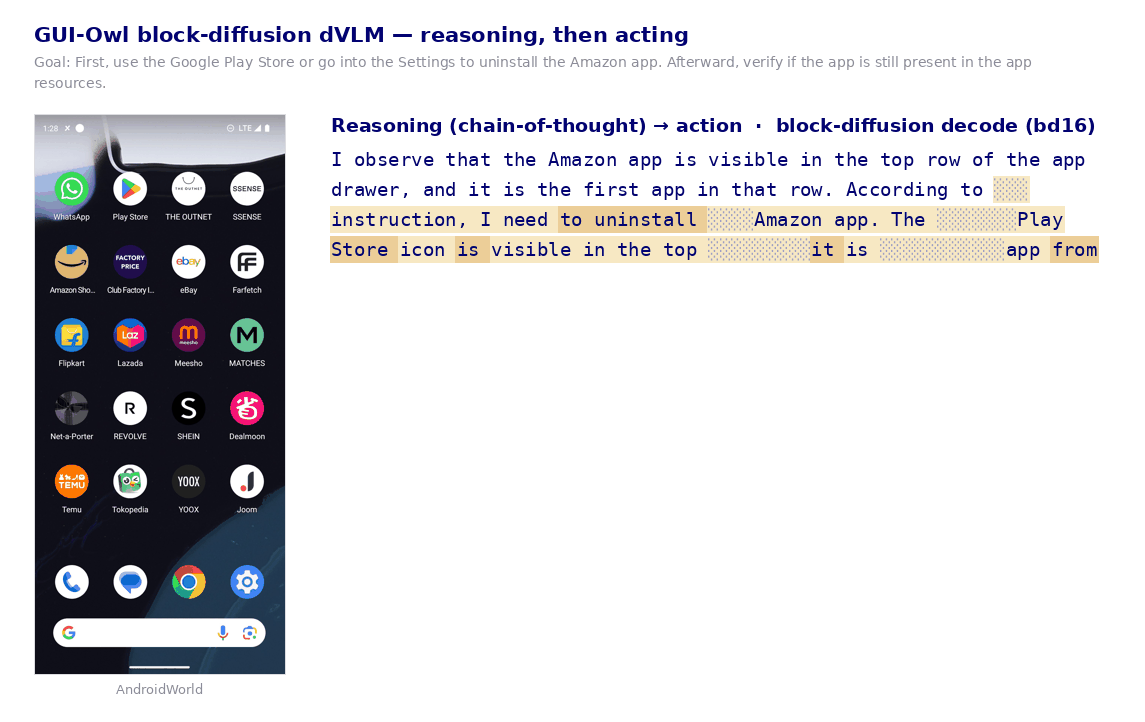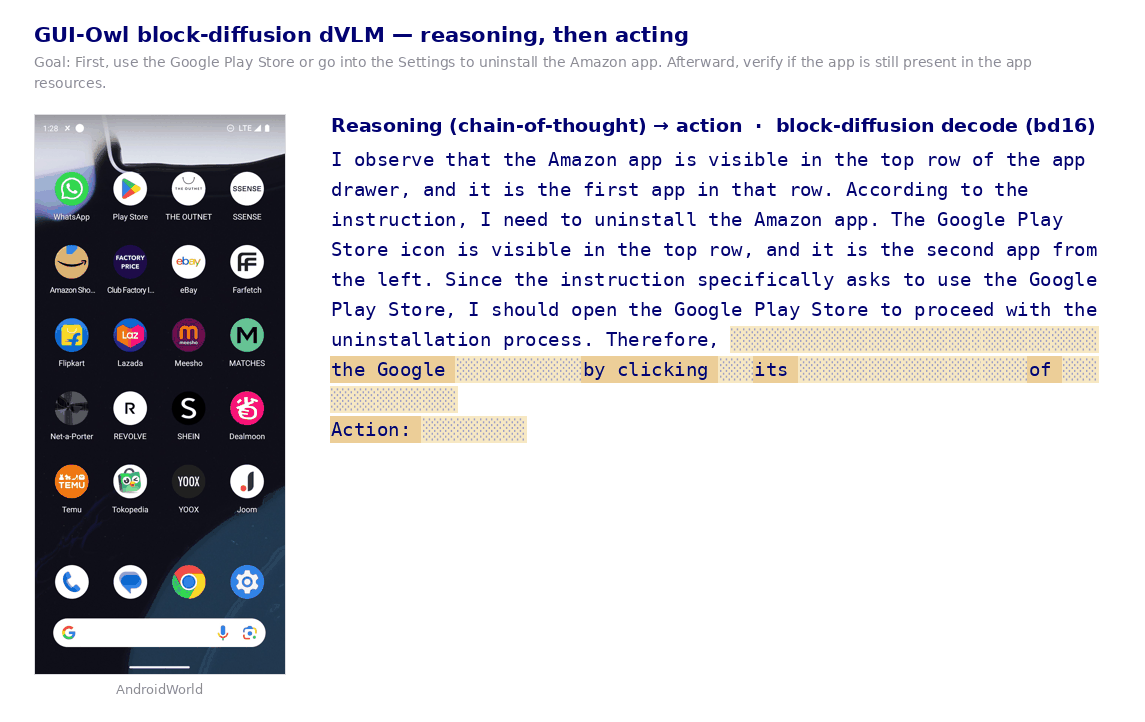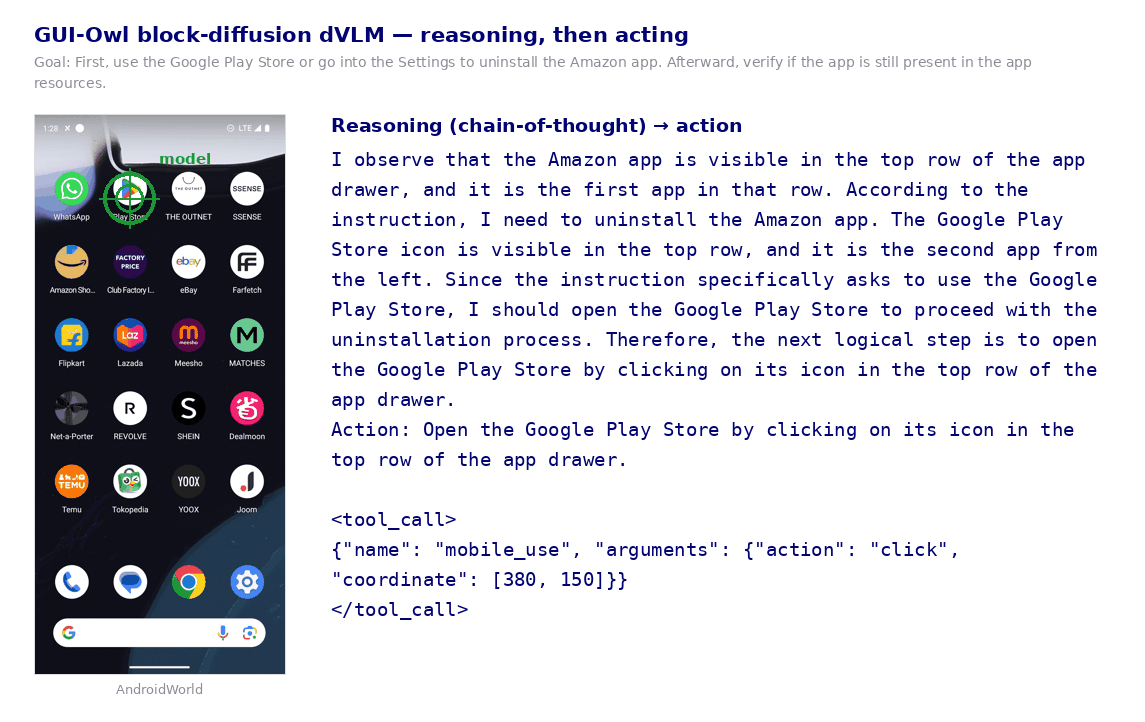
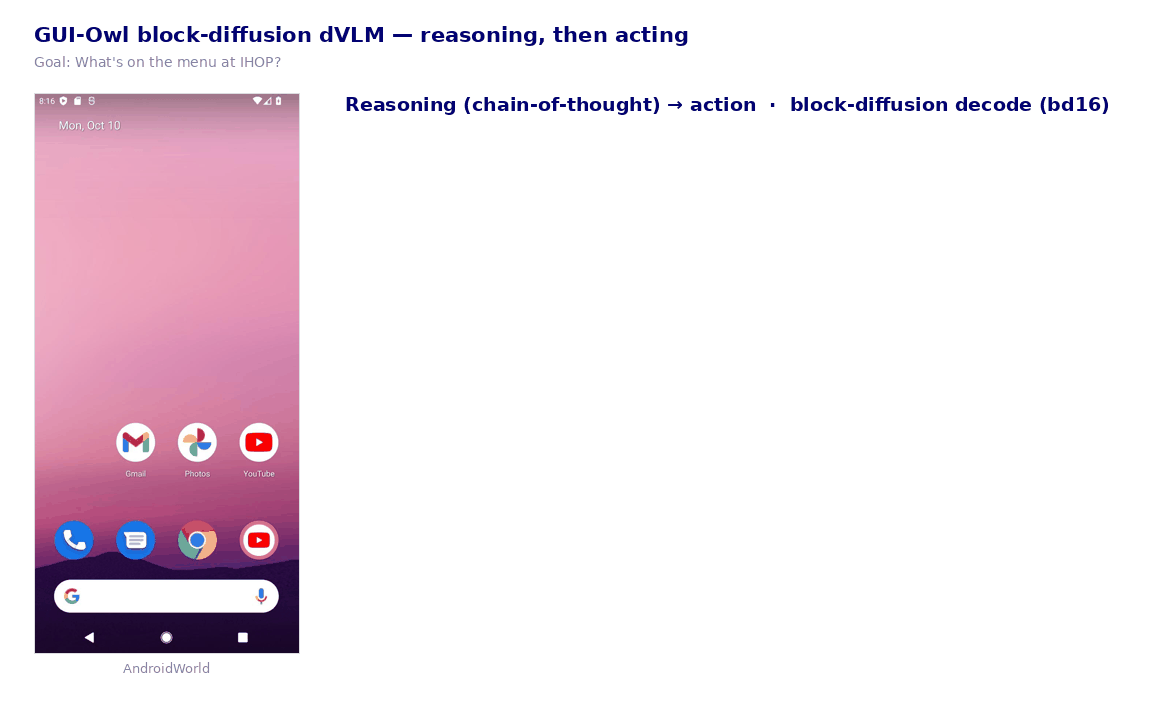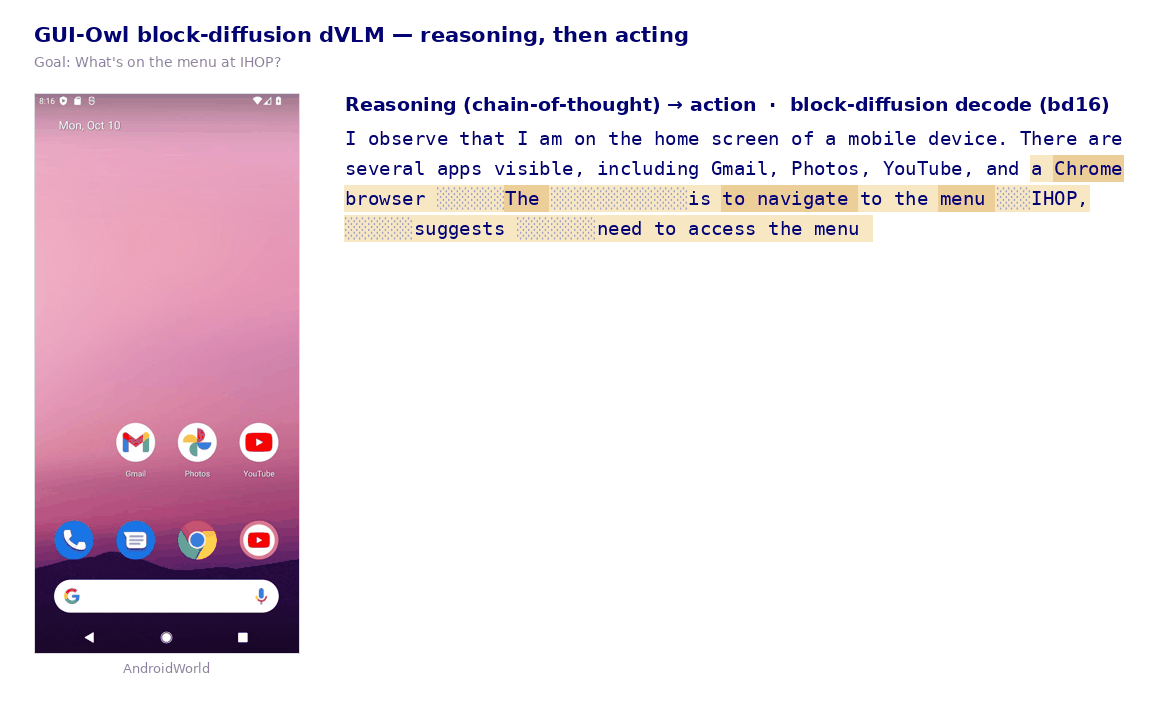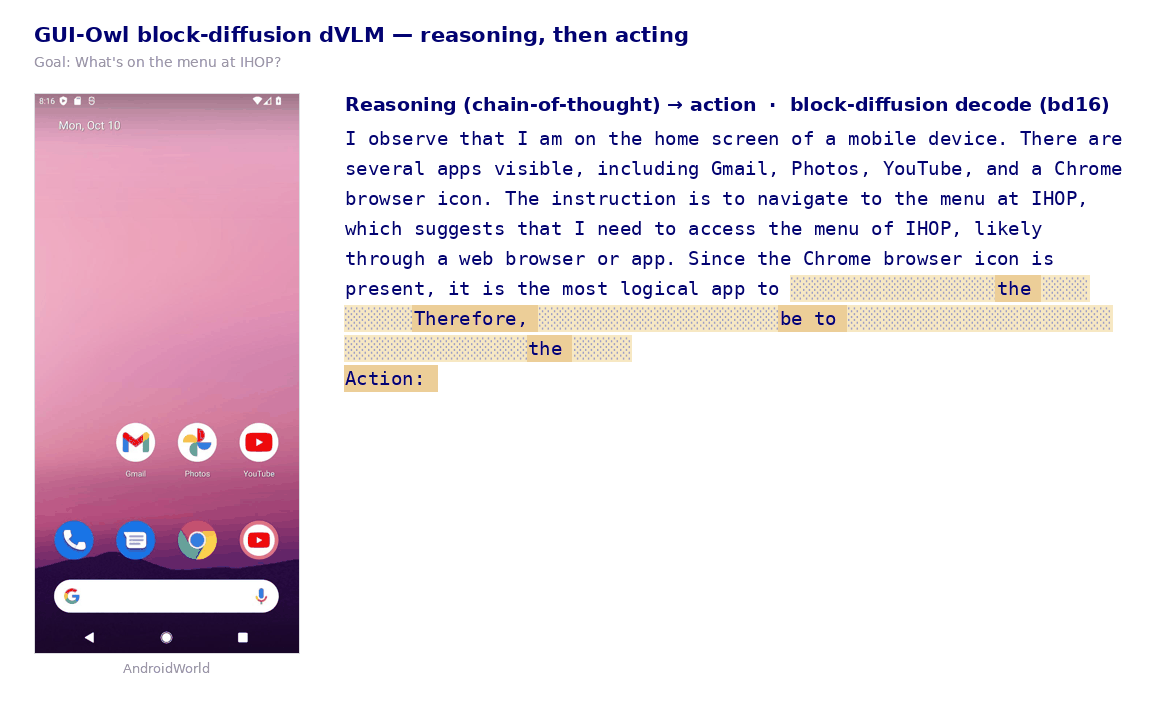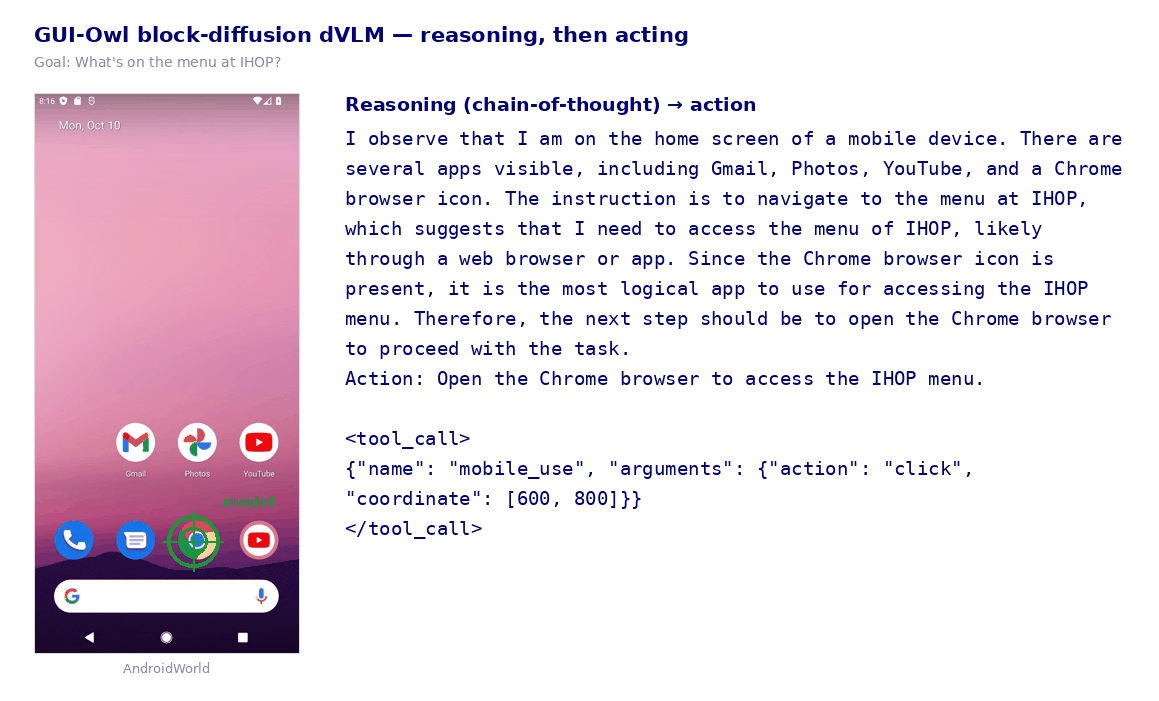
Reasoning, then acting
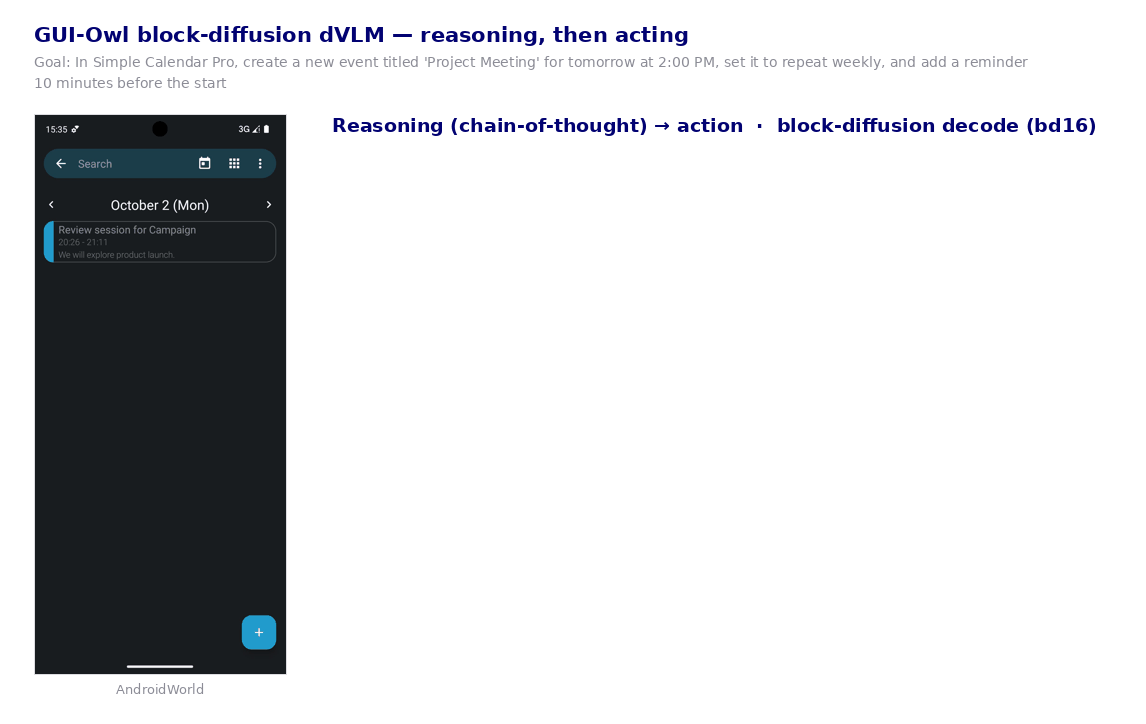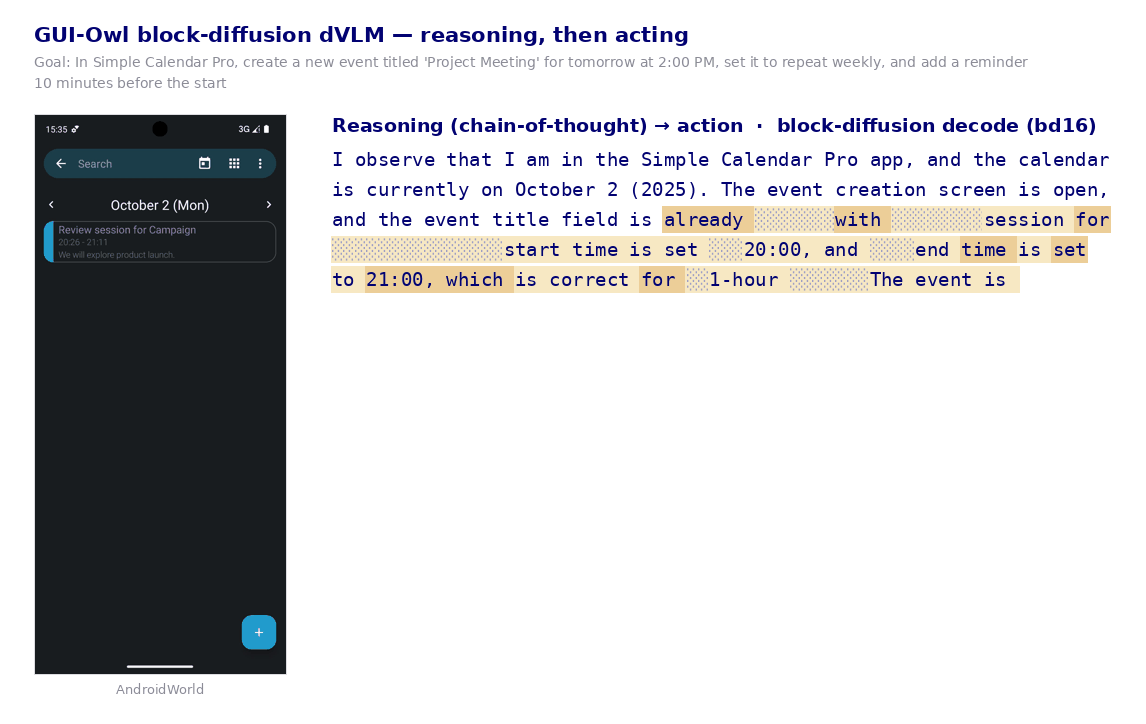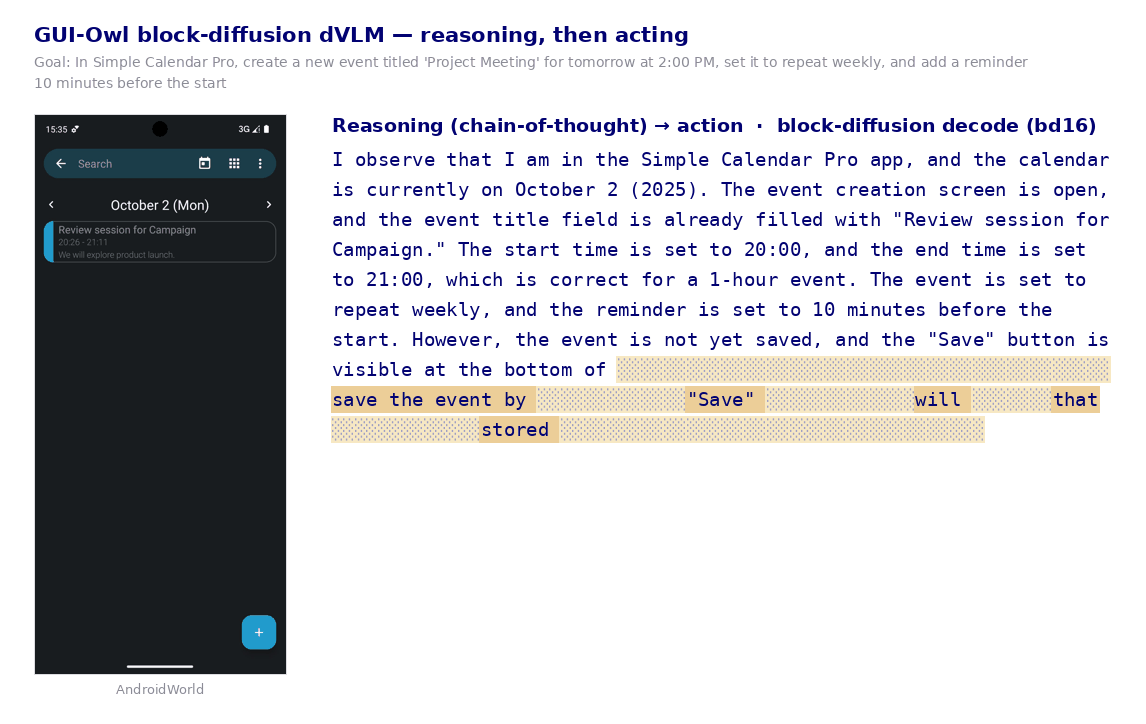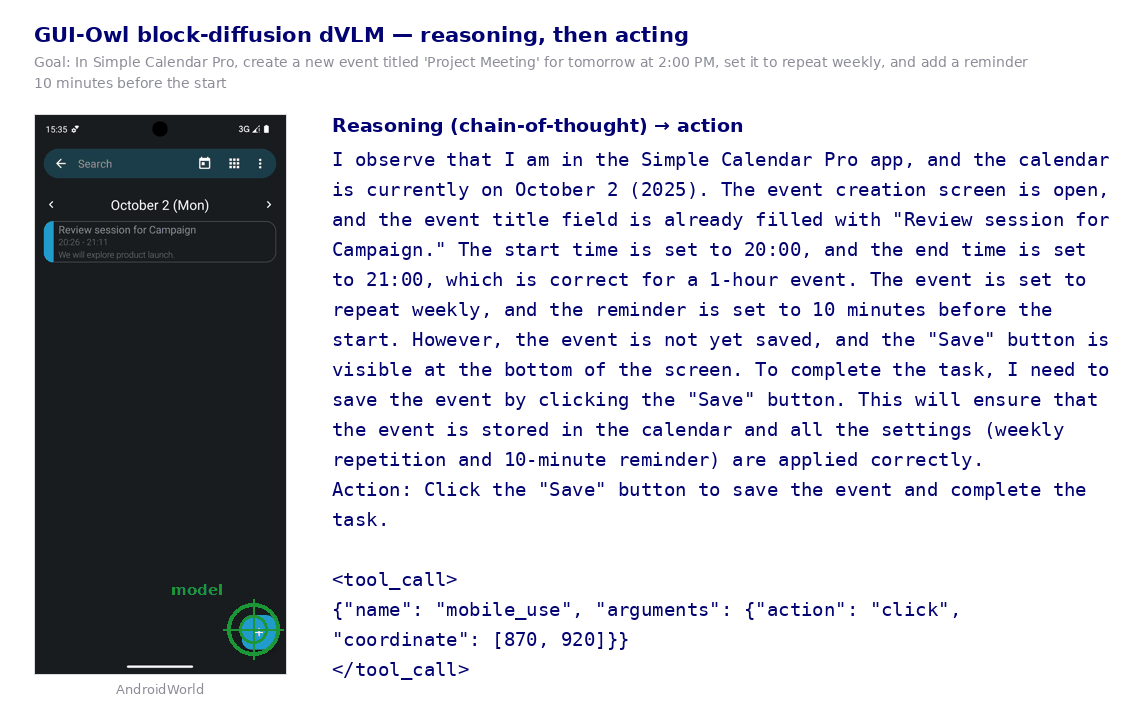
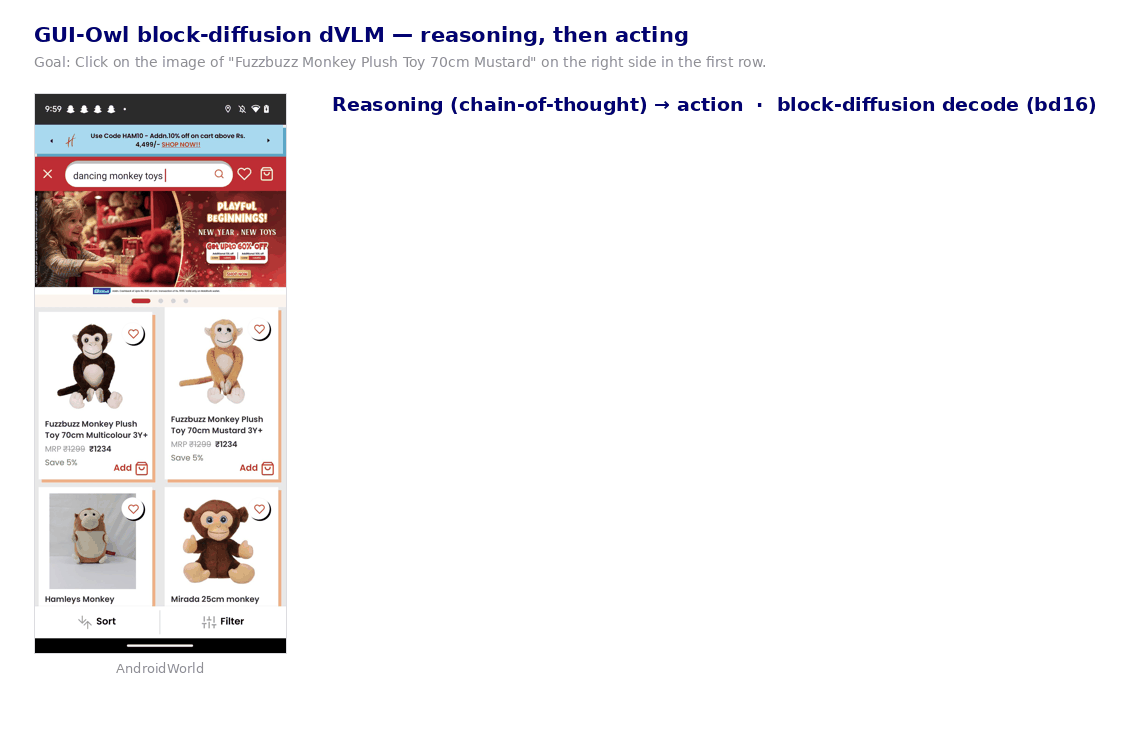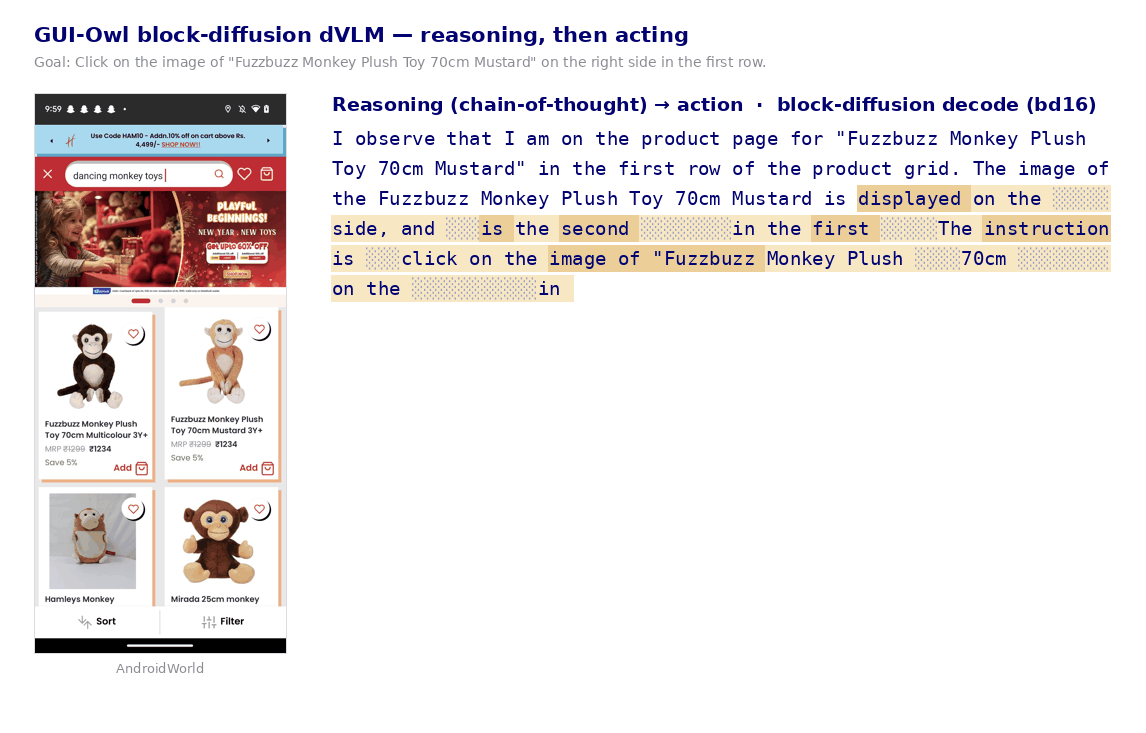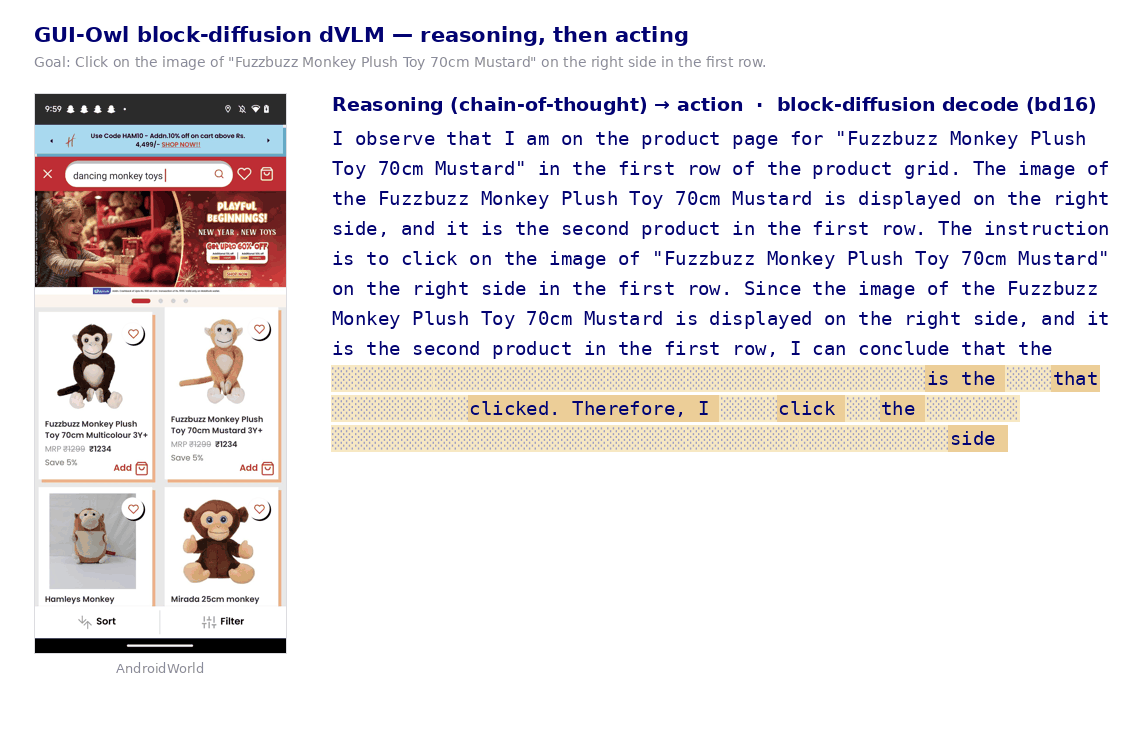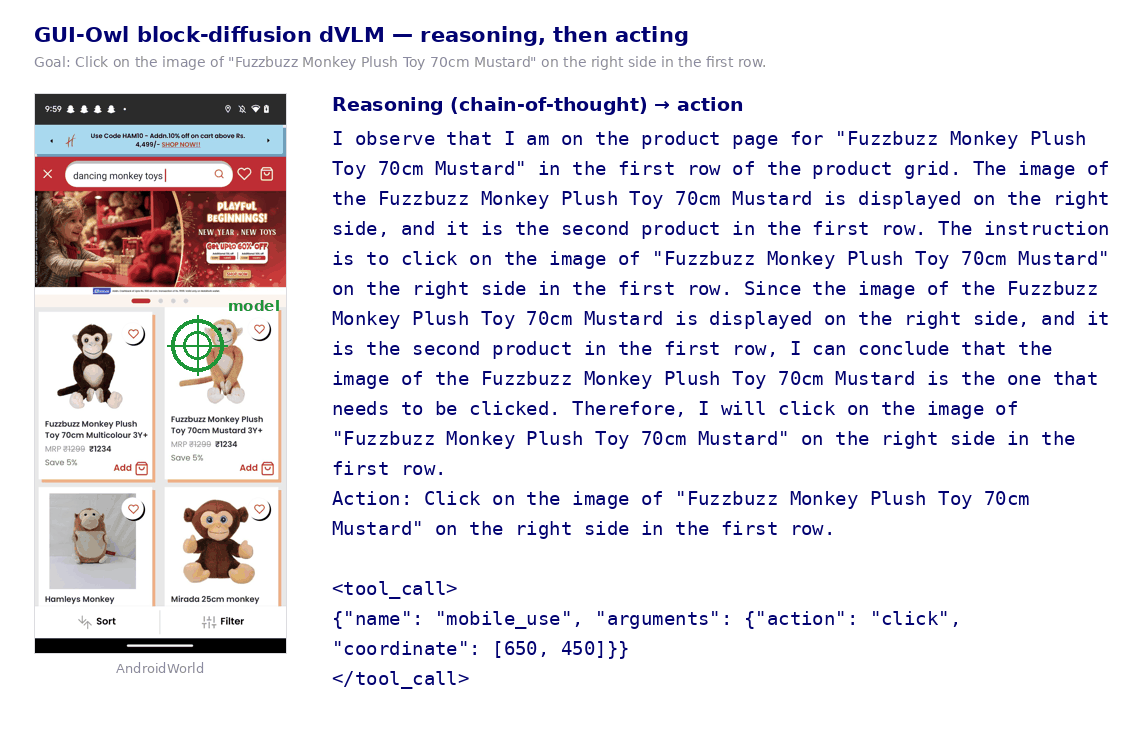
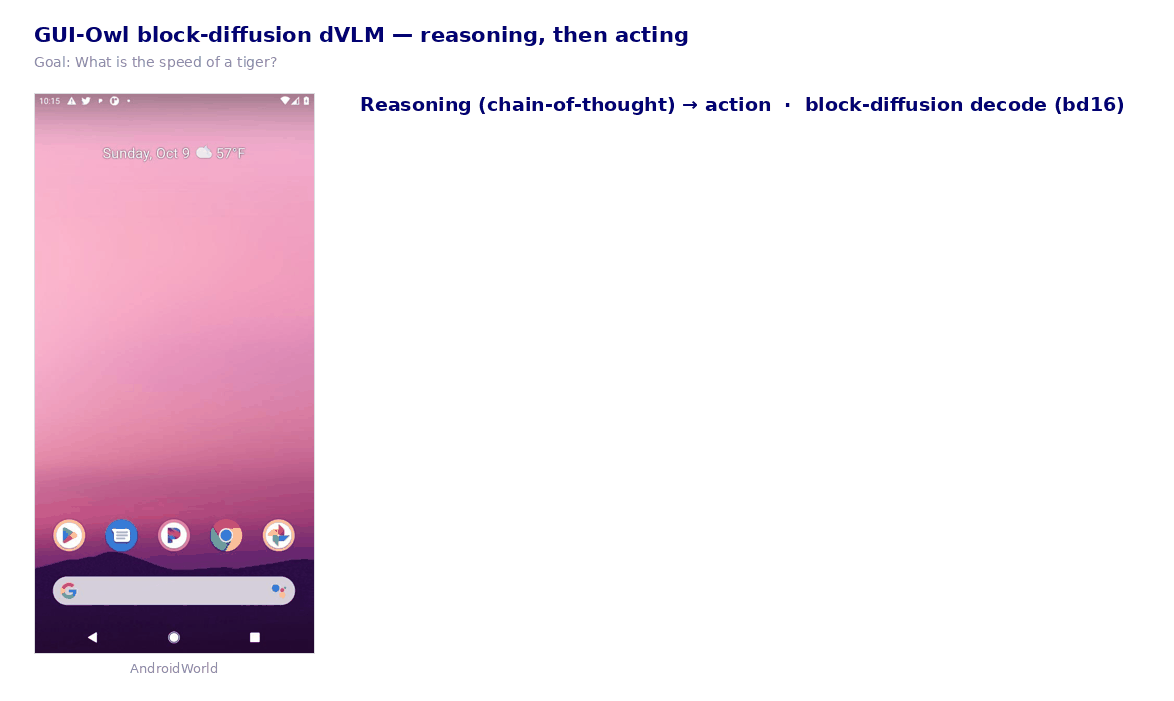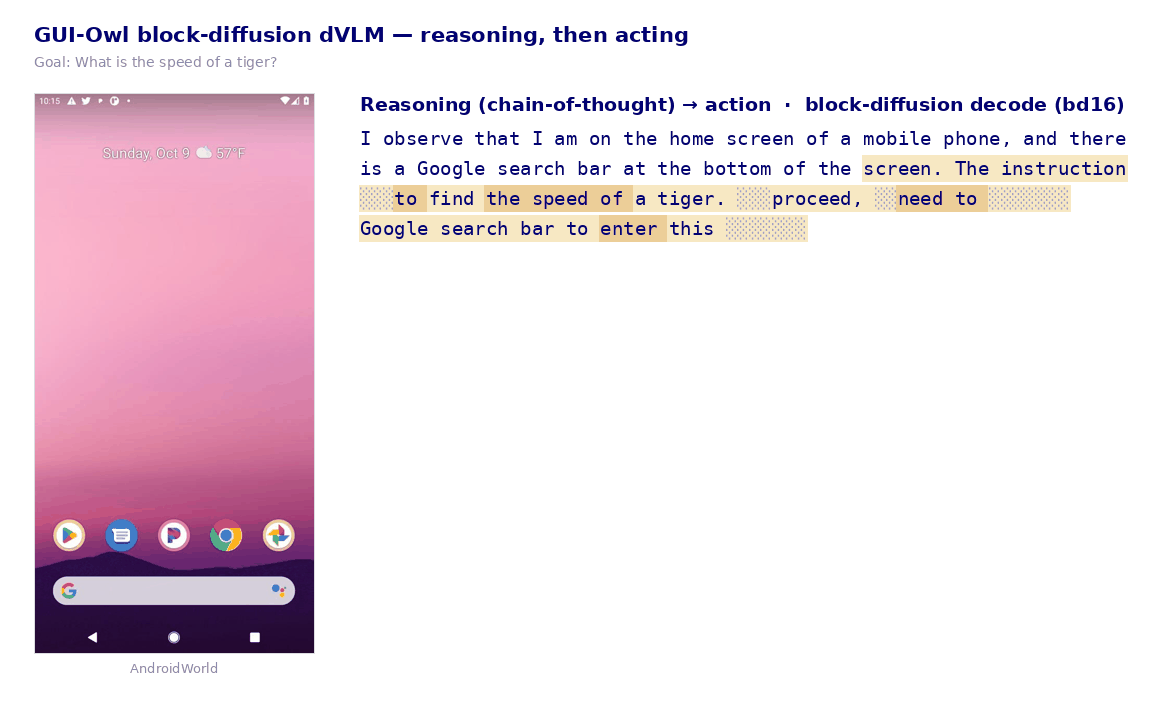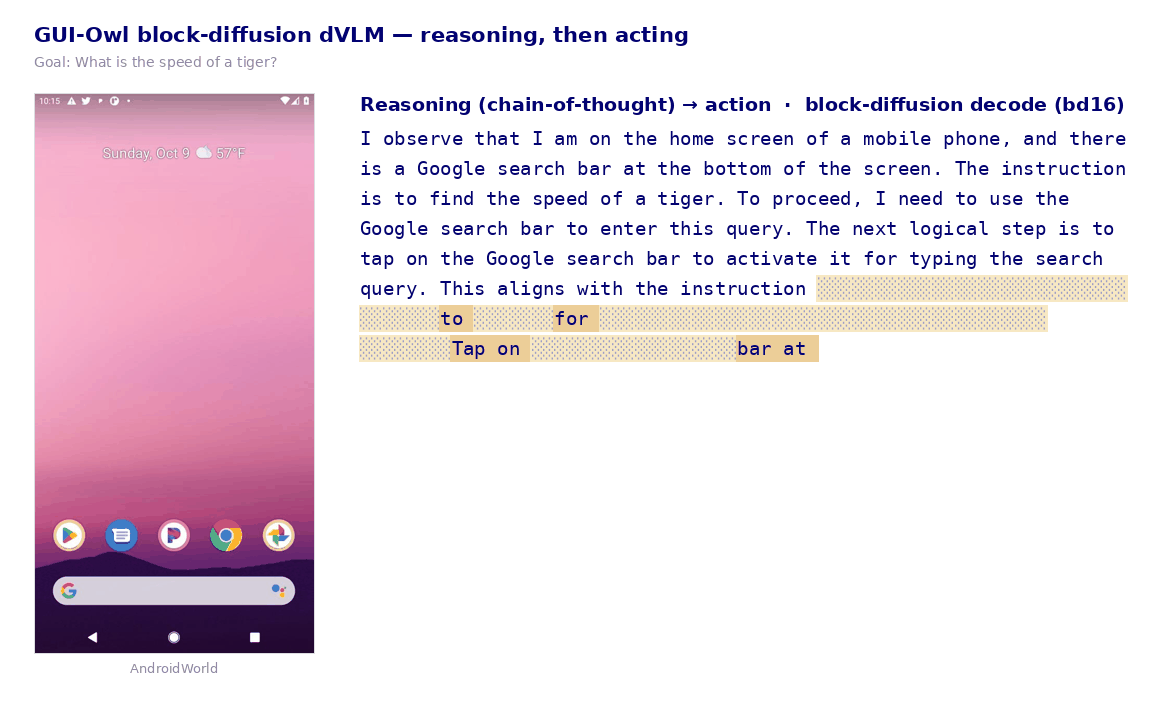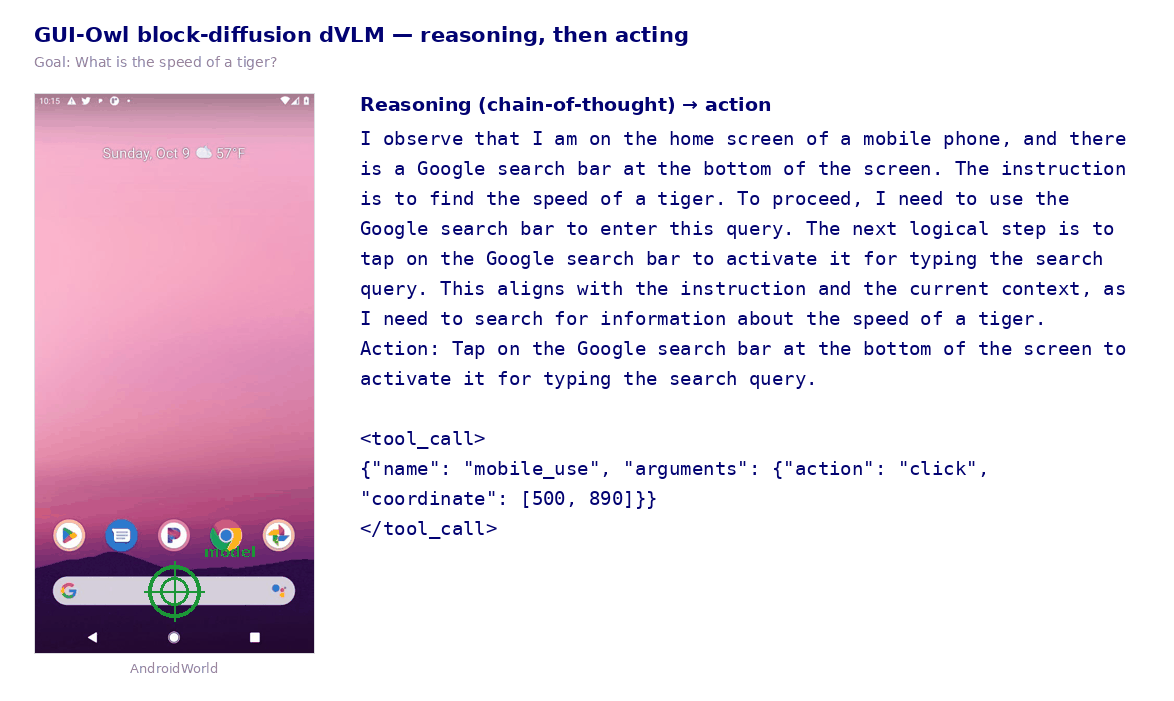
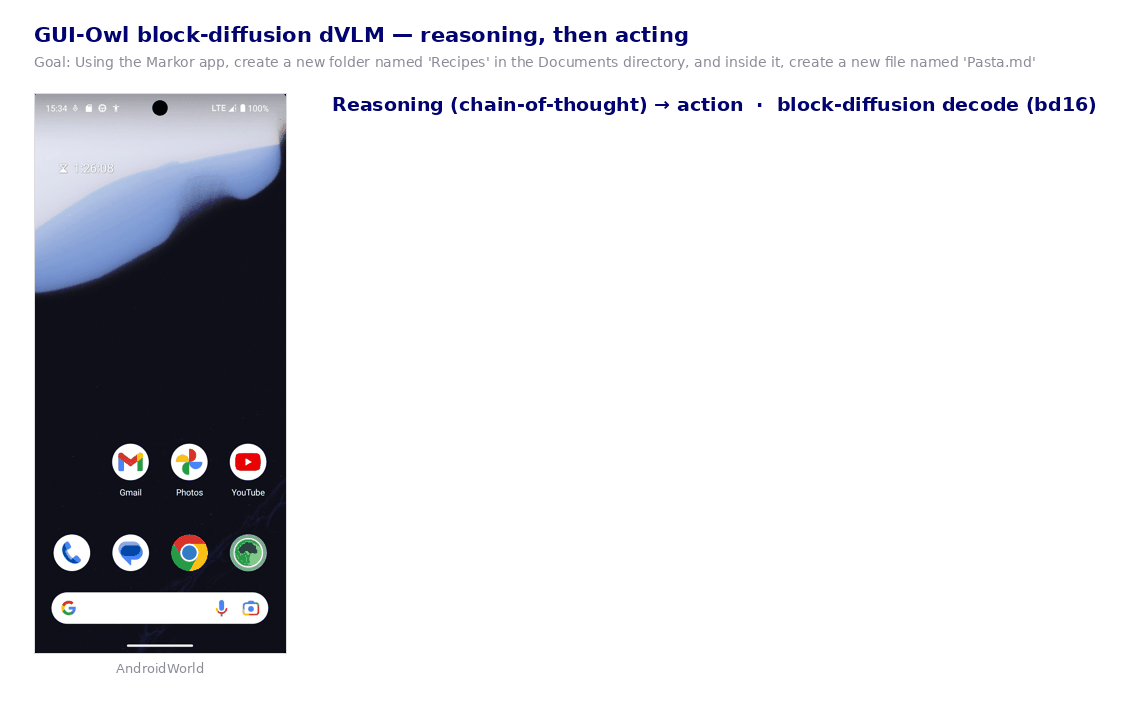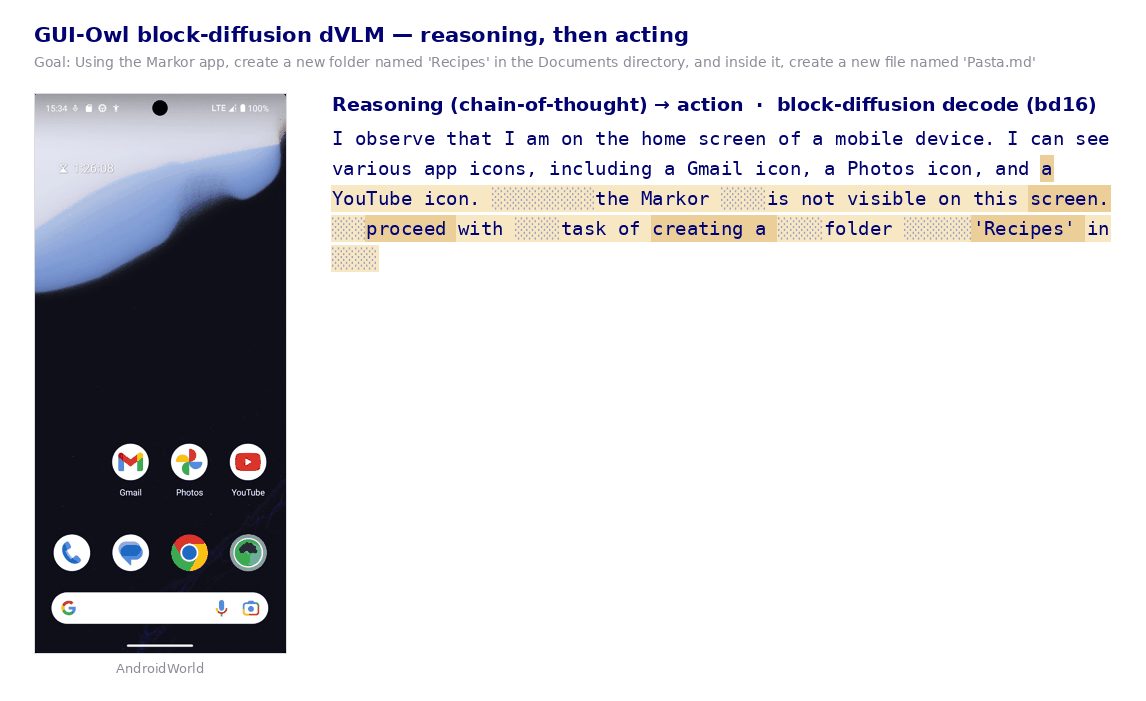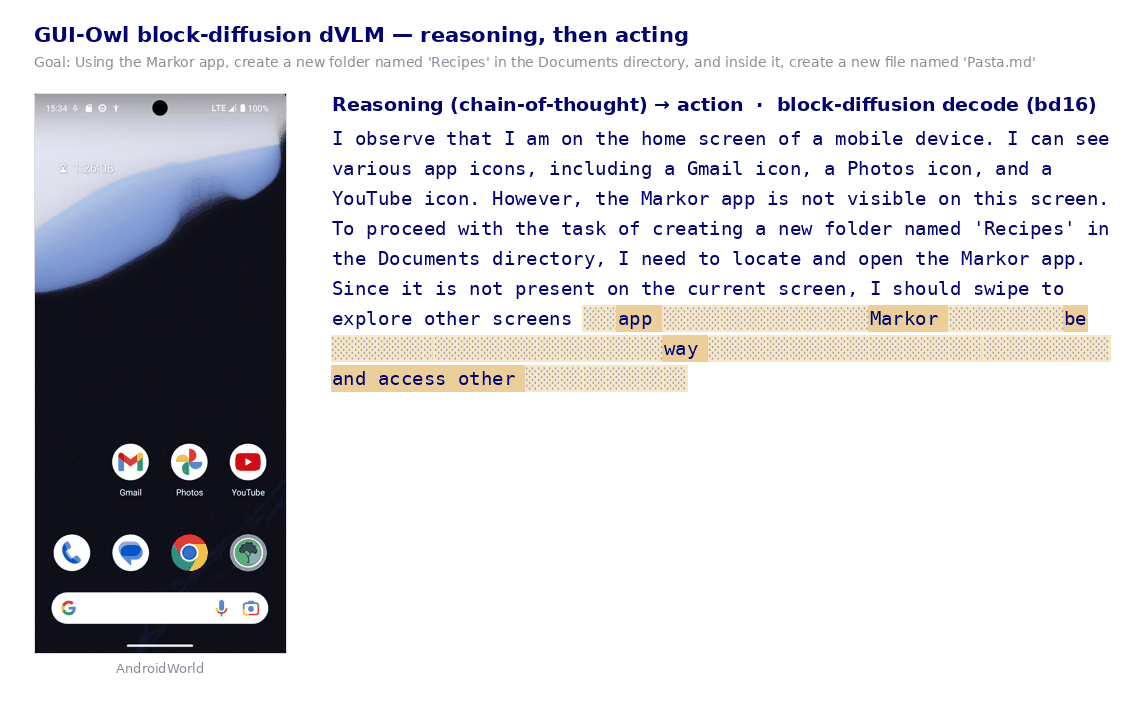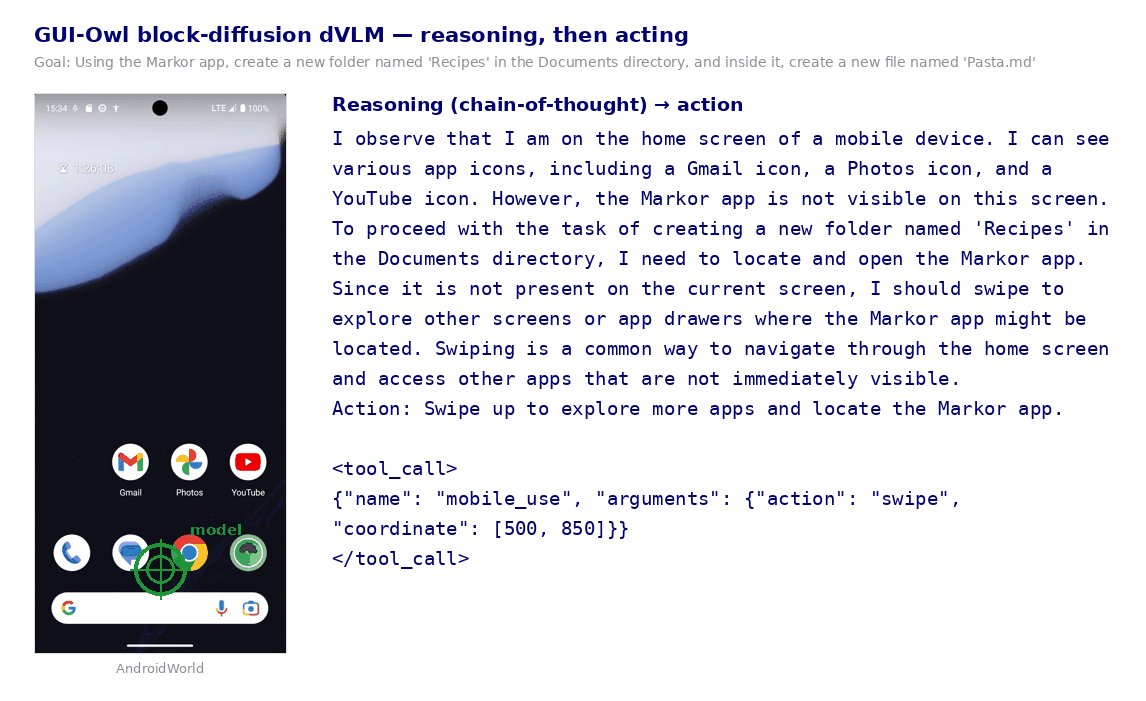
W0 can emit a chain-of-thought before the action. Each example decodes the reasoning and the action as block diffusion on a live AndroidWorld screen. Each clip shows the task goal, the decoded reasoning, and the model's tap on the screen. Click any example to enlarge and read the full reasoning.
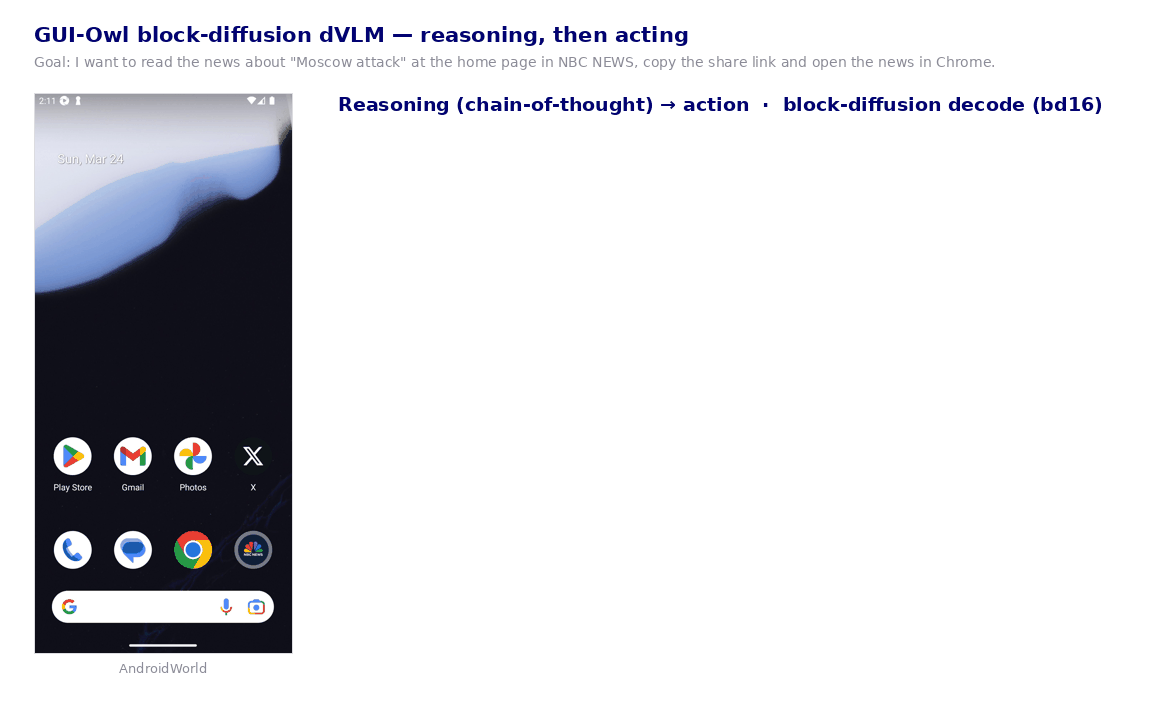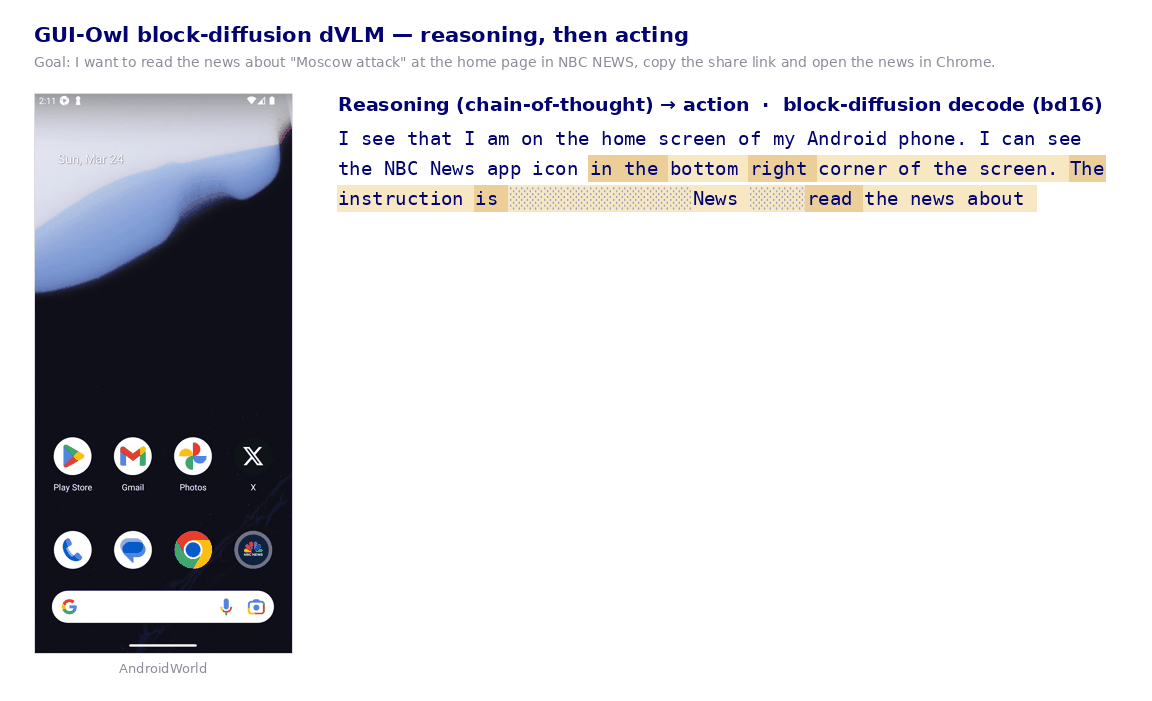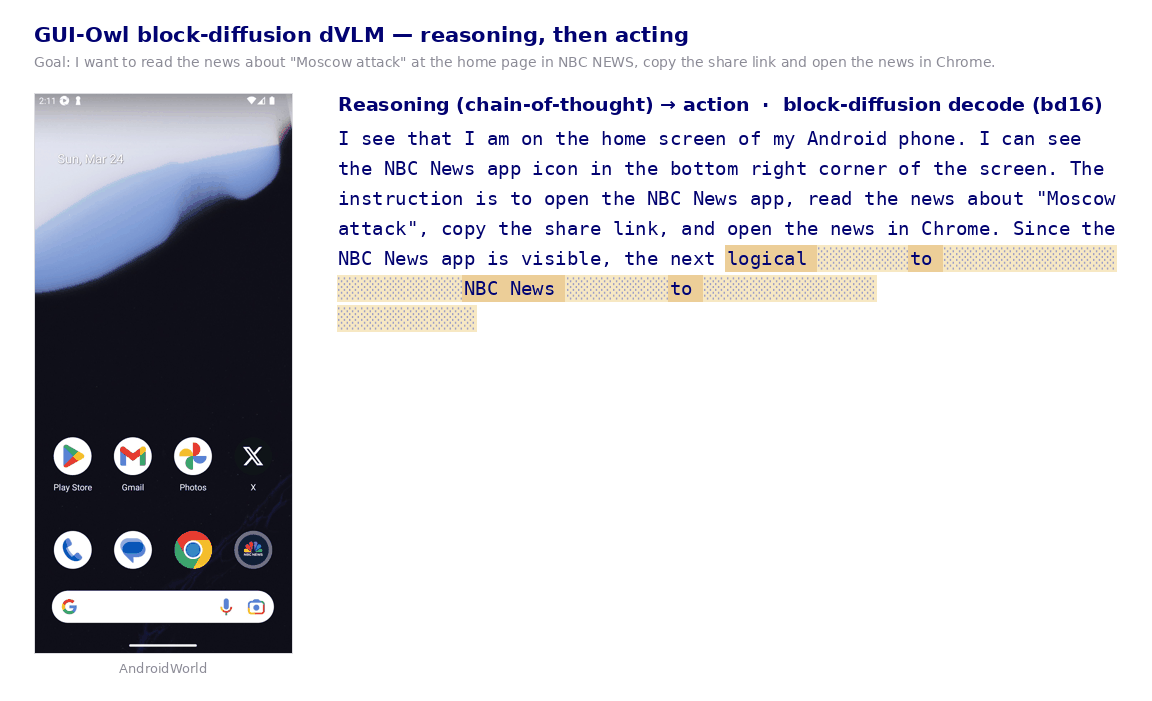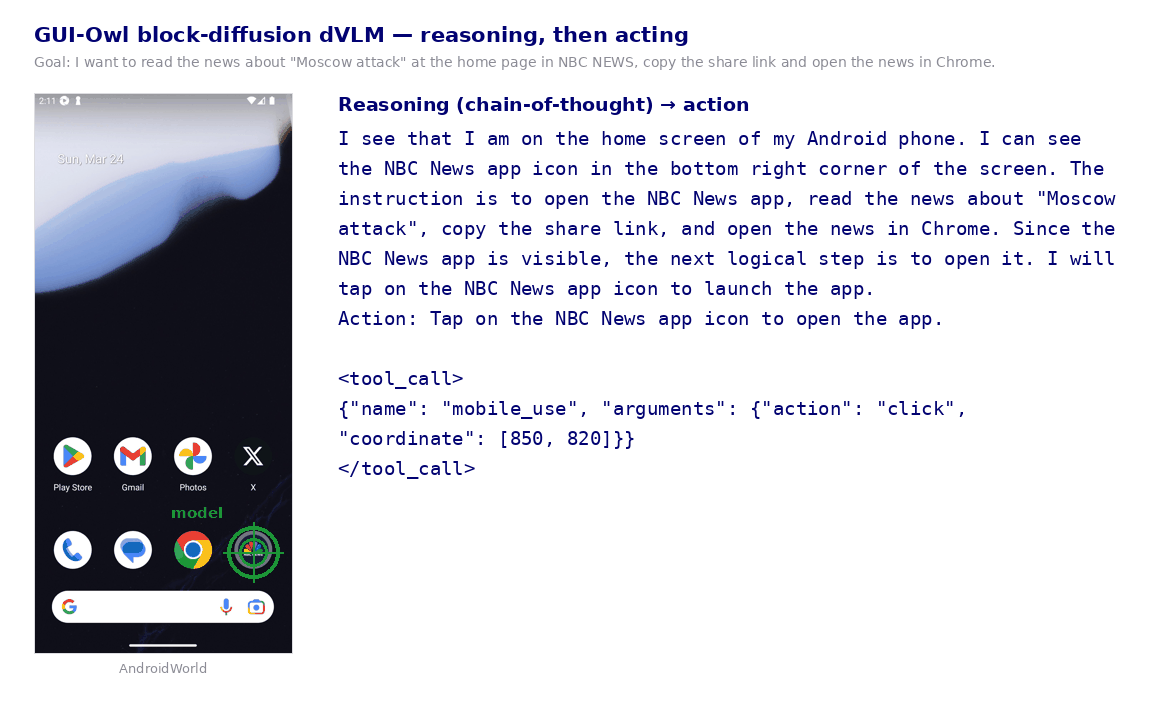
One-step decoding
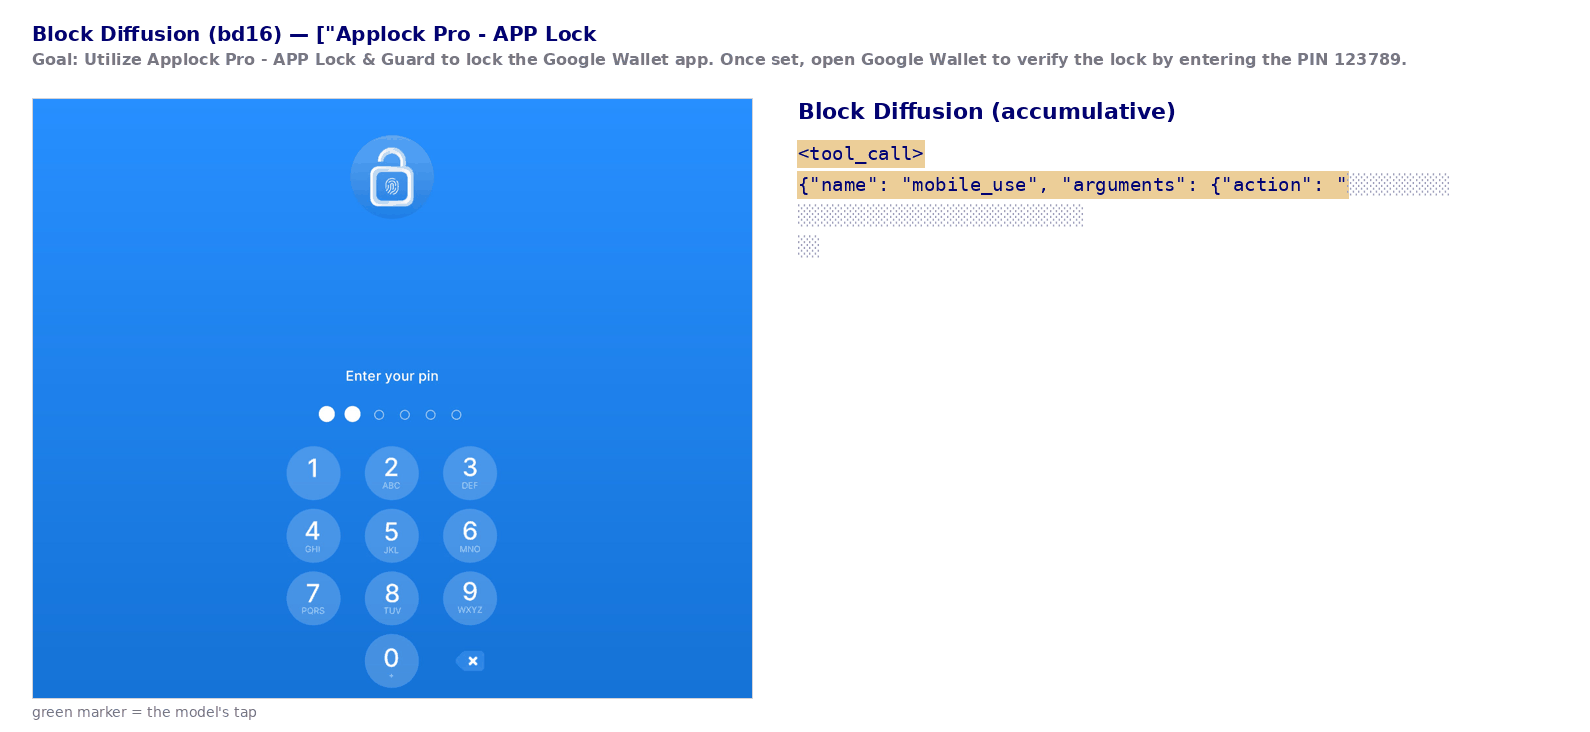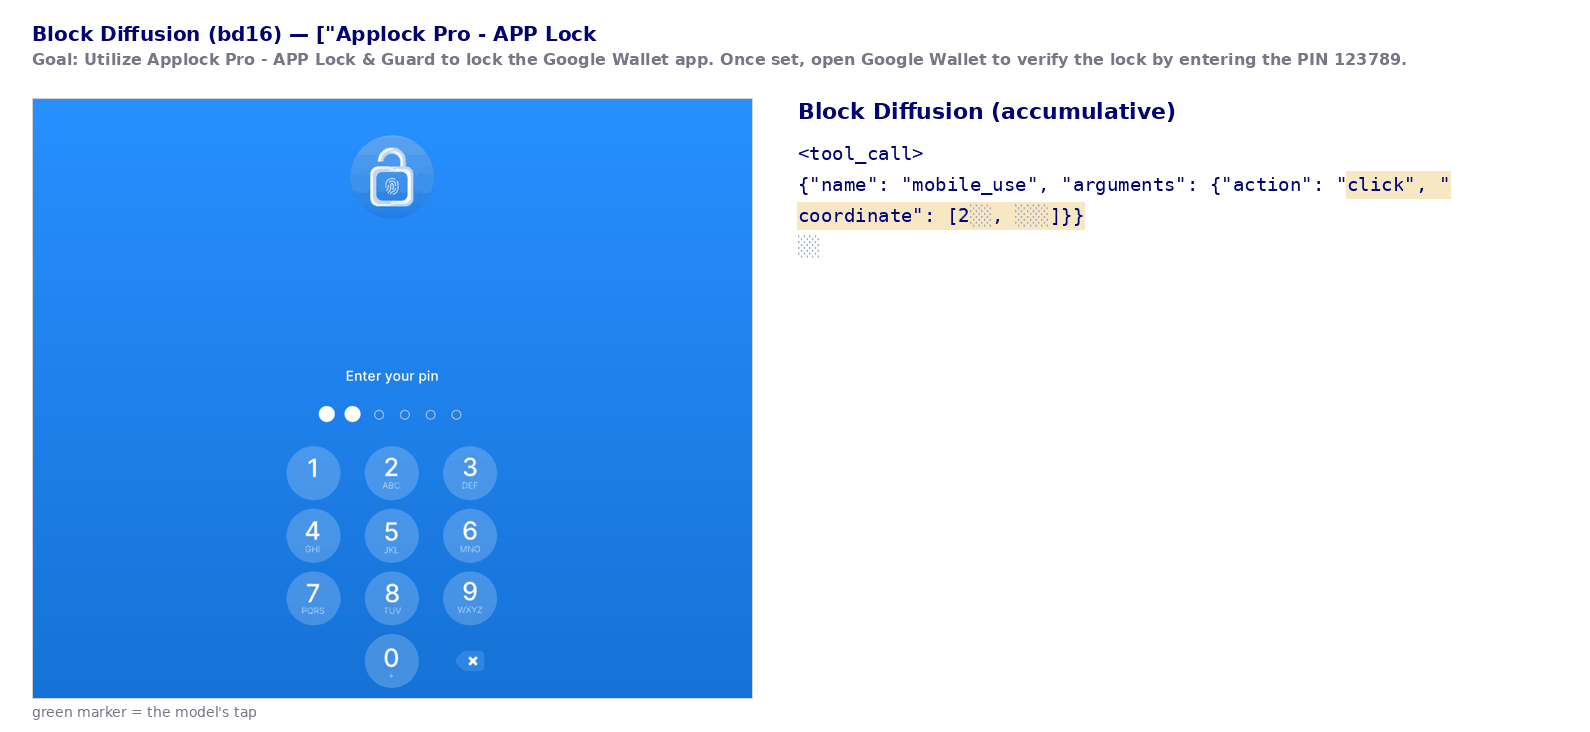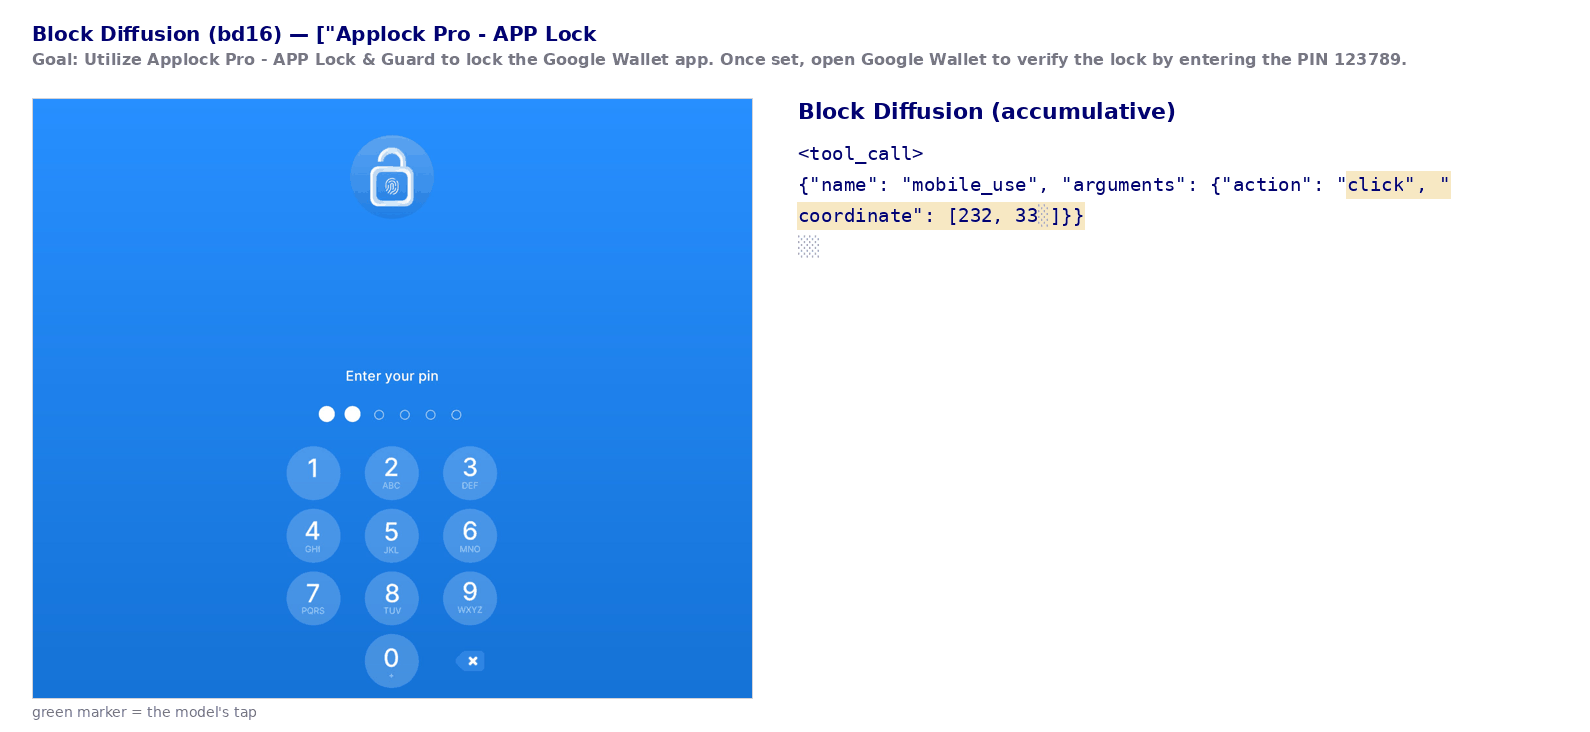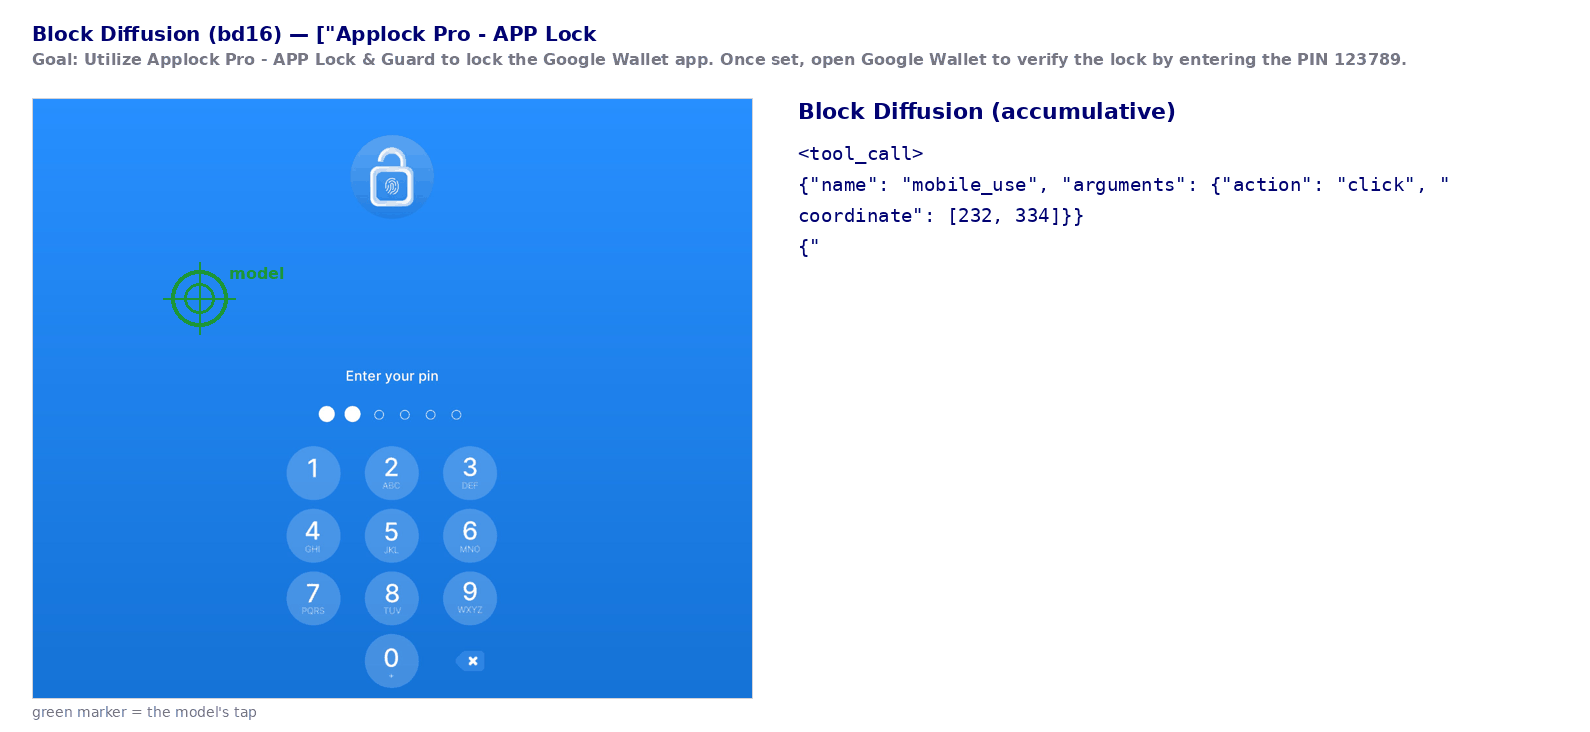
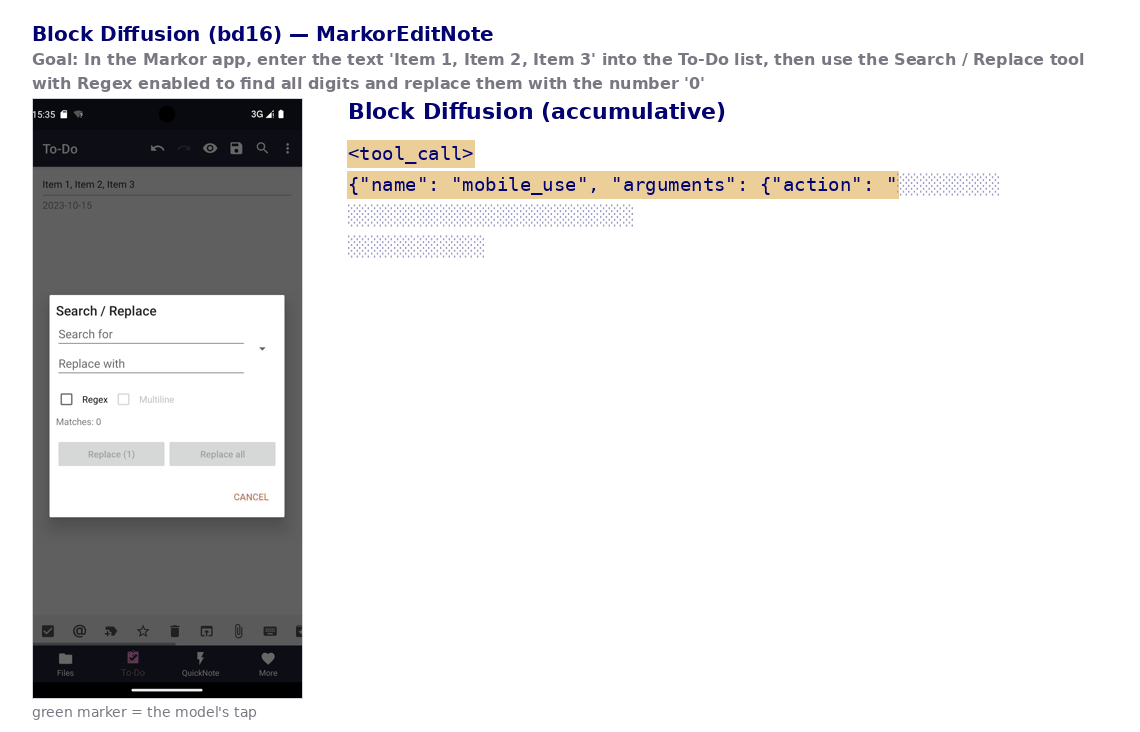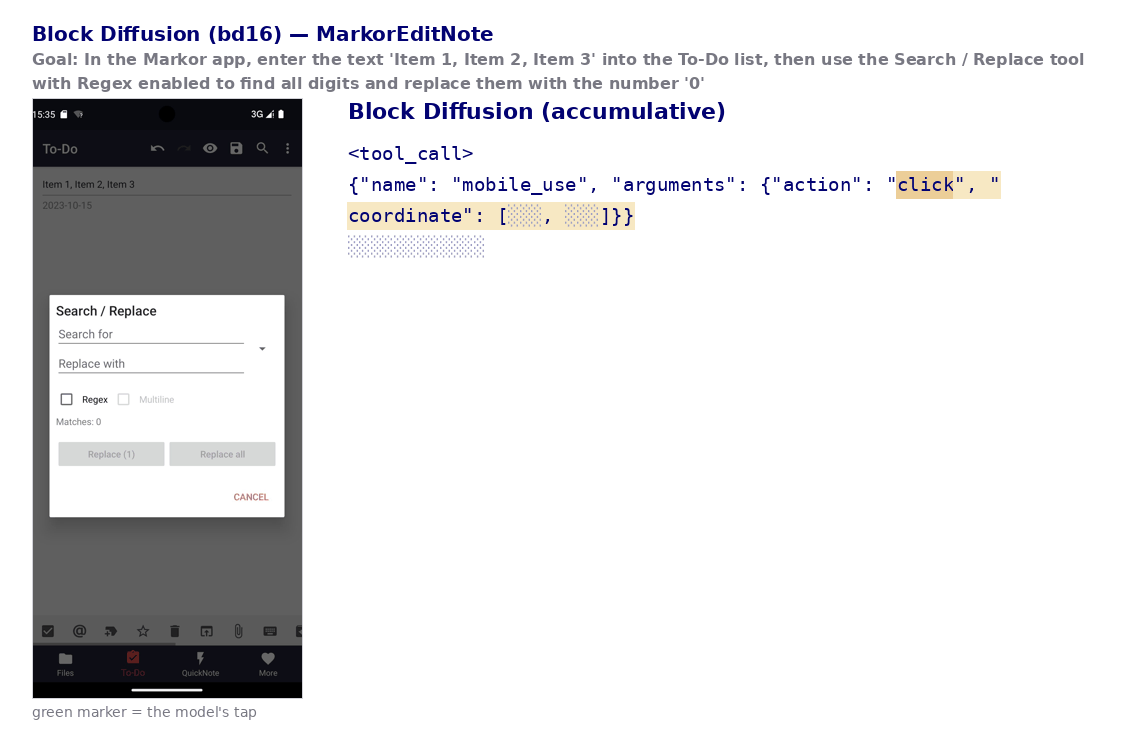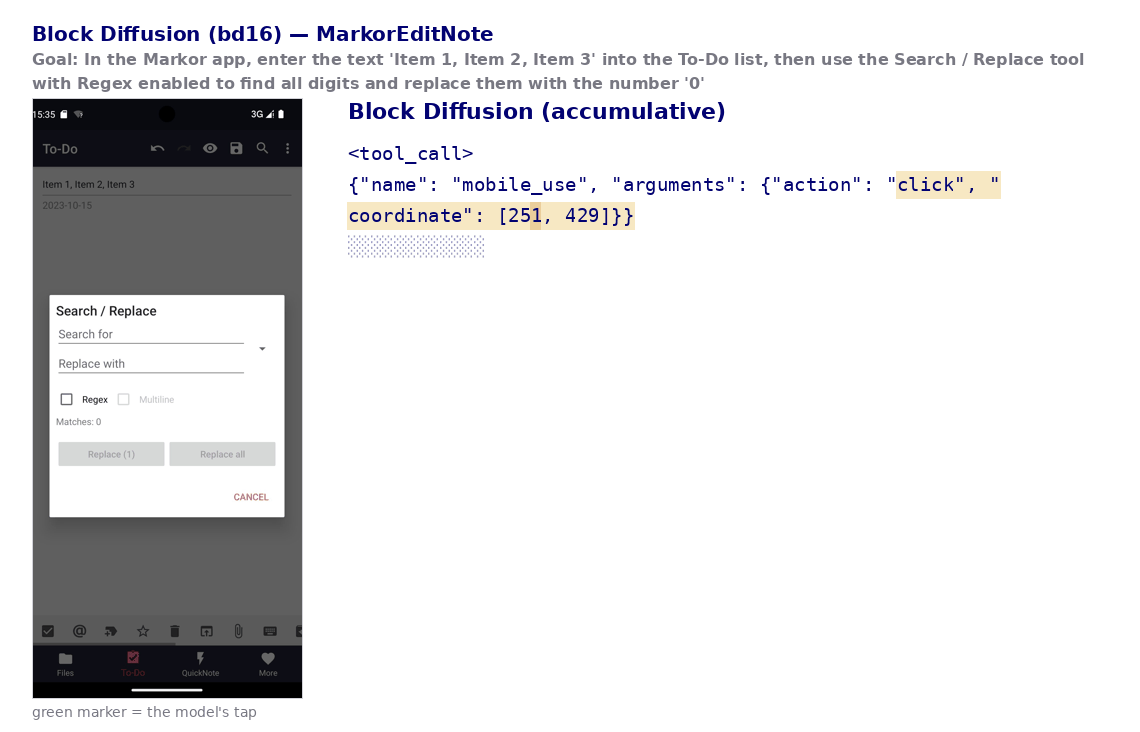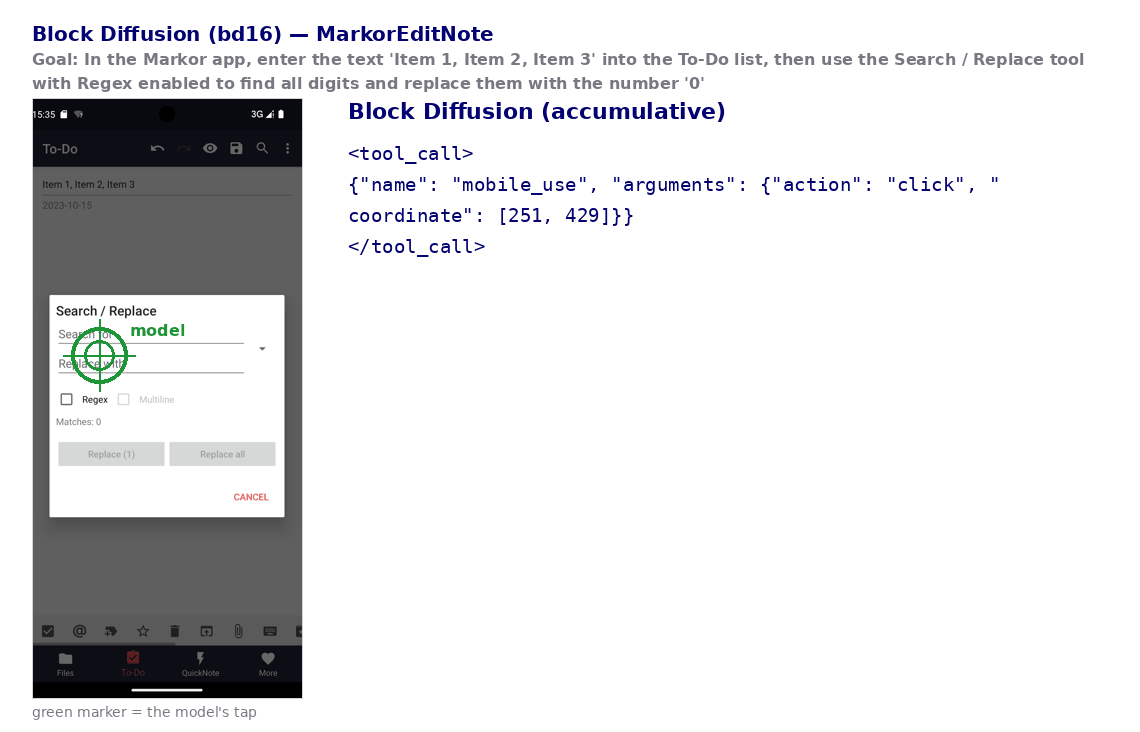
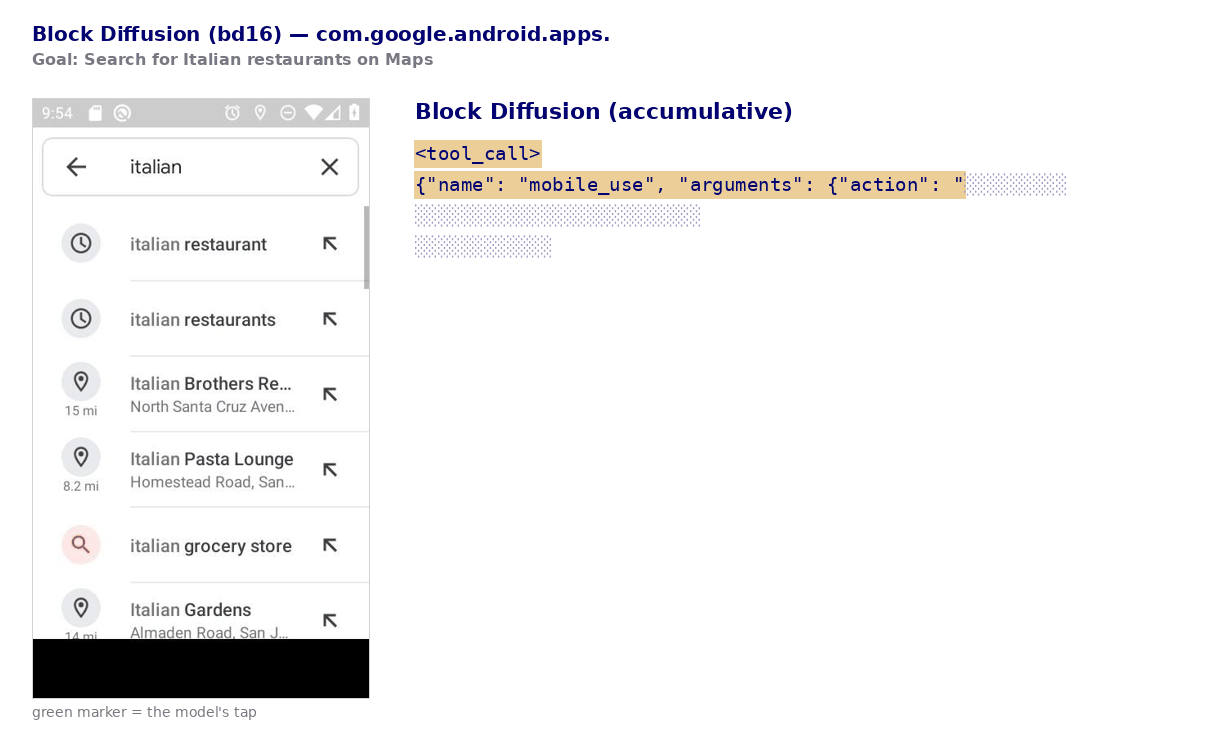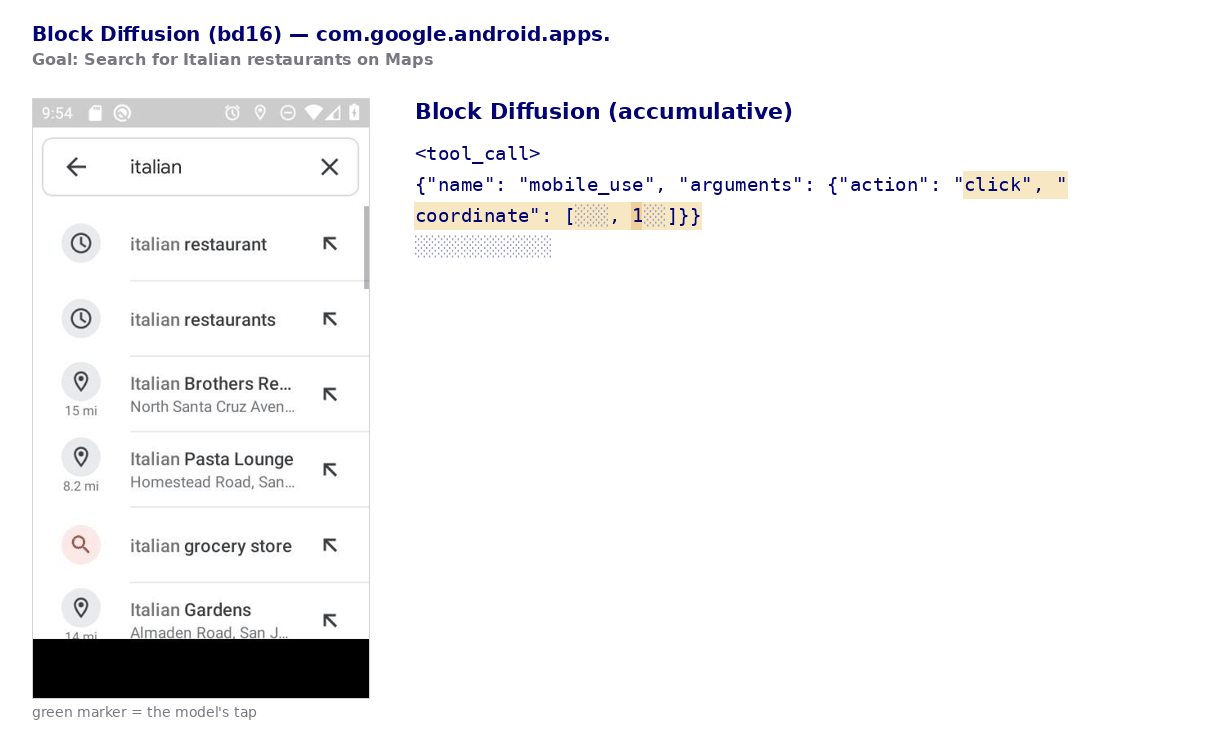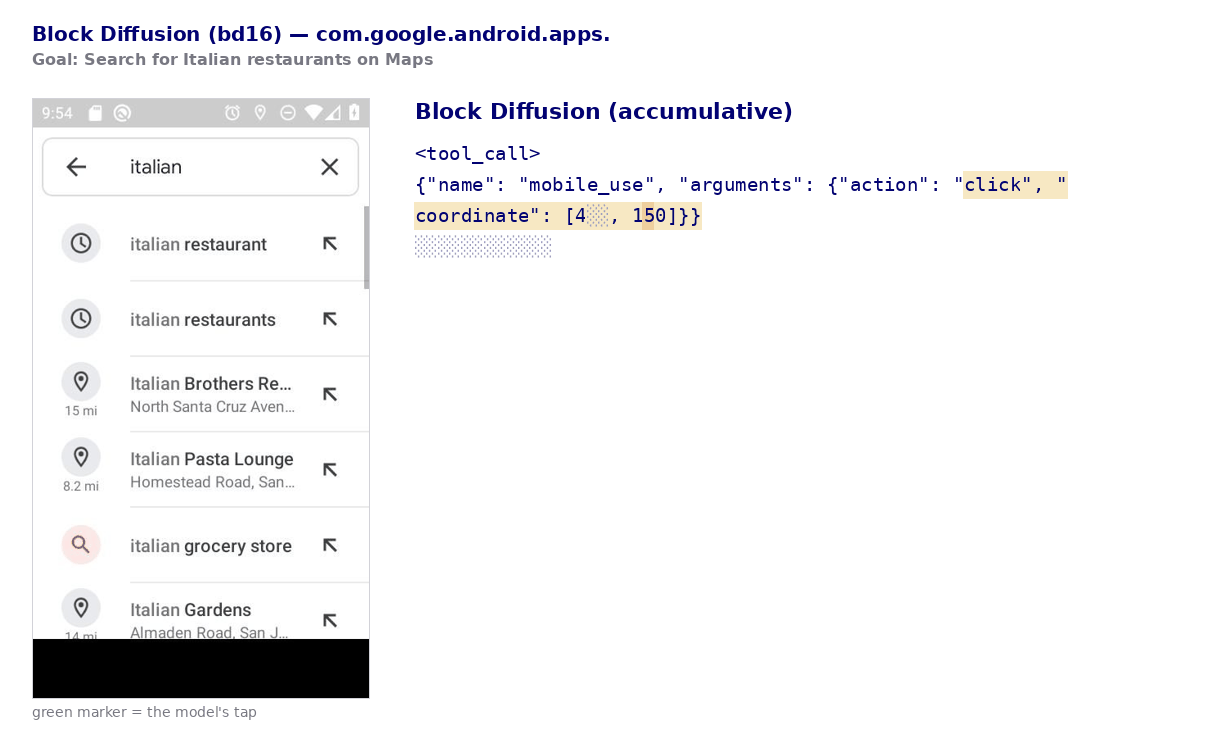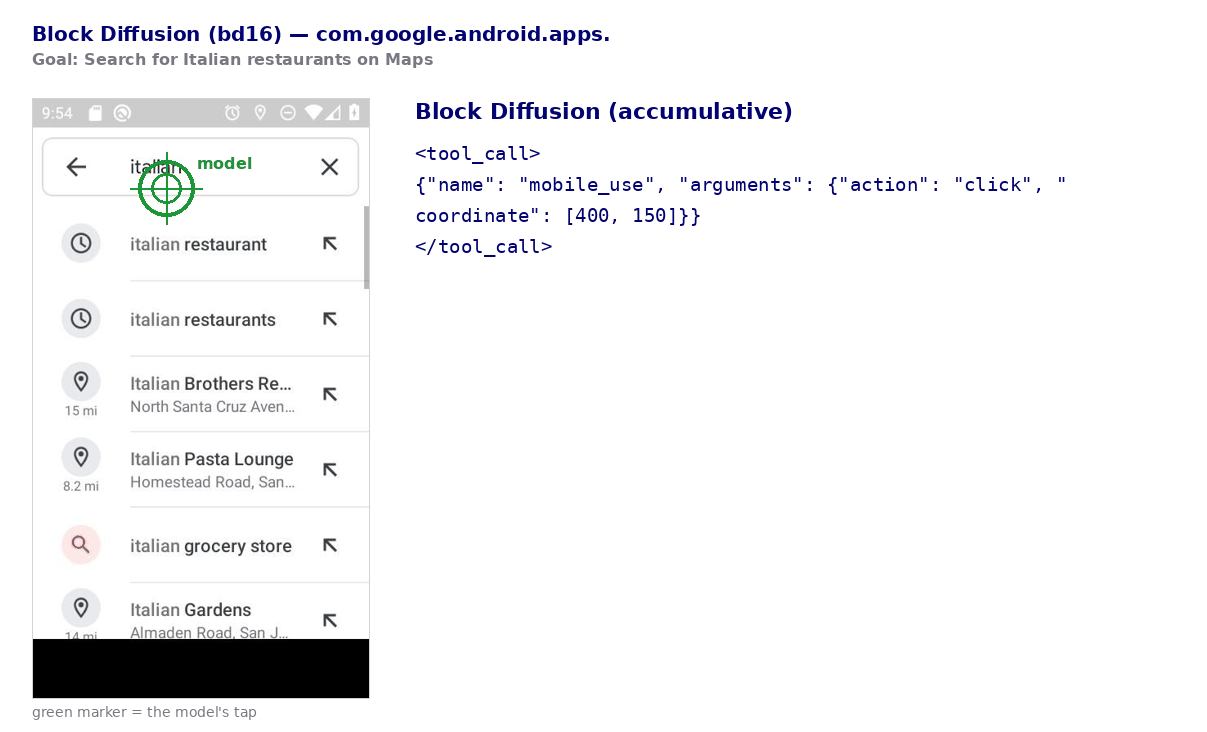
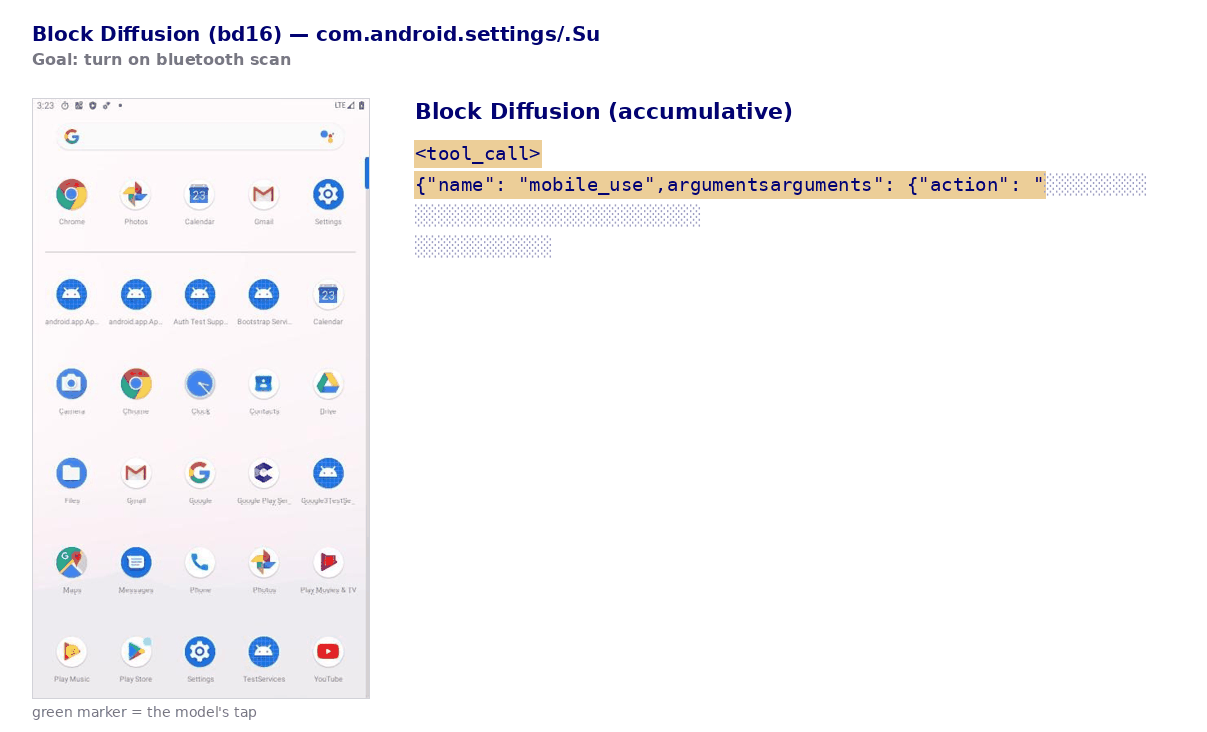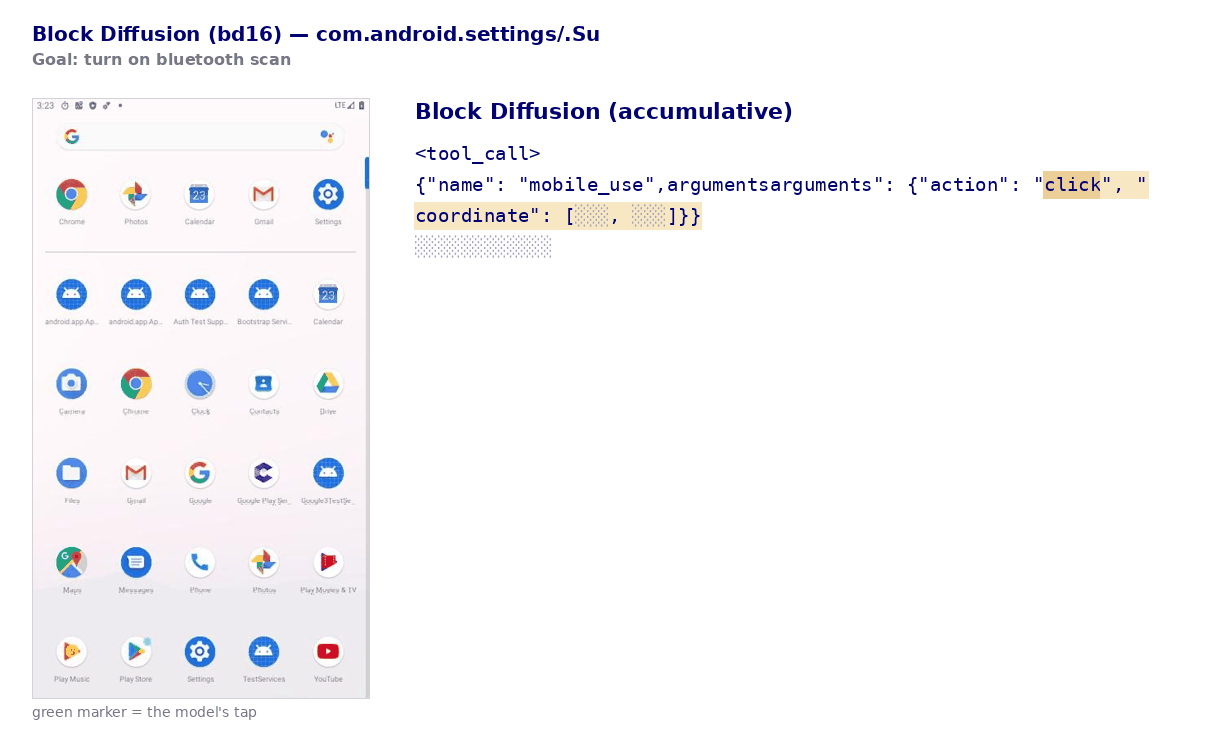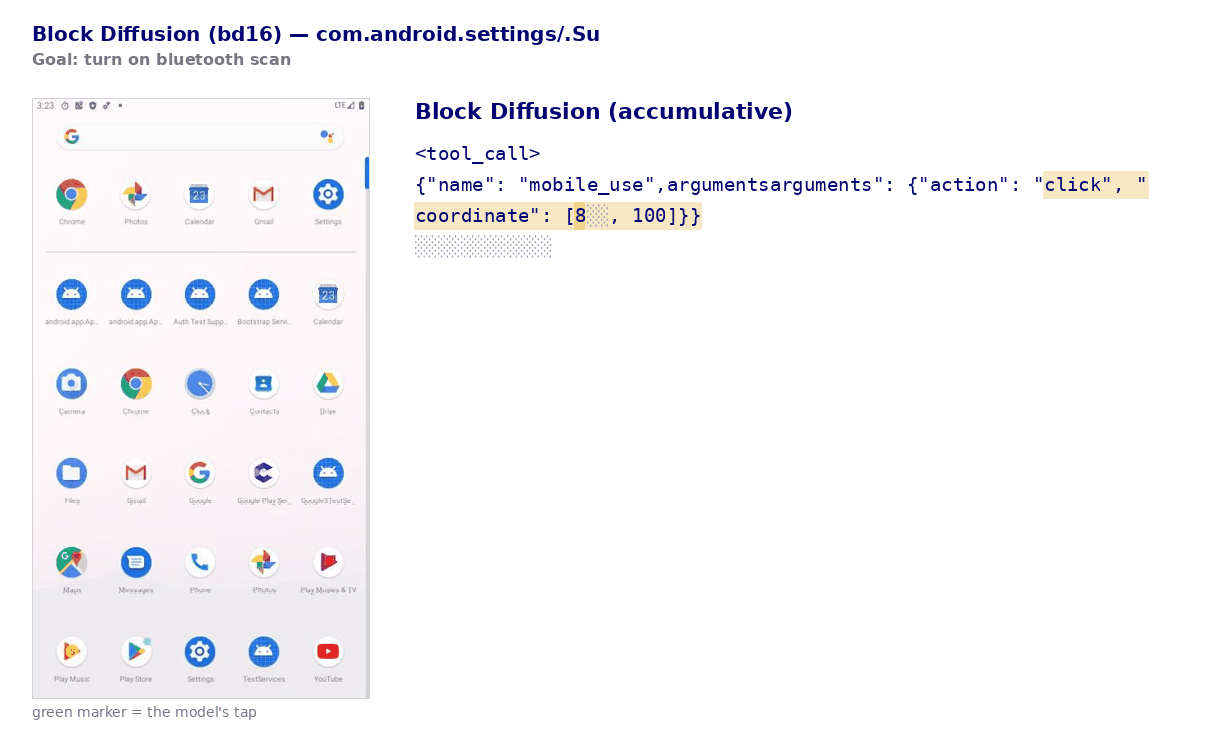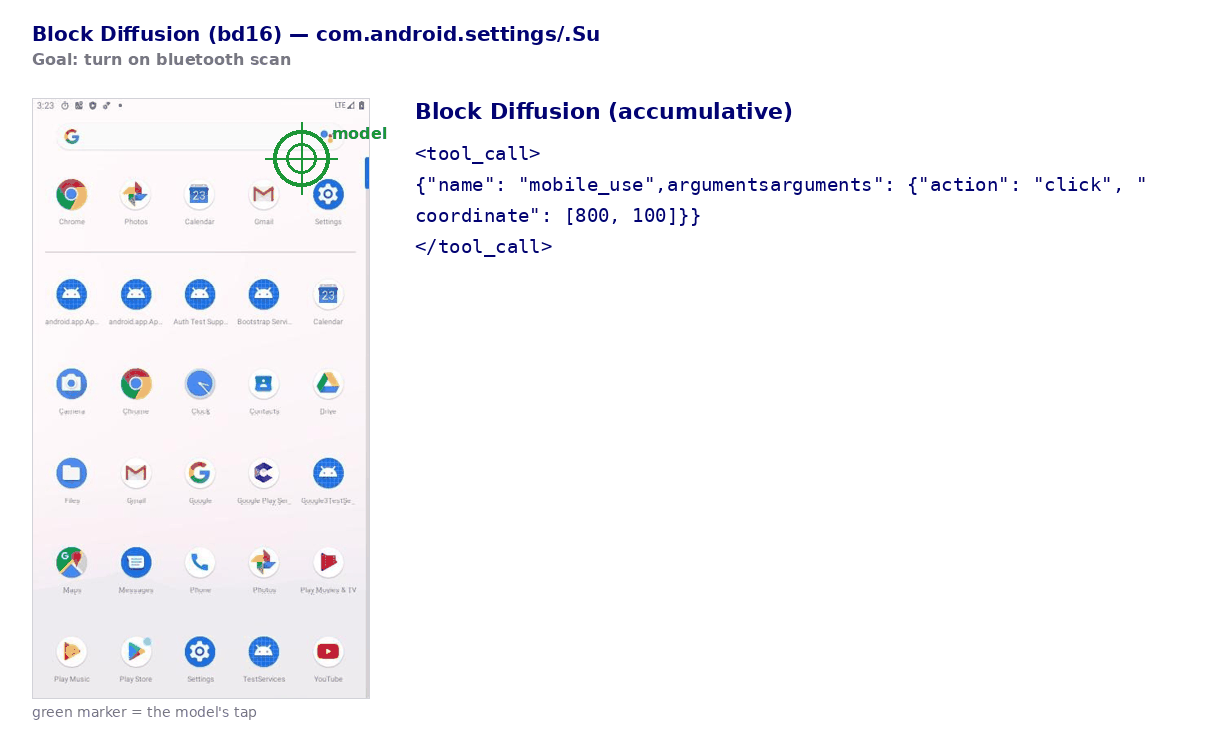
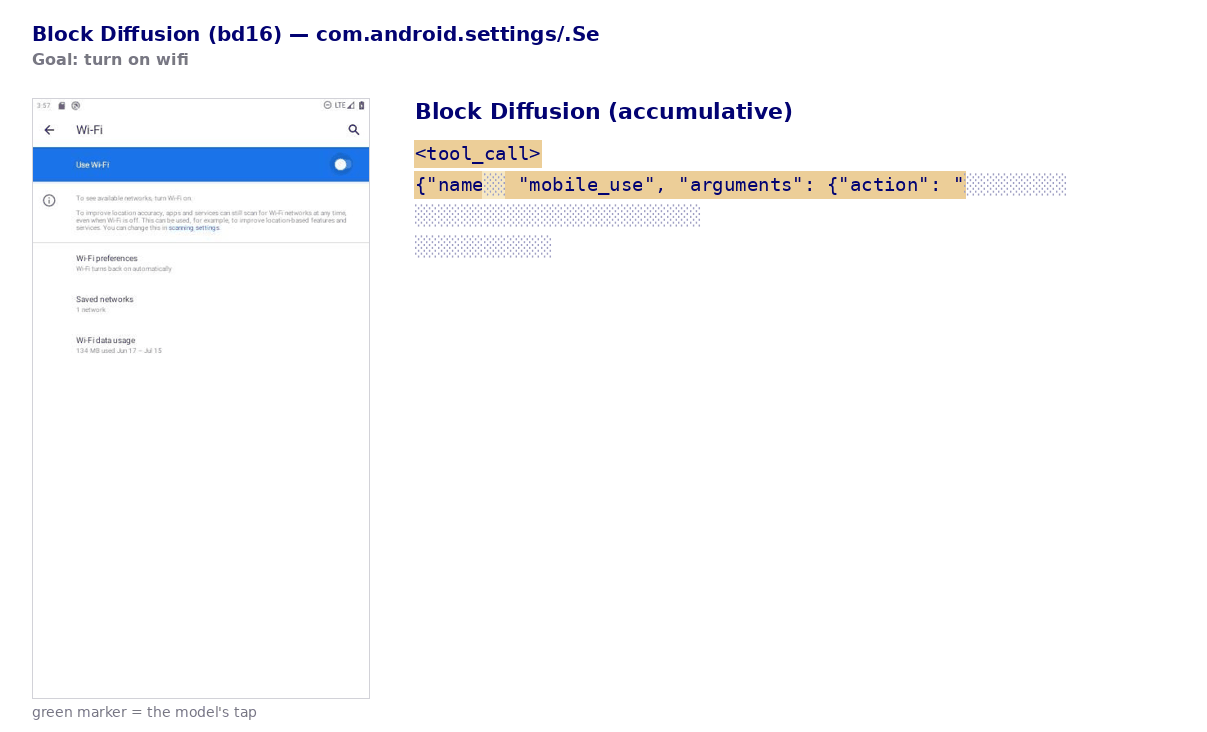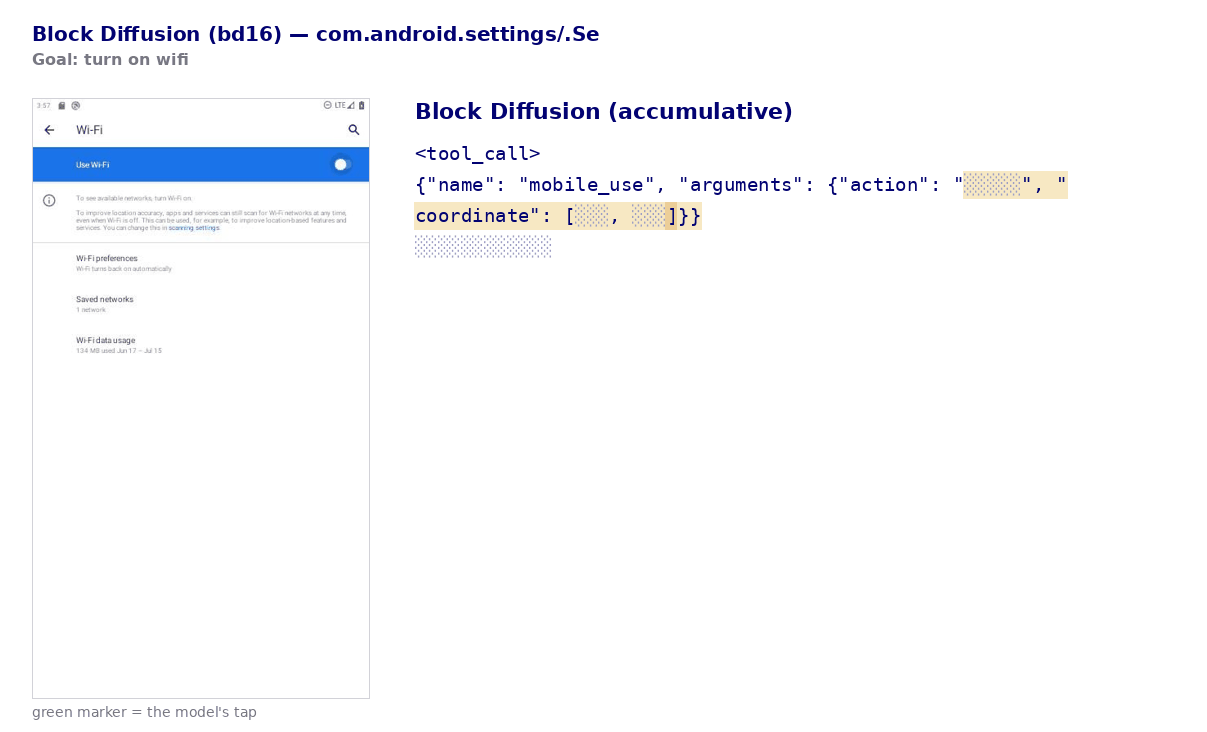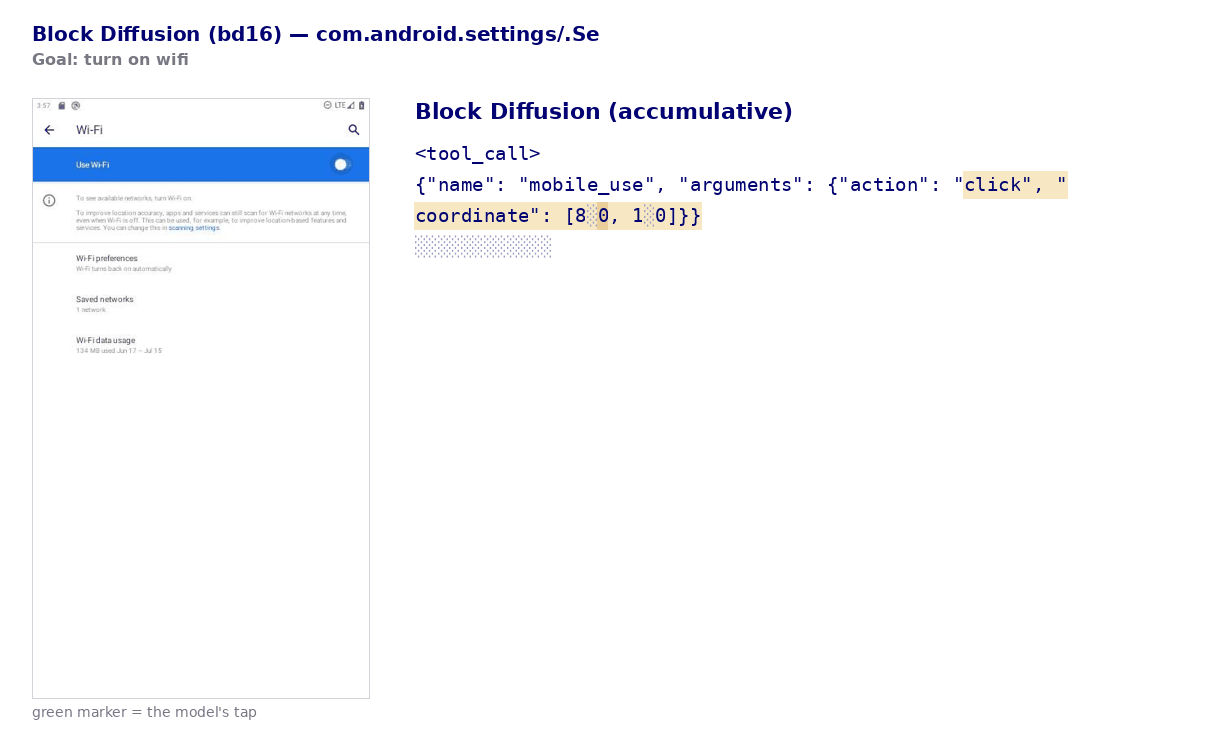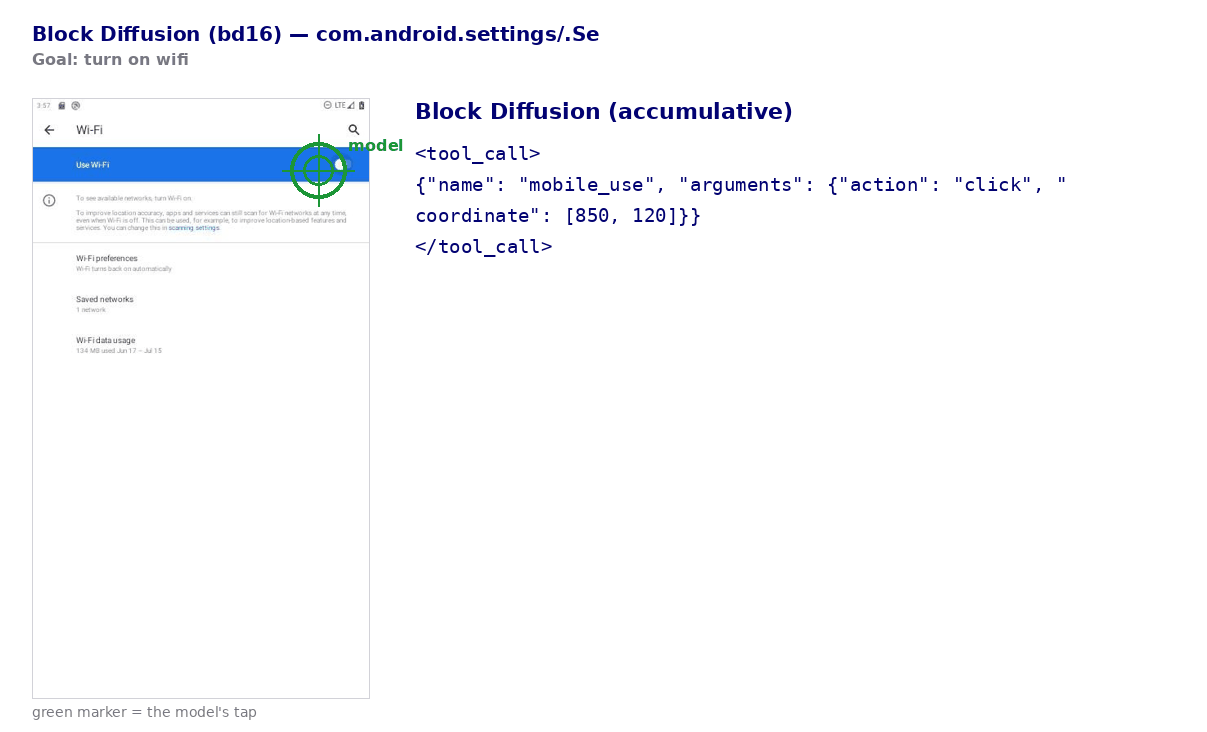
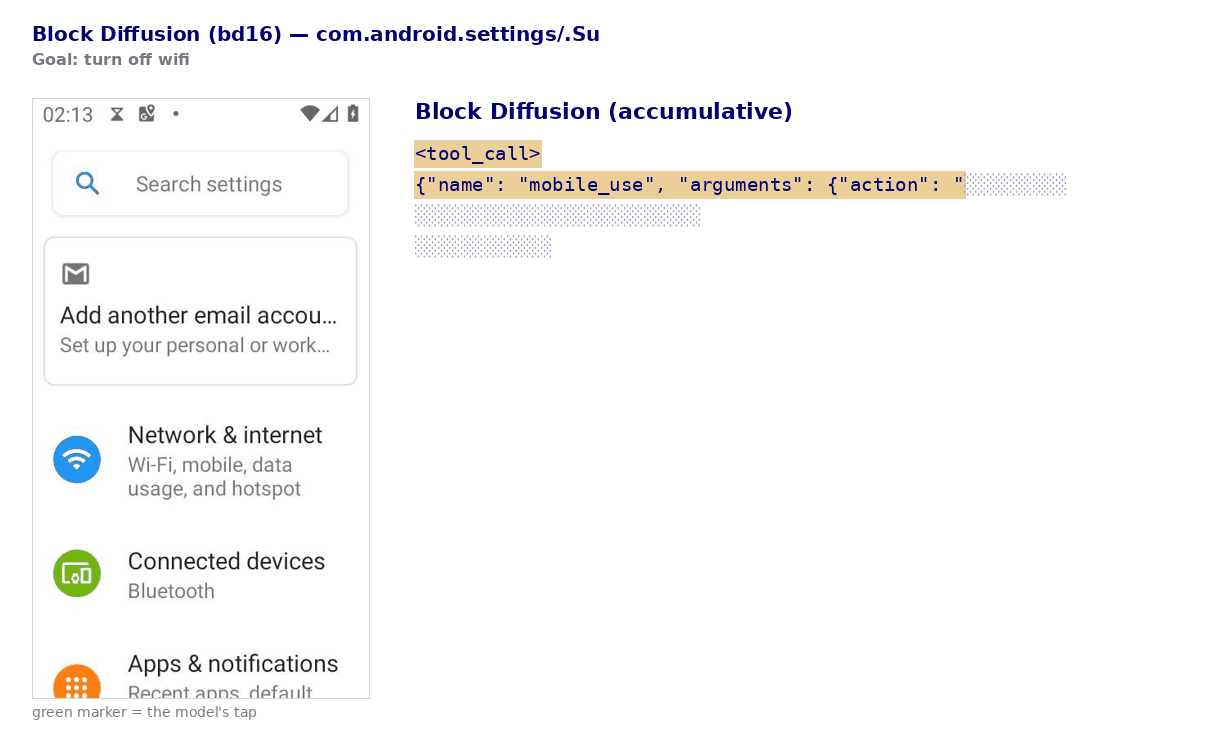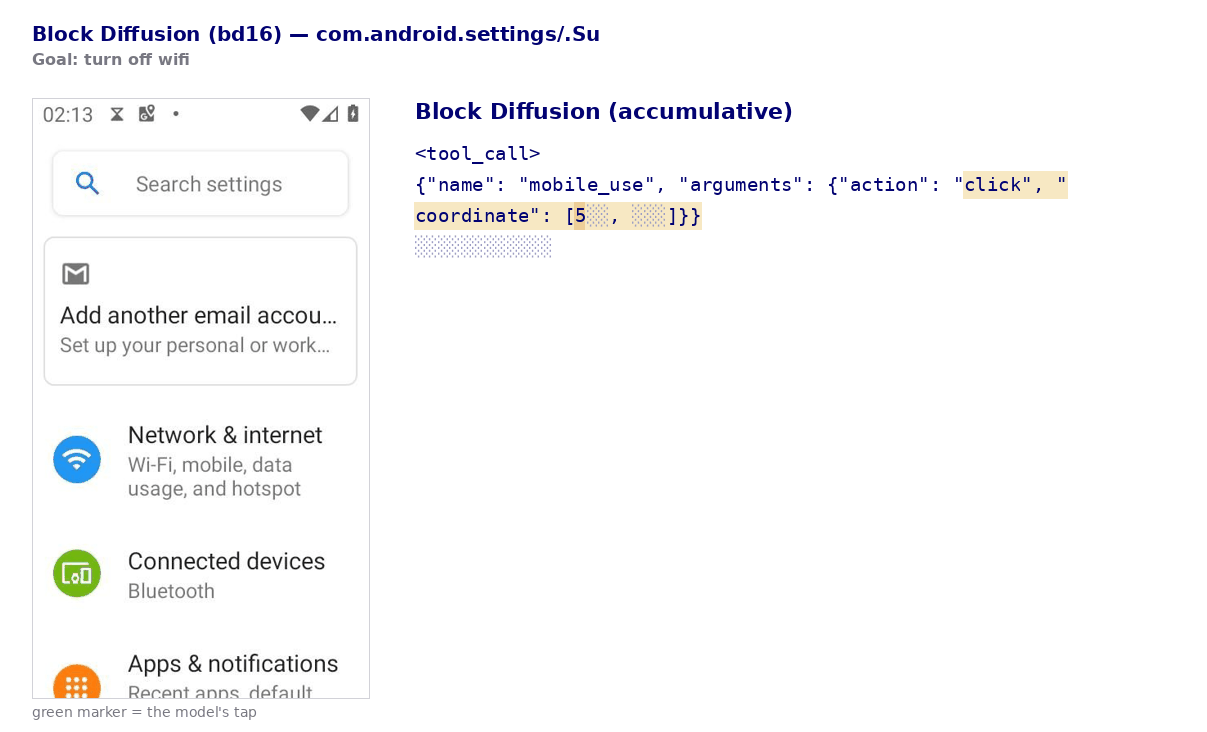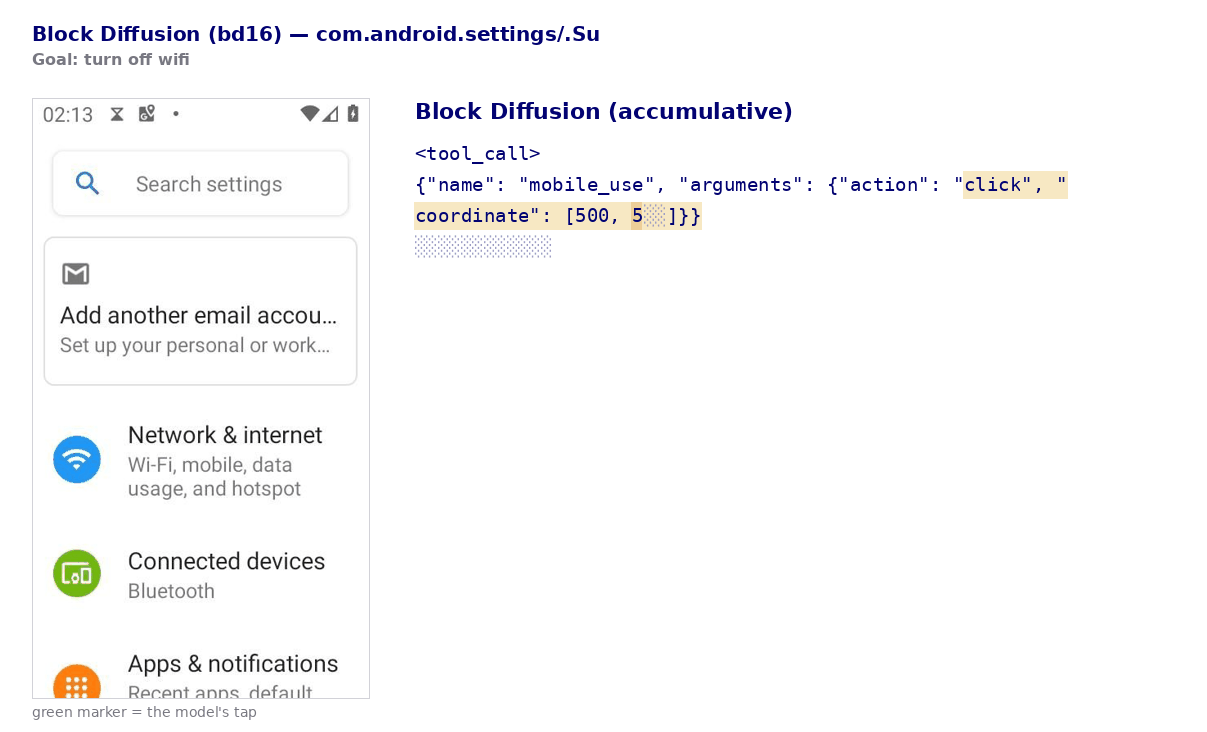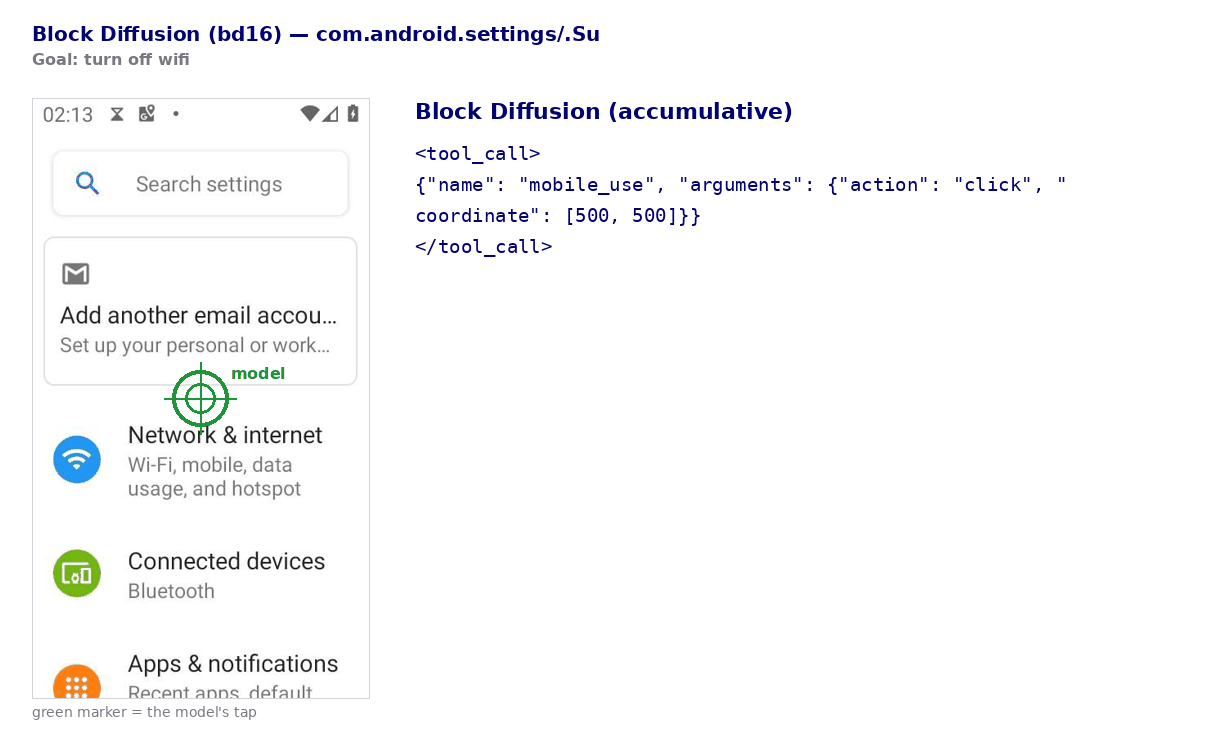
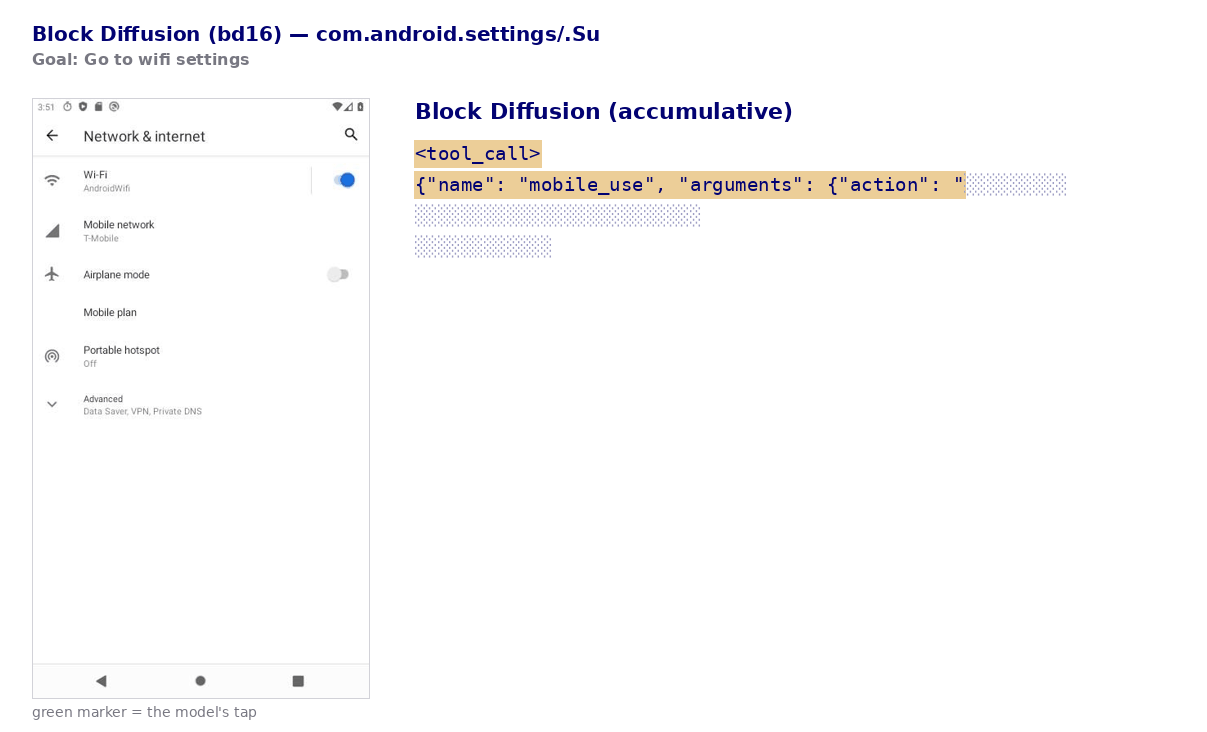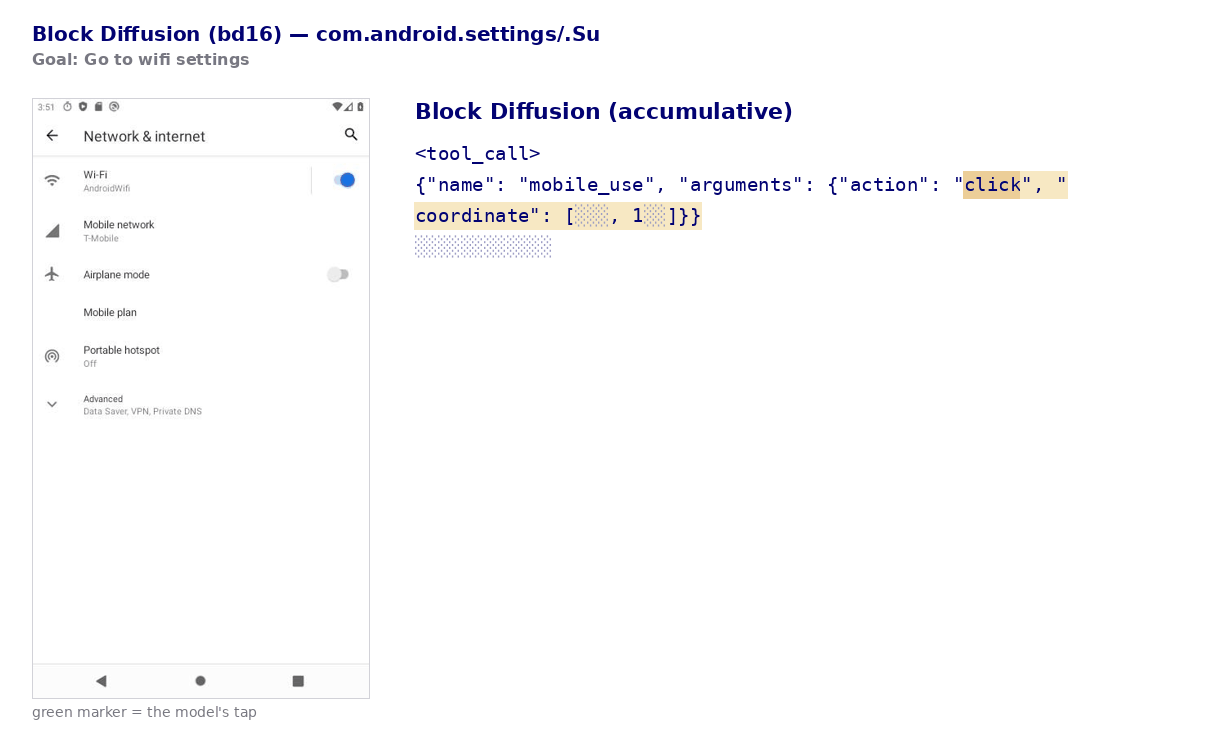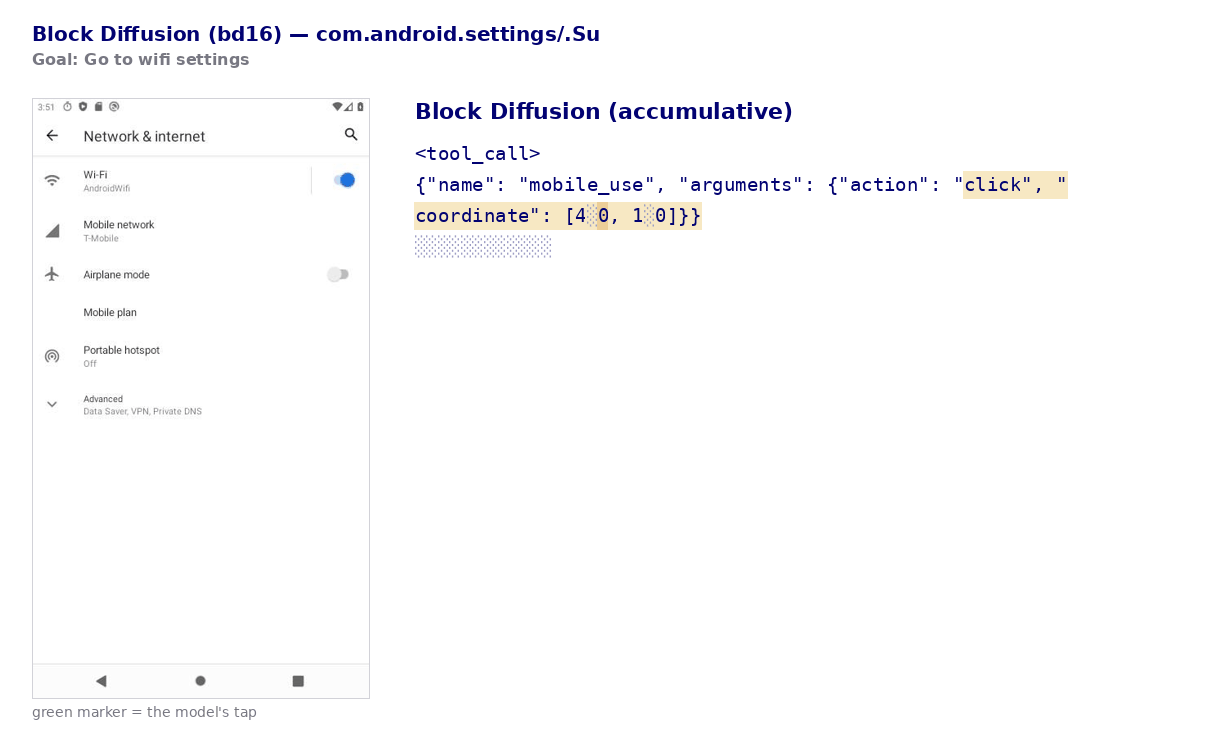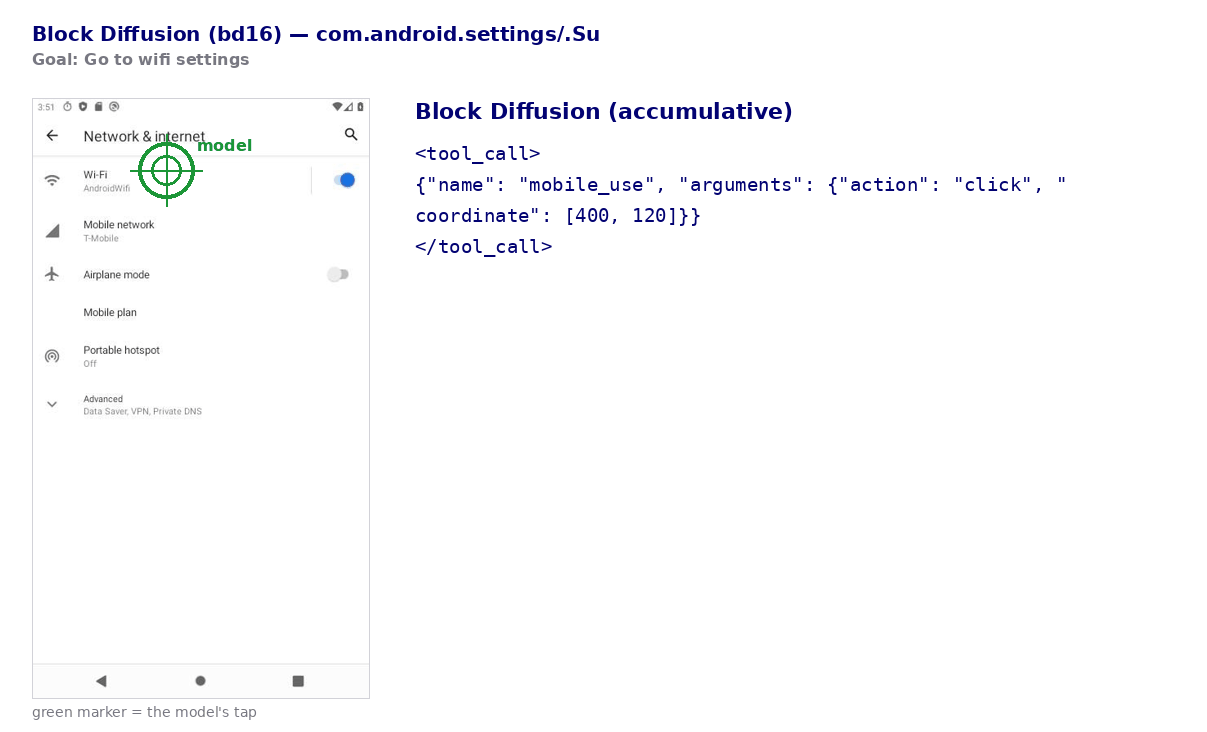
The same agent without chain-of-thought: a single block-diffusion decode (no autoregression) emits one UI action in one step. Each clip shows the task goal, and the green marker is the model's tap landing on the intended target. Click to enlarge.
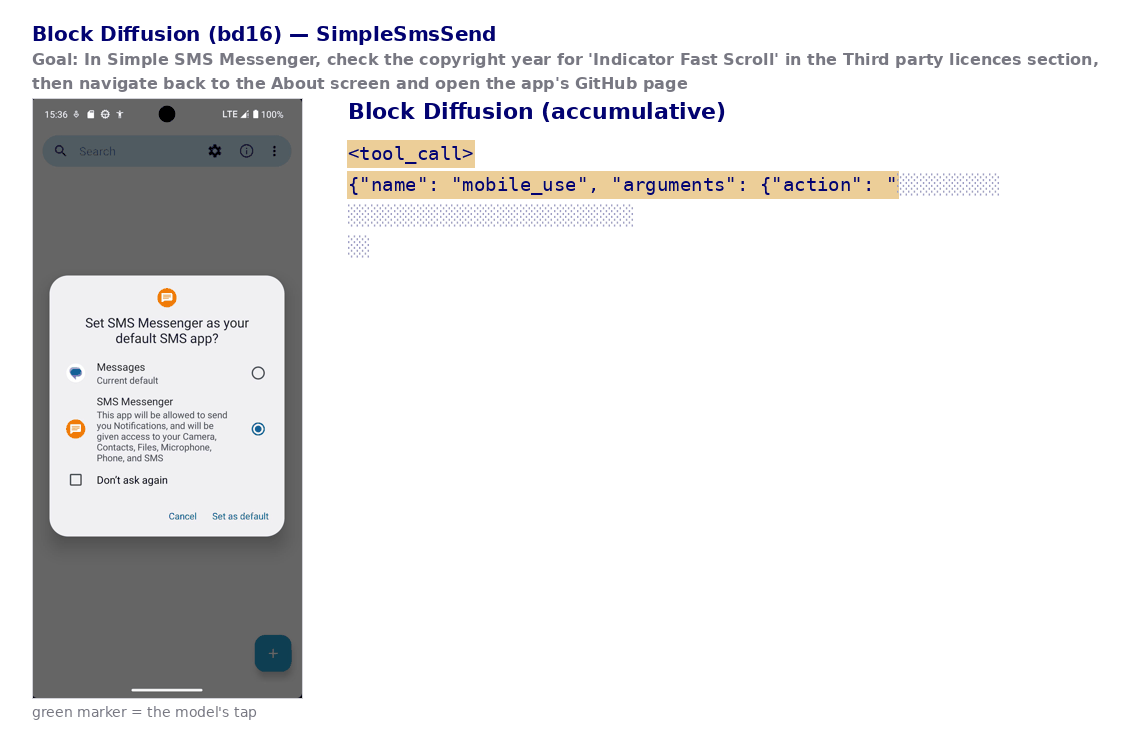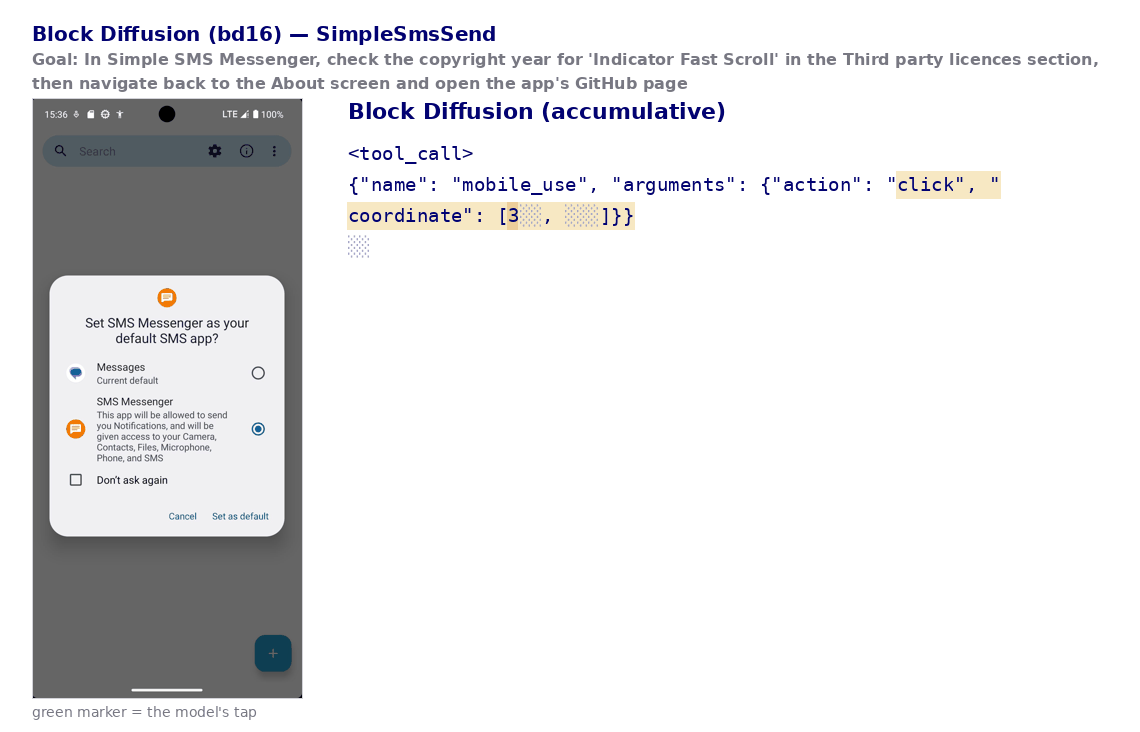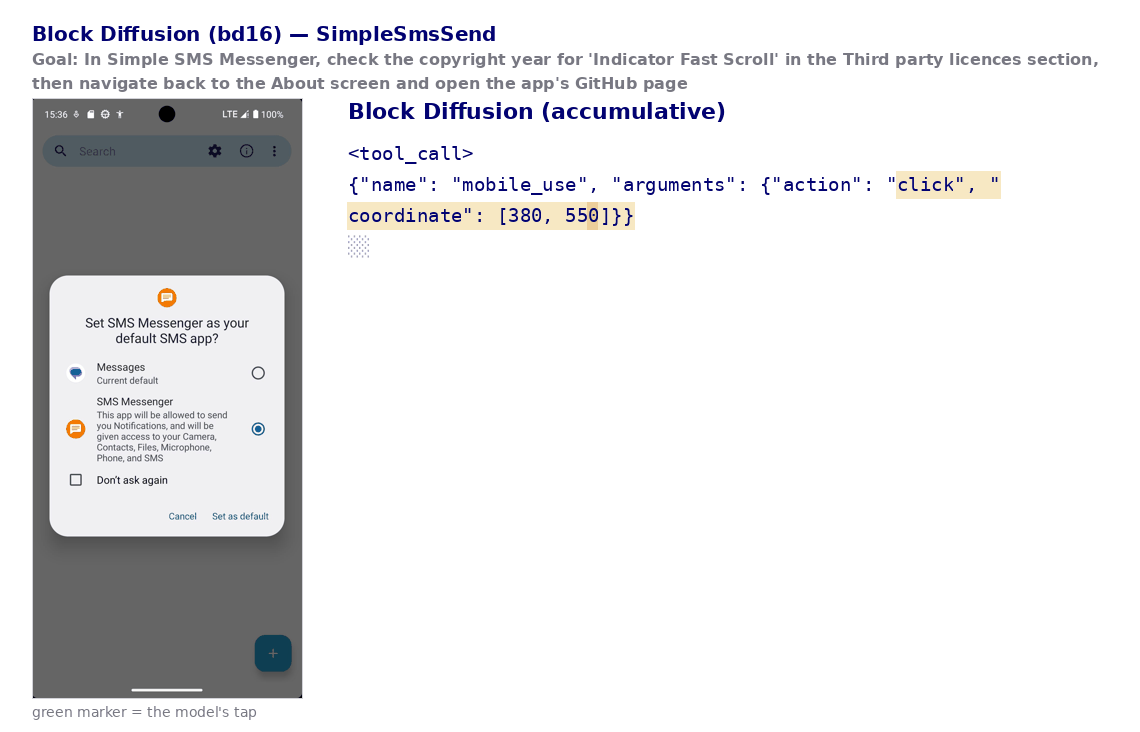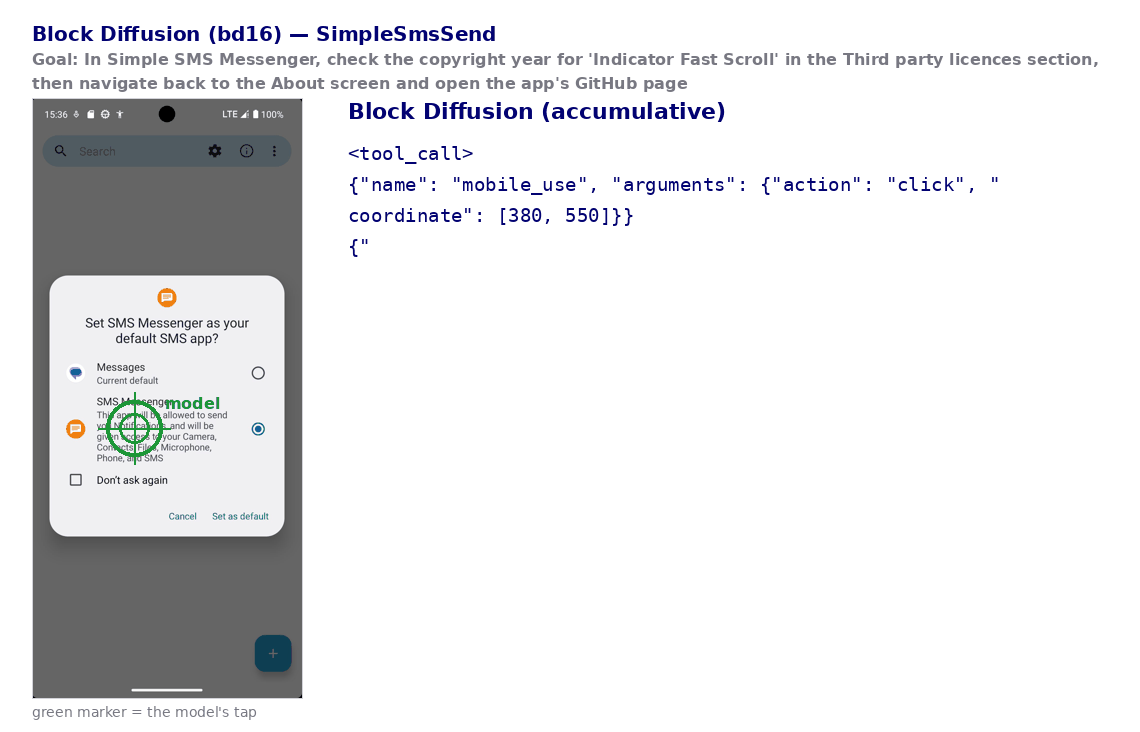
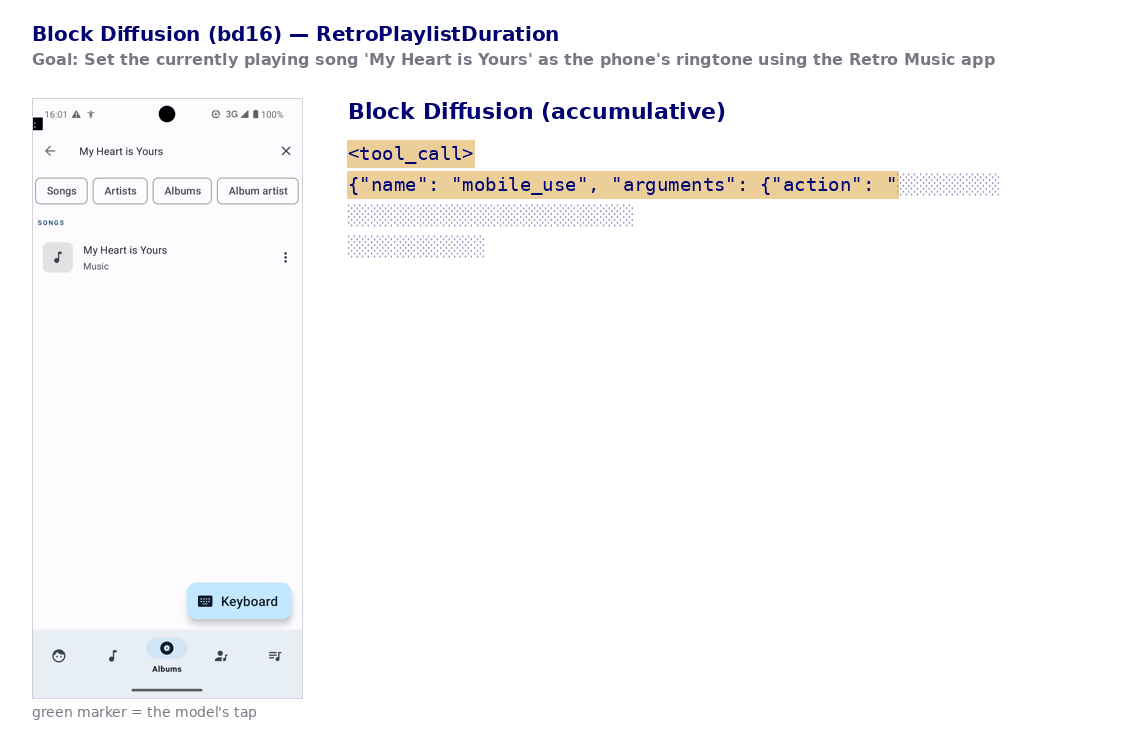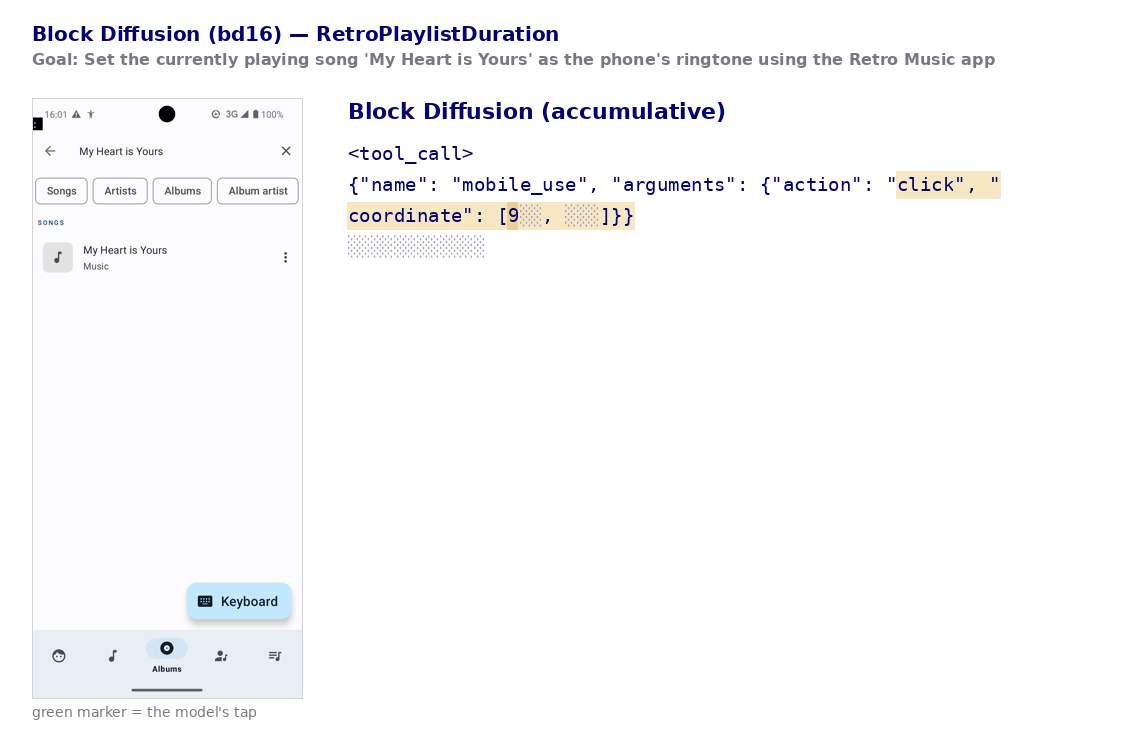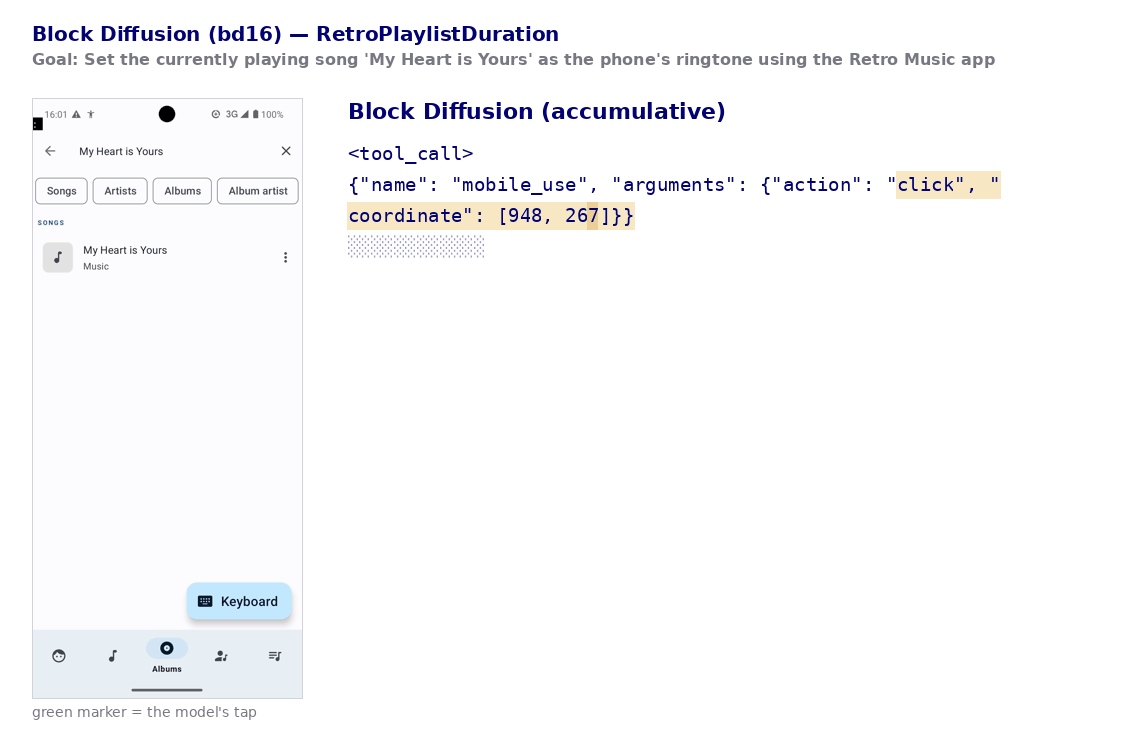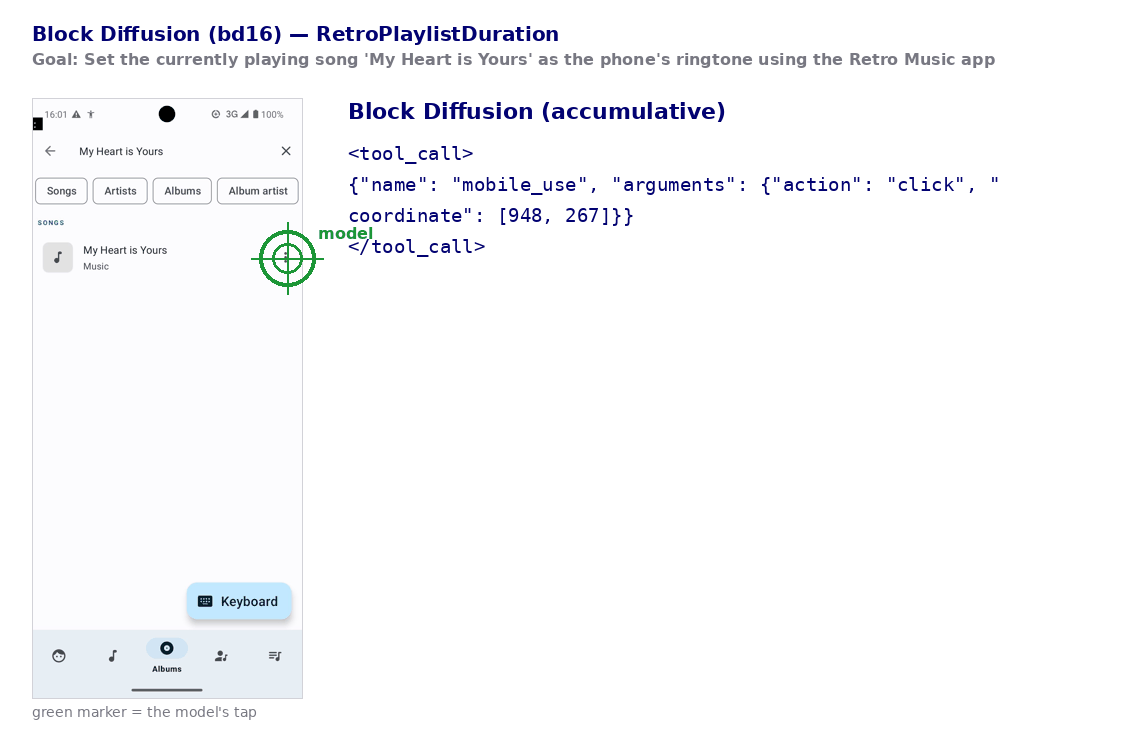
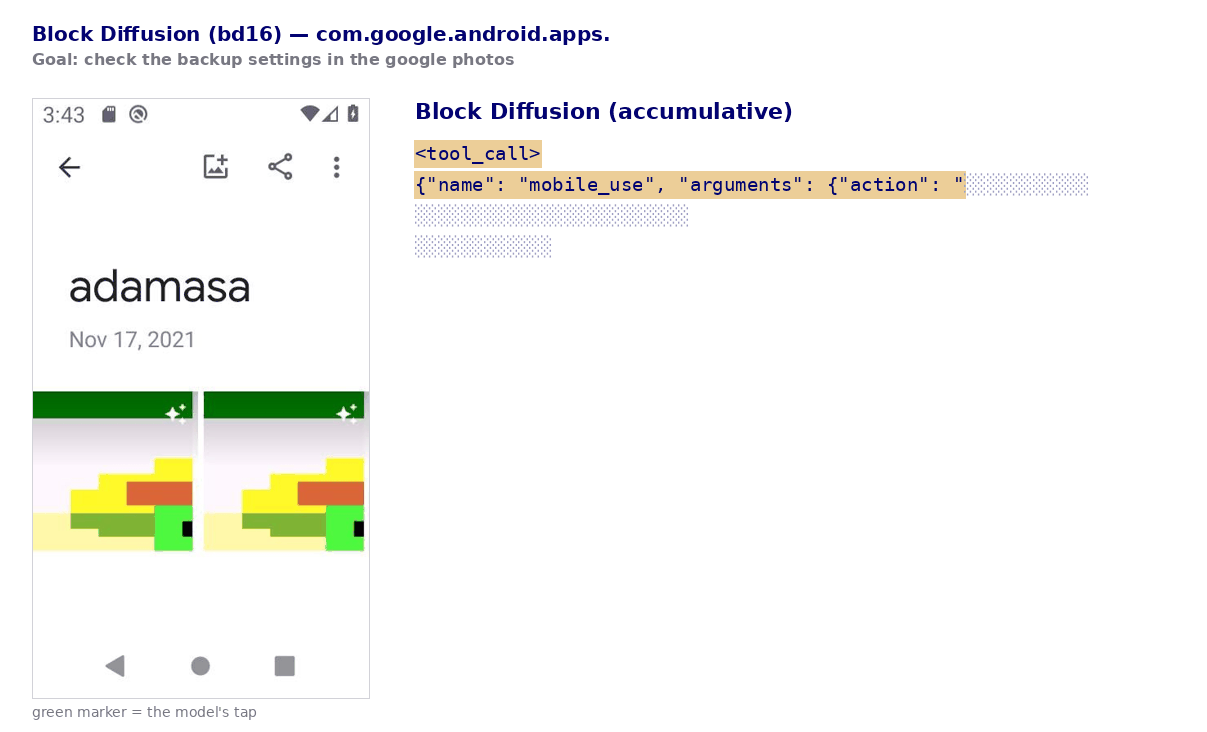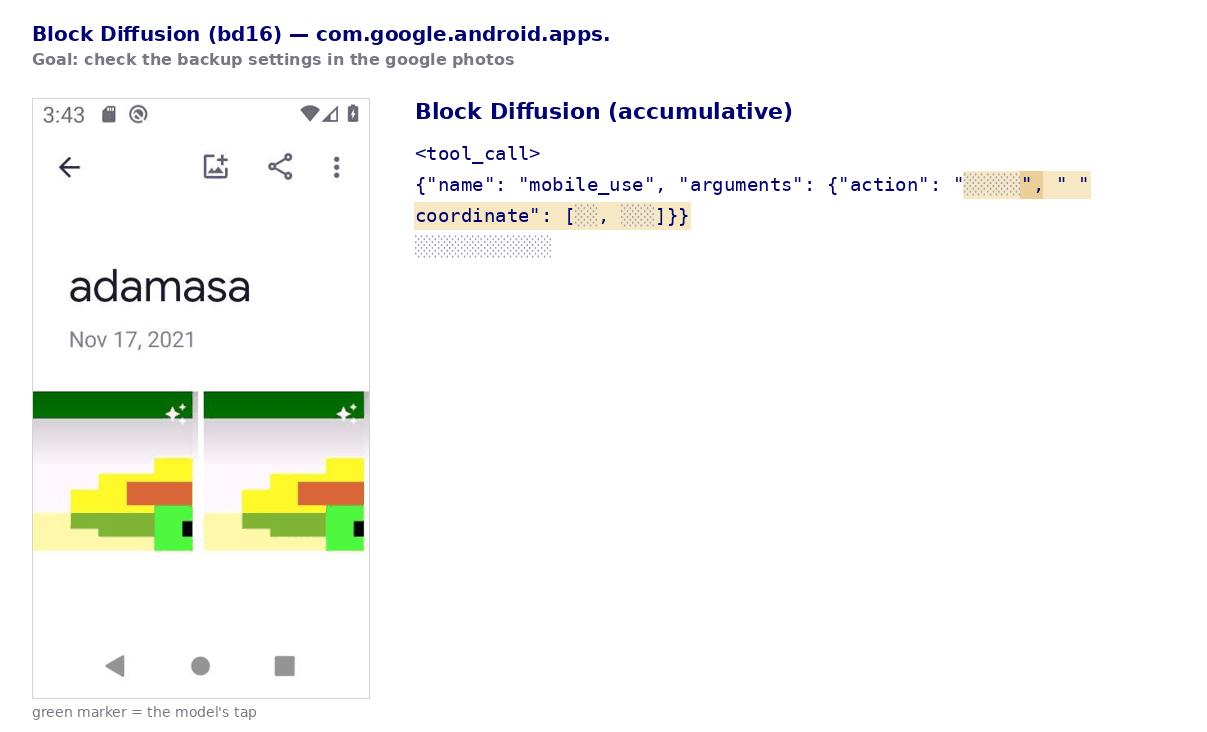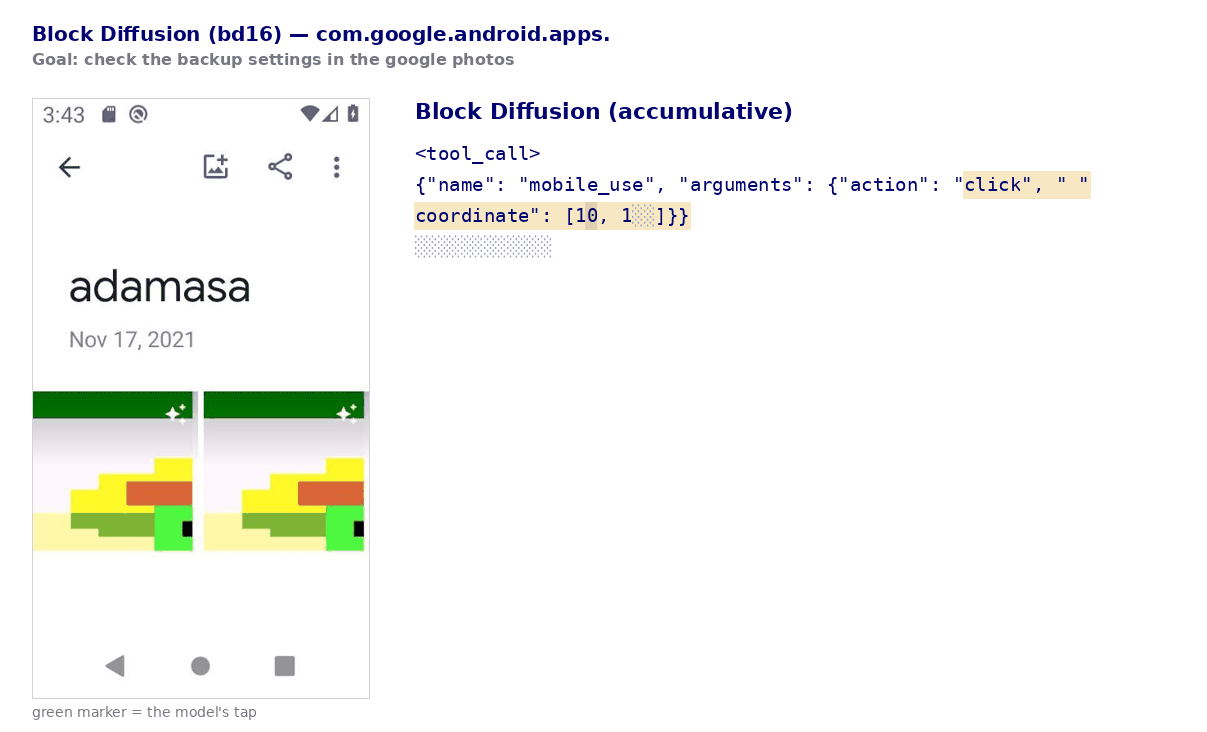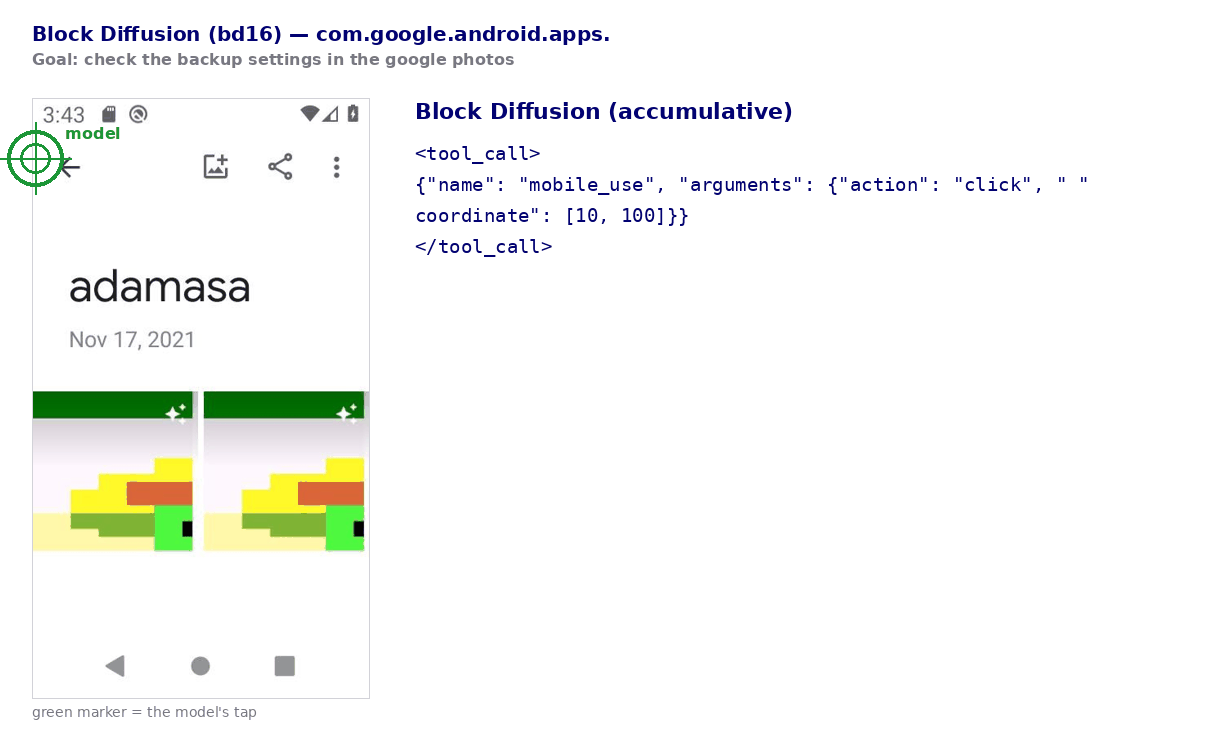
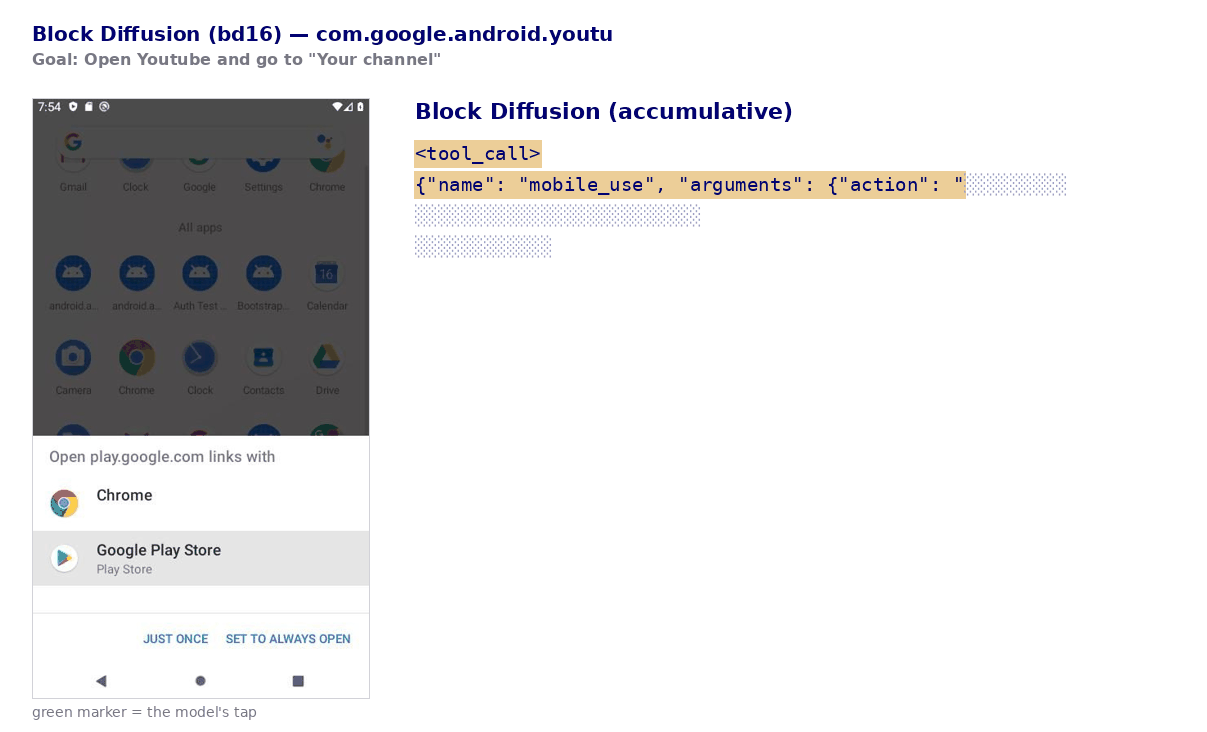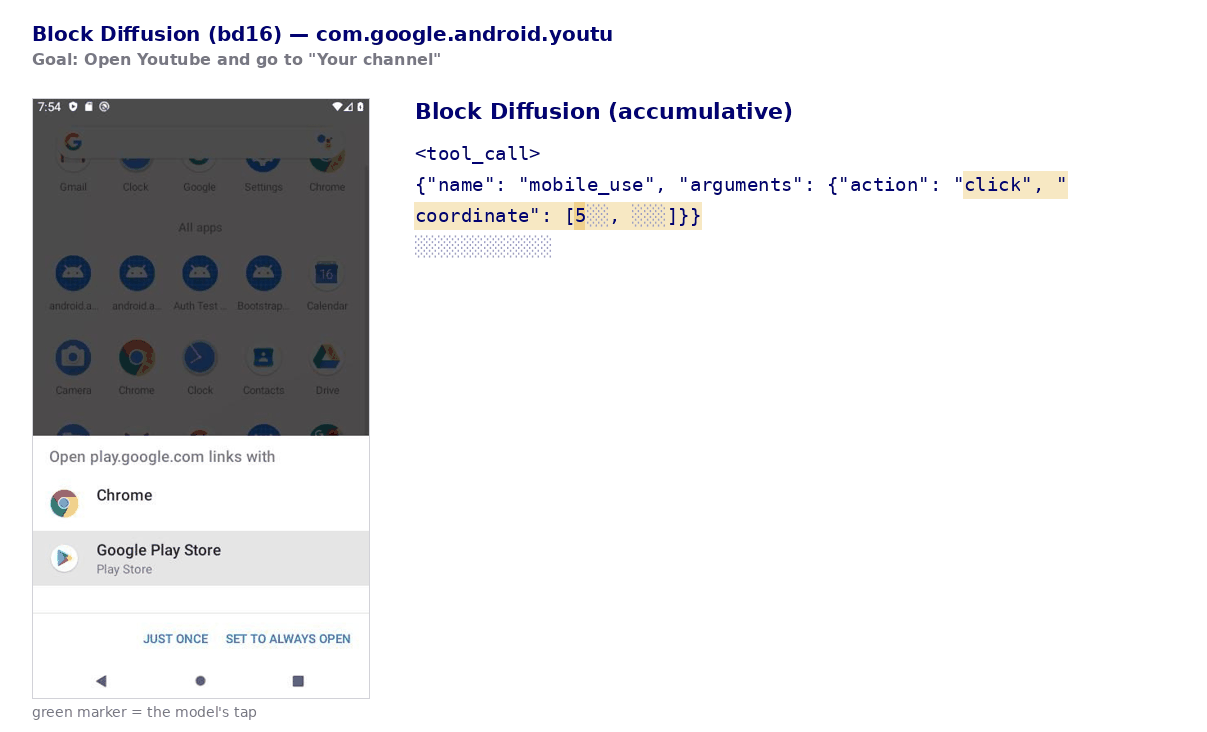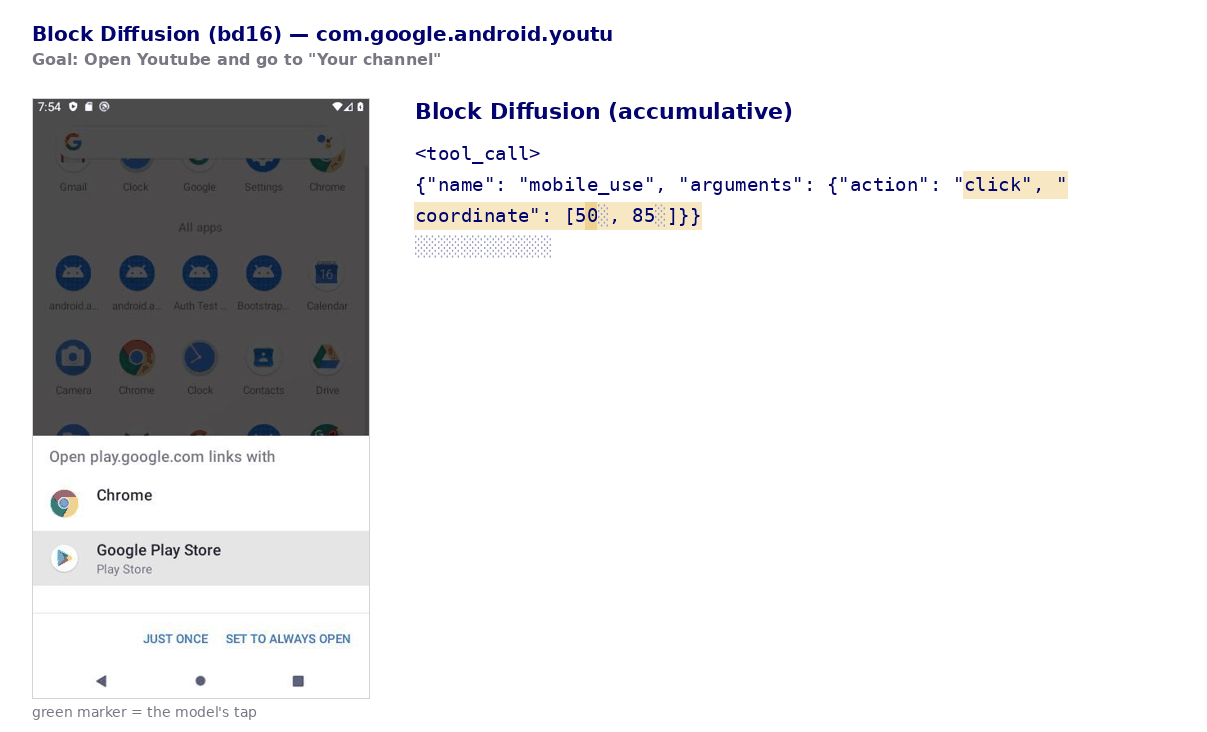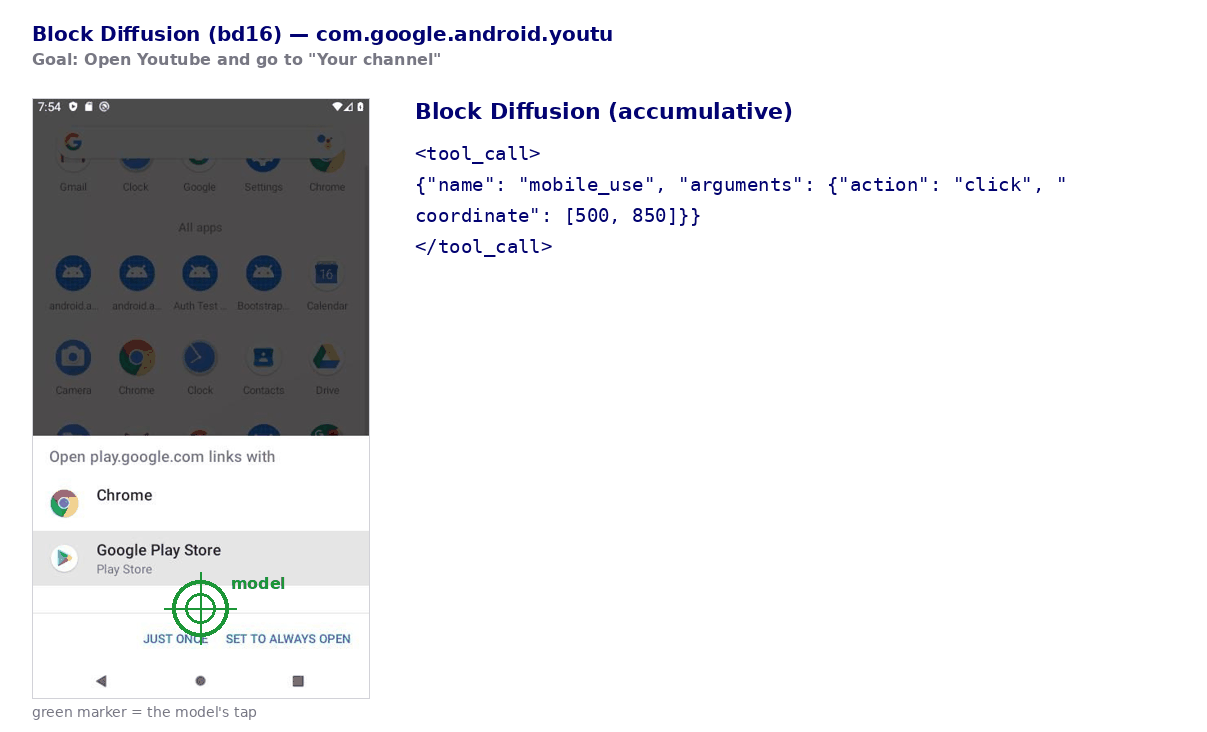
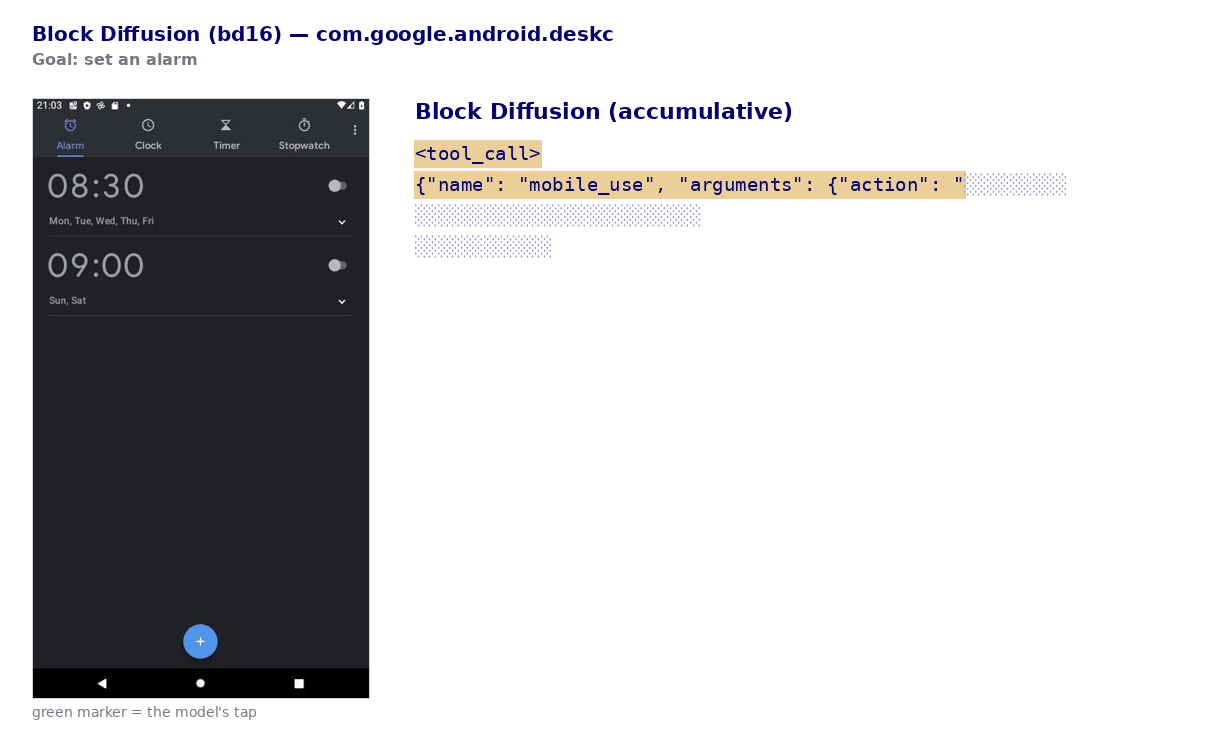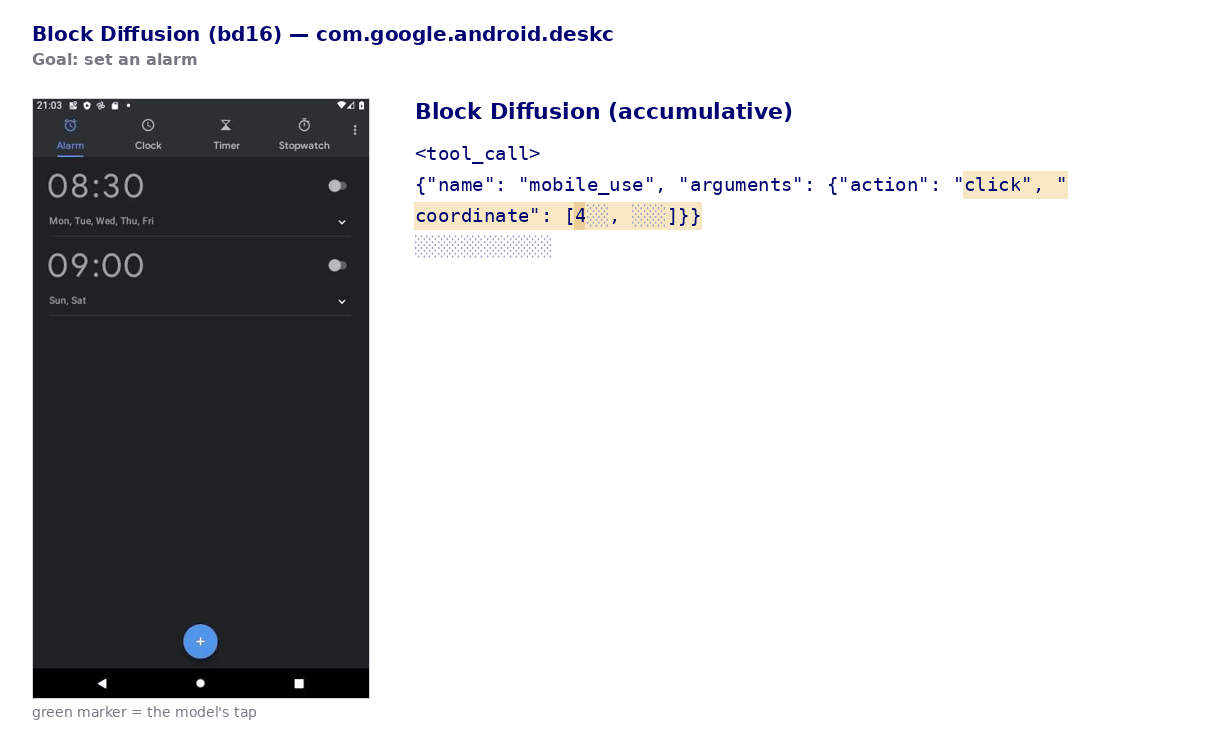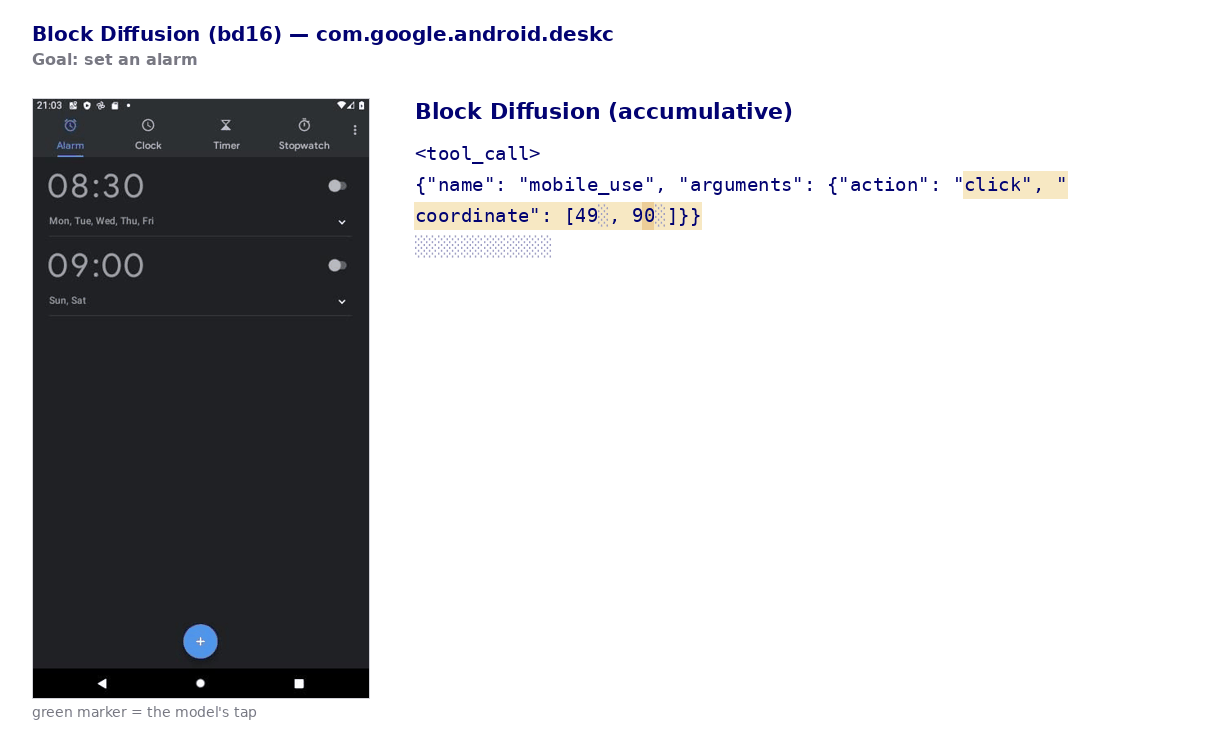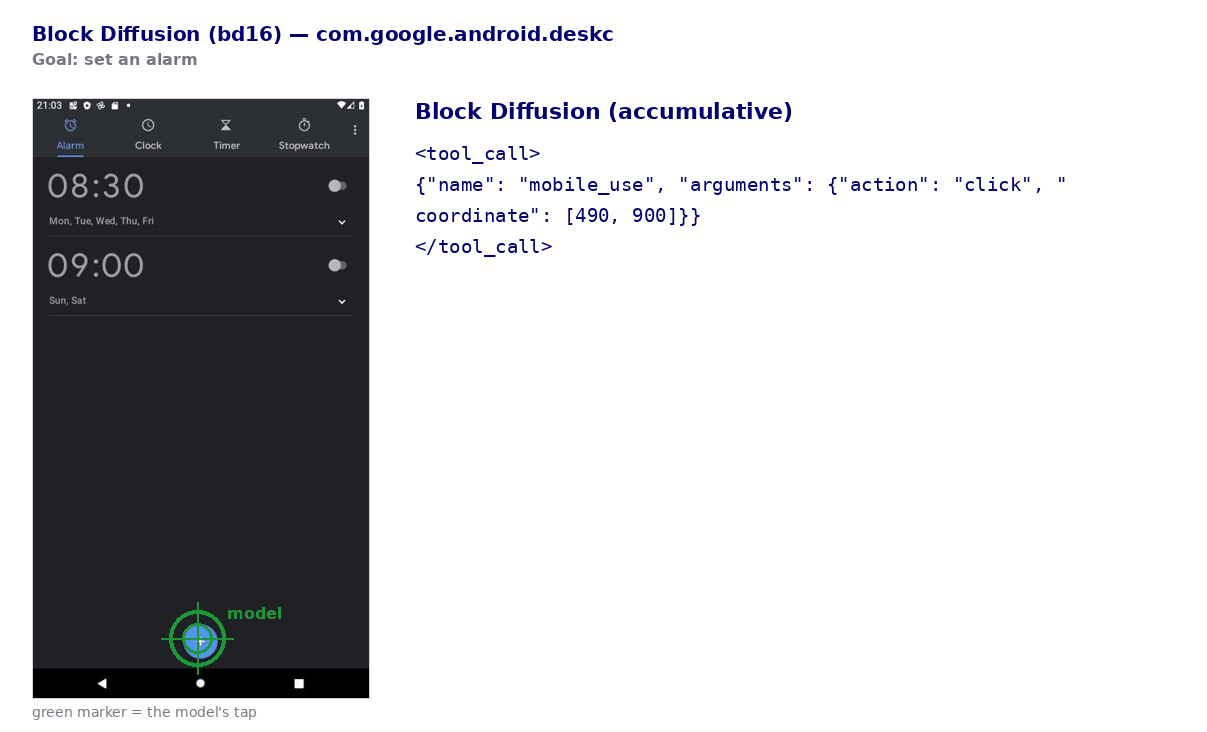
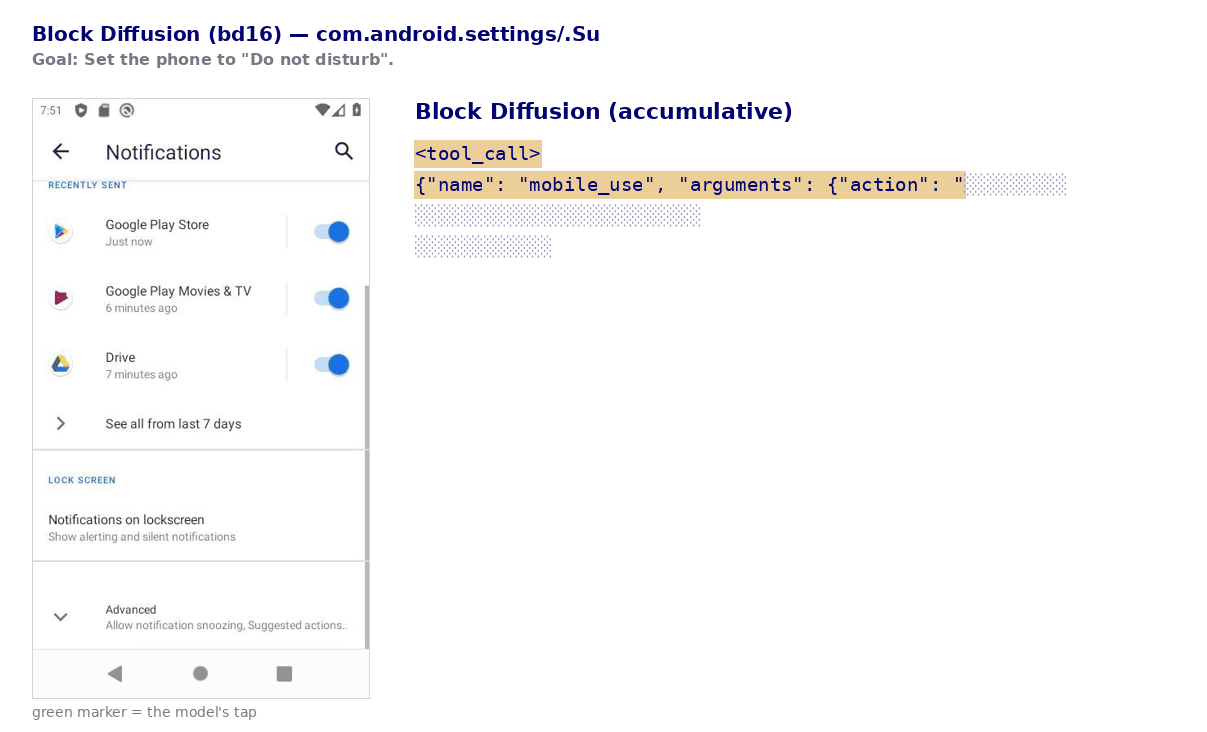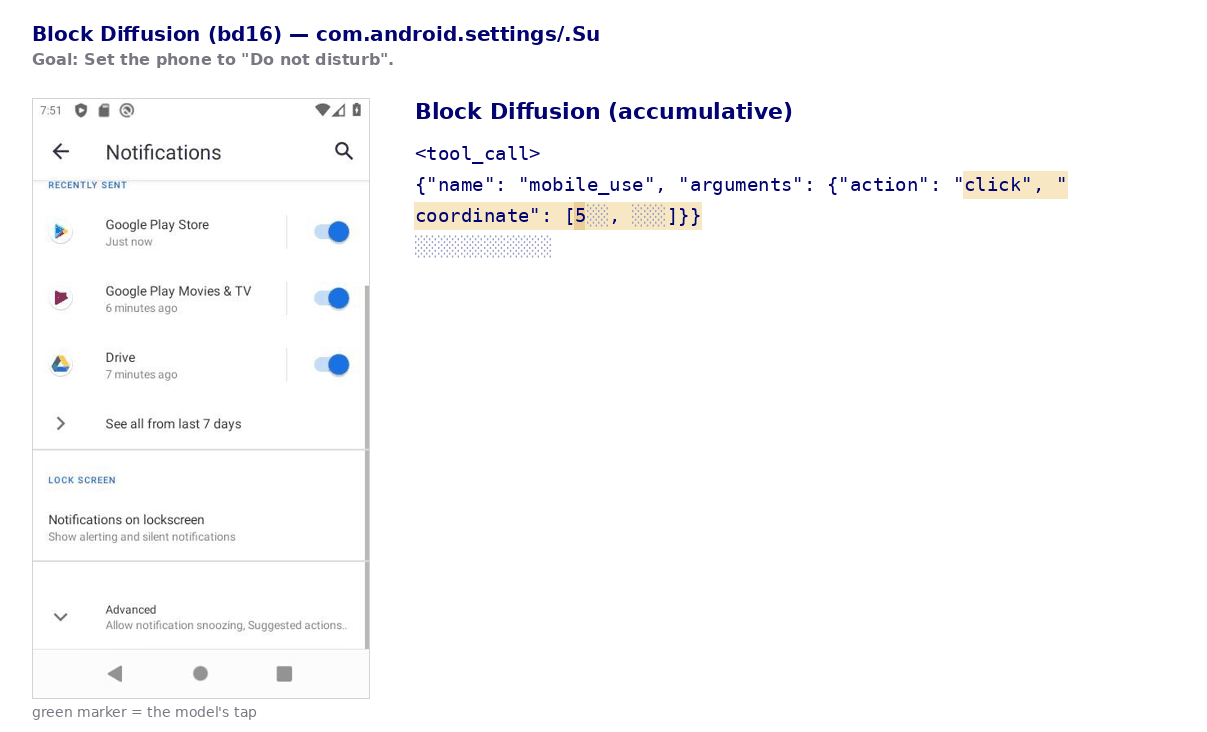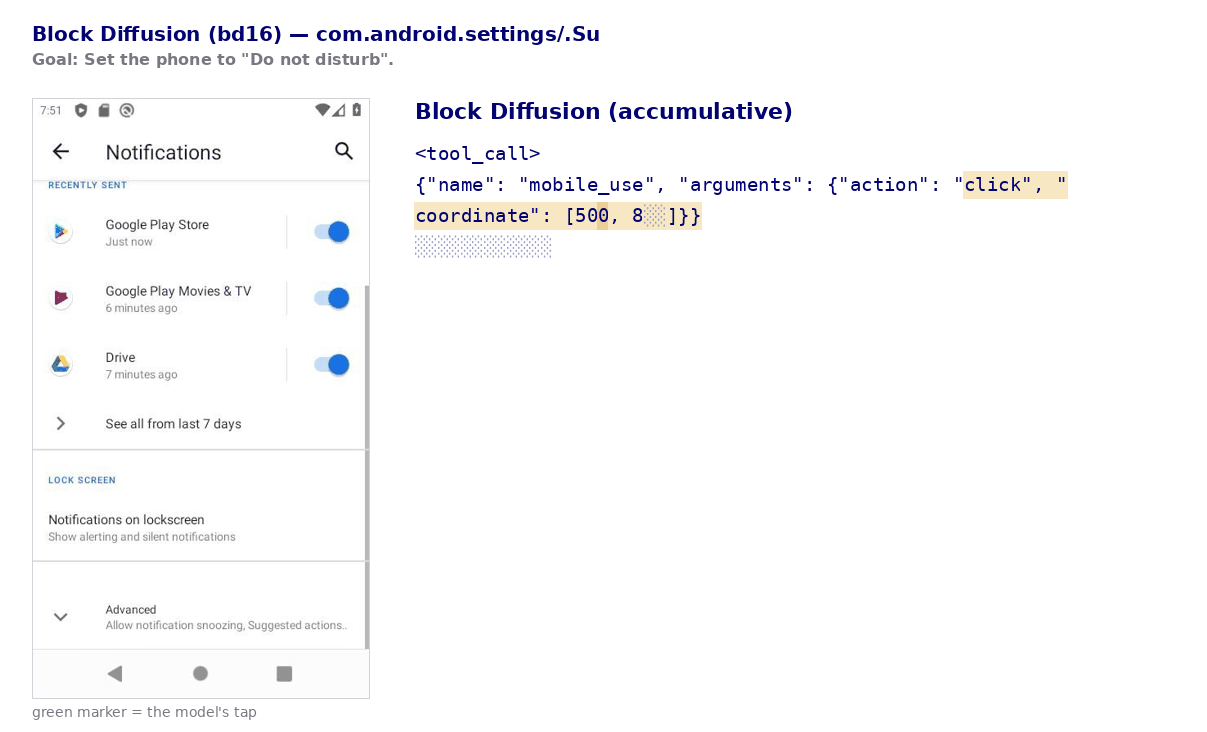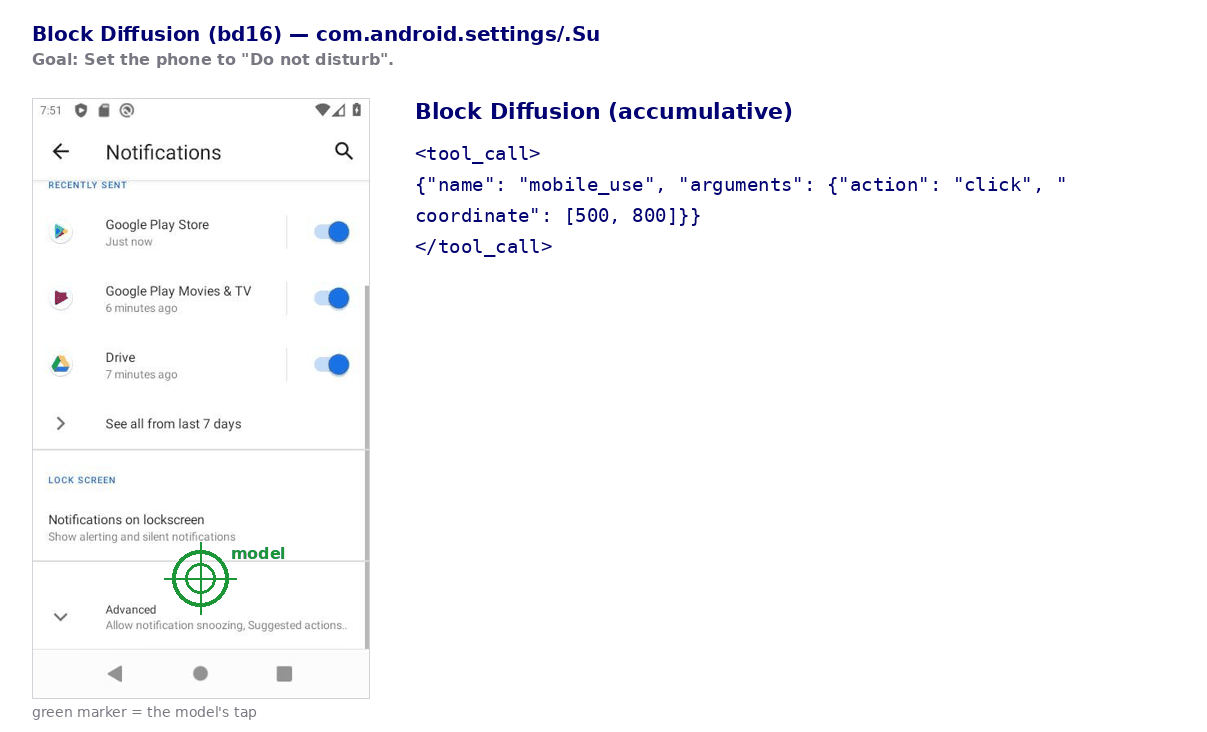
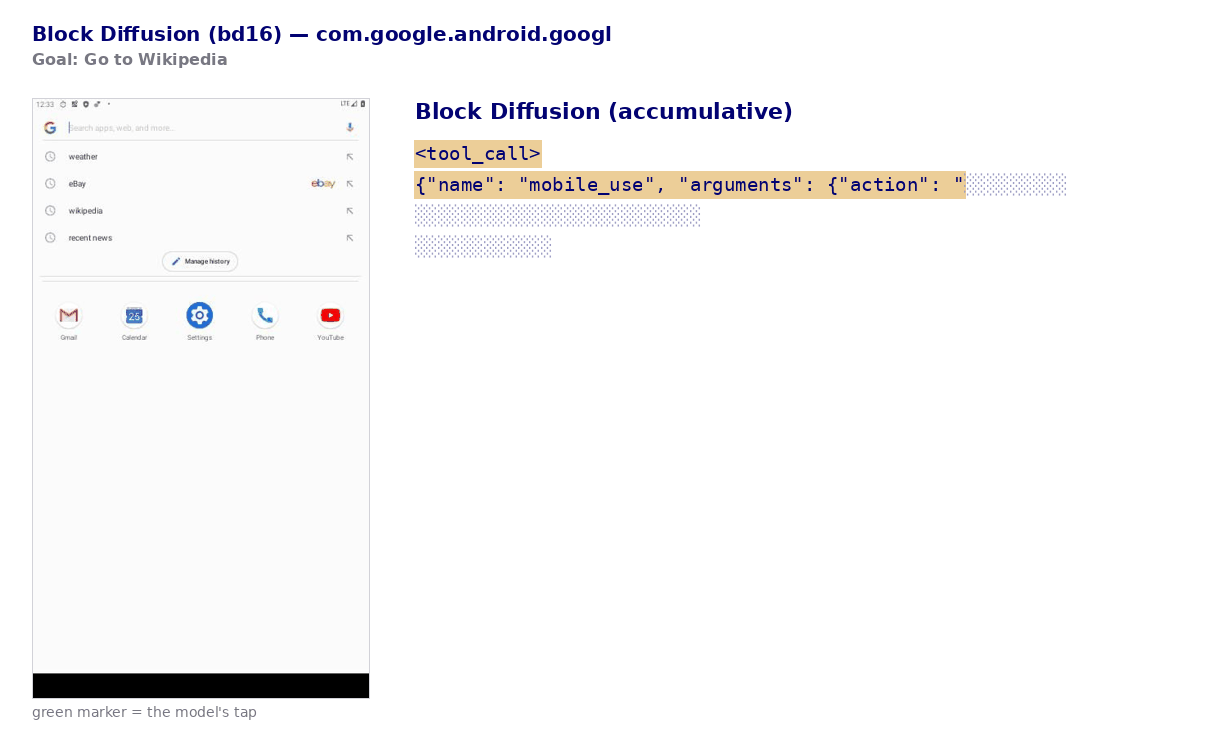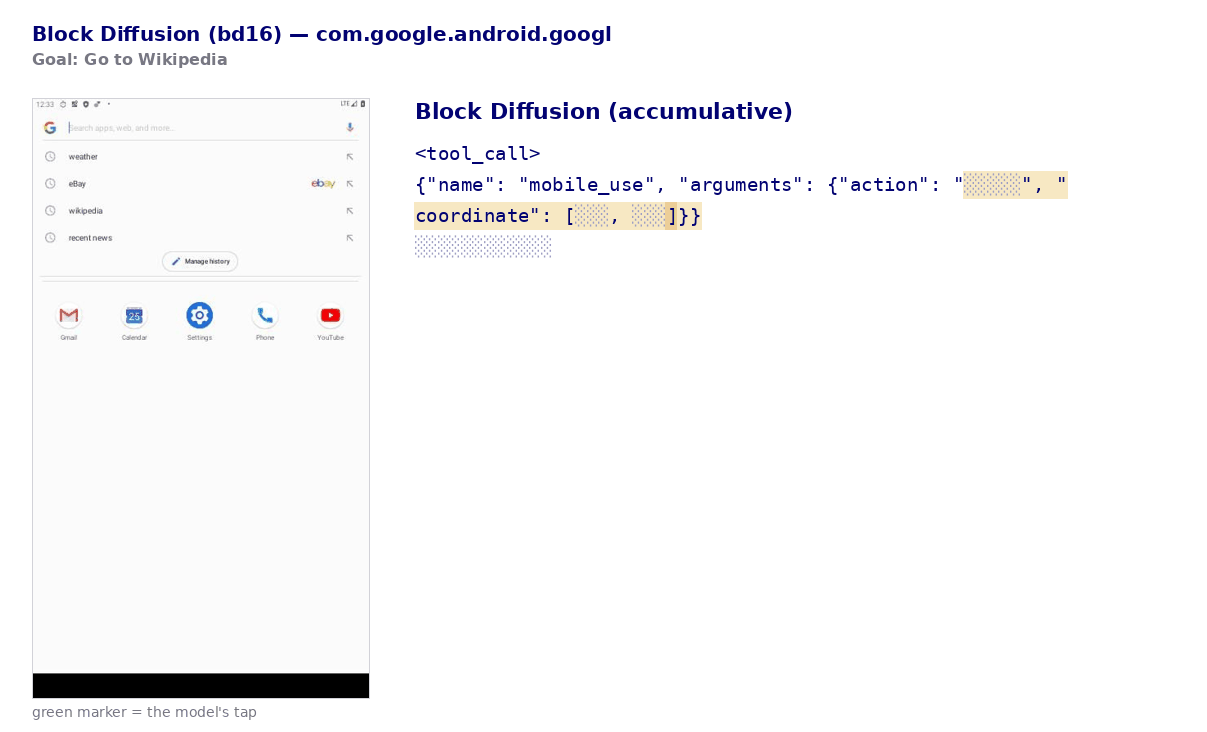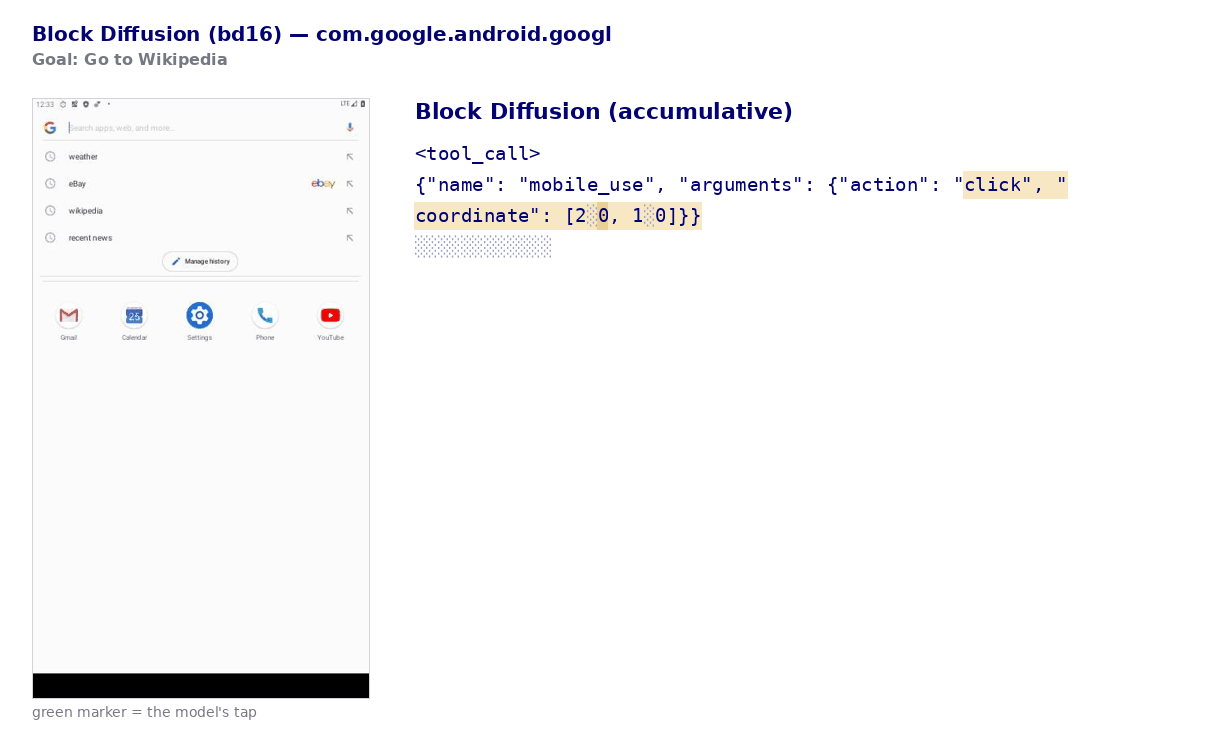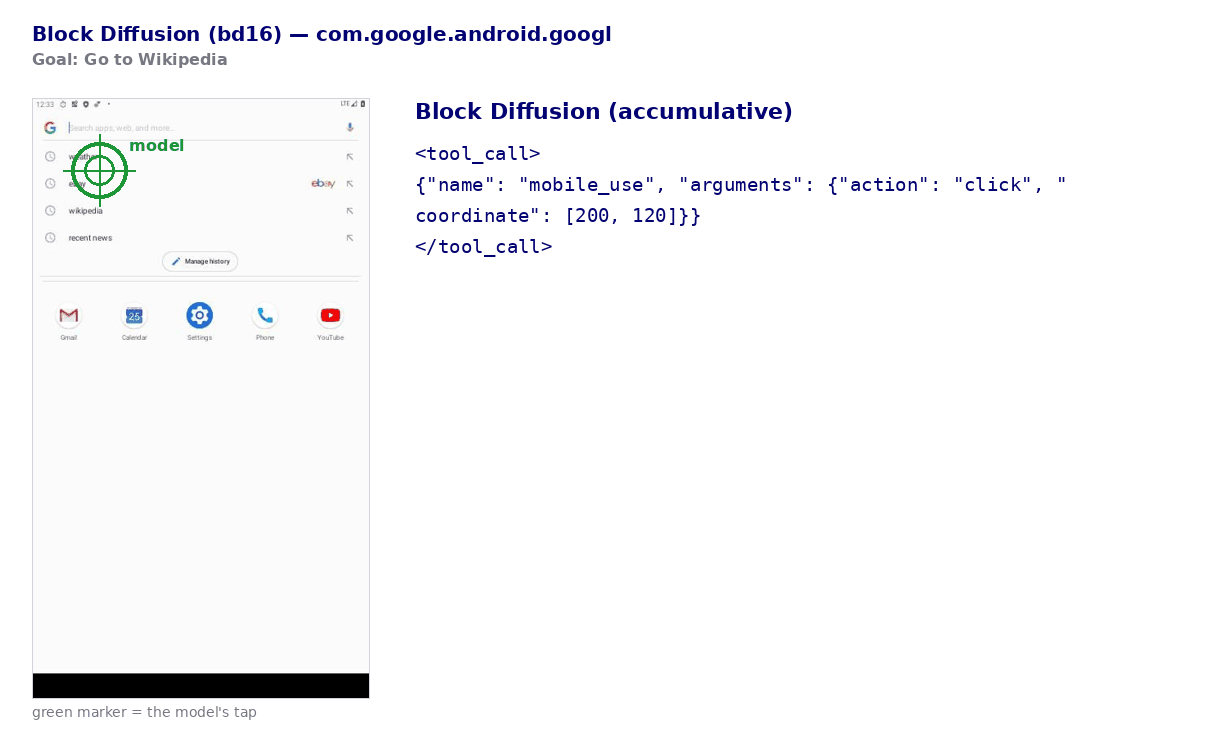
Settings toggles (Bluetooth / Wi-Fi)
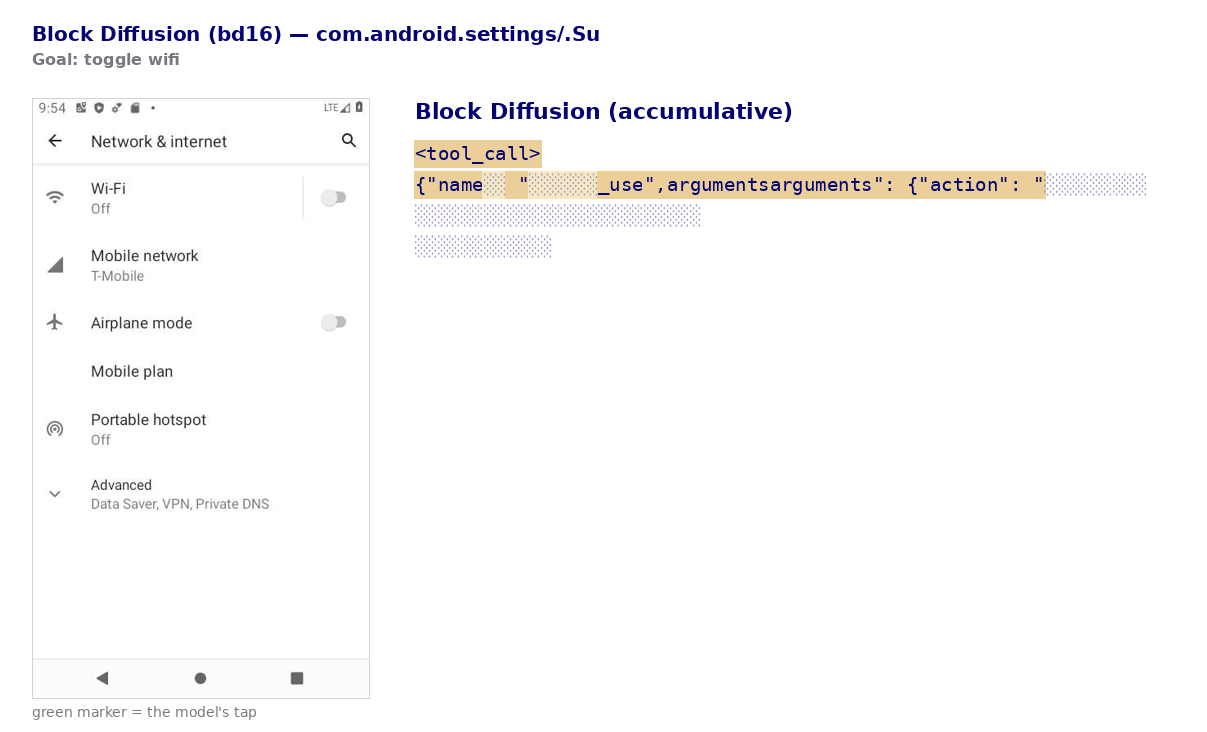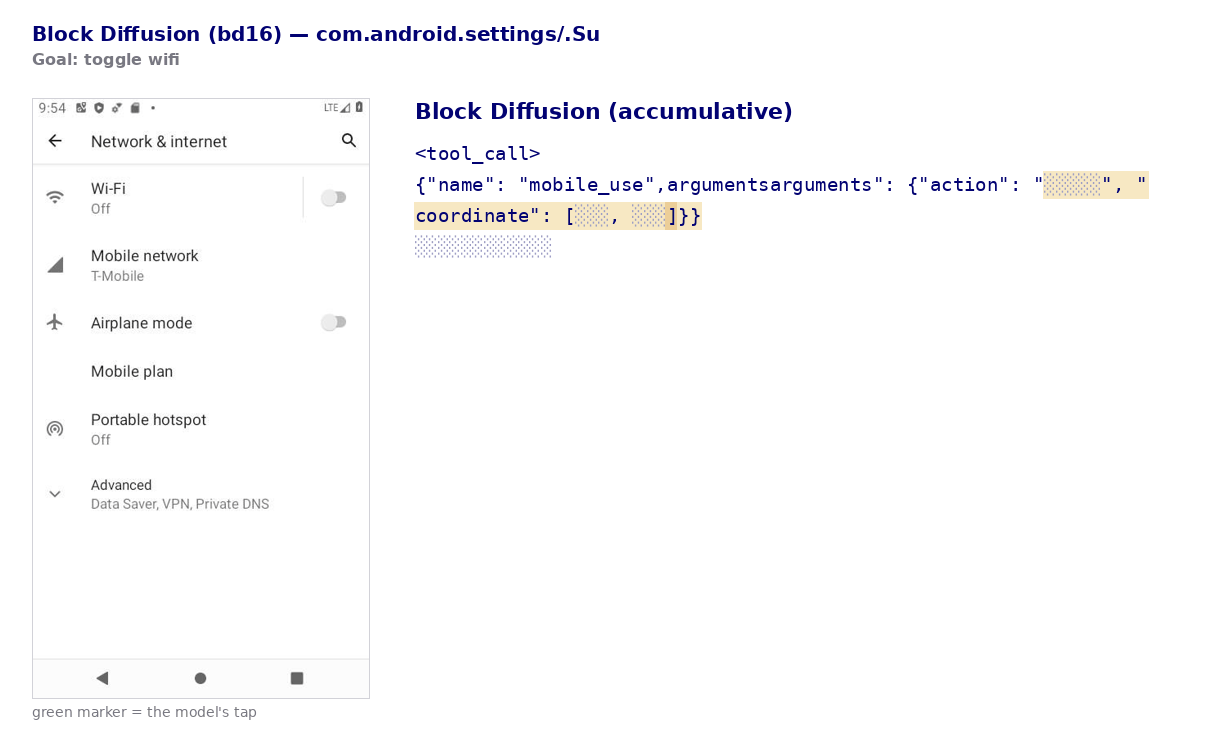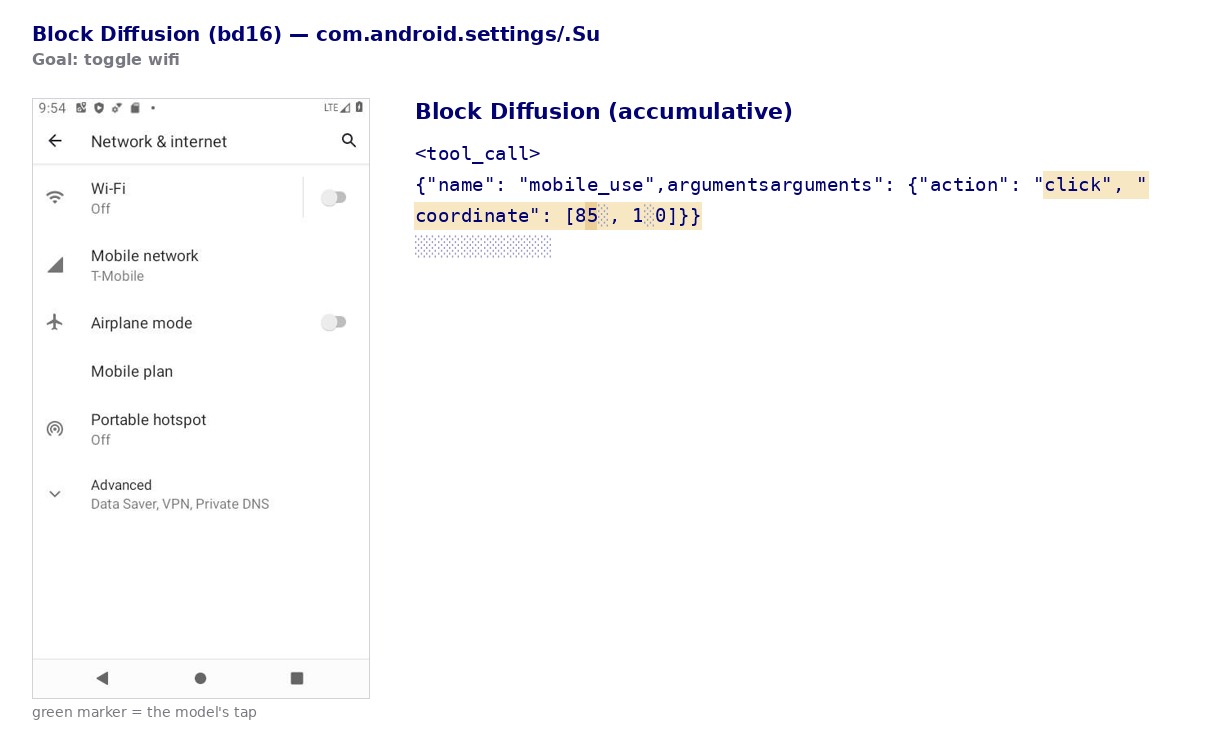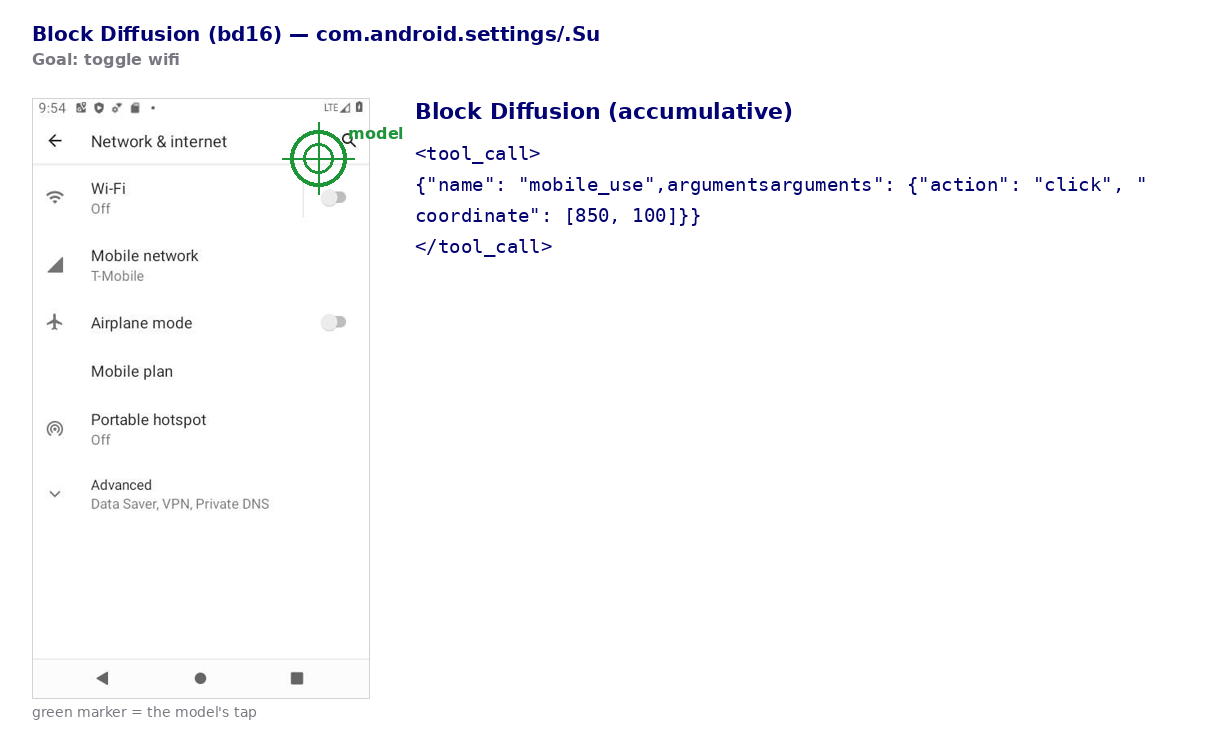
AndroidWorld connectivity / settings tasks. W0 decodes each action as block diffusion and taps the correct control; the green marker is the model's tap landing on the ground-truth target. Click to enlarge.
Multi-step episodes
W0 runs an AndroidWorld task step by step, decoding each action as block diffusion (right). A green marker shows where the model taps at each step, and the task goal is shown on each clip. Click any clip to enlarge.
Team